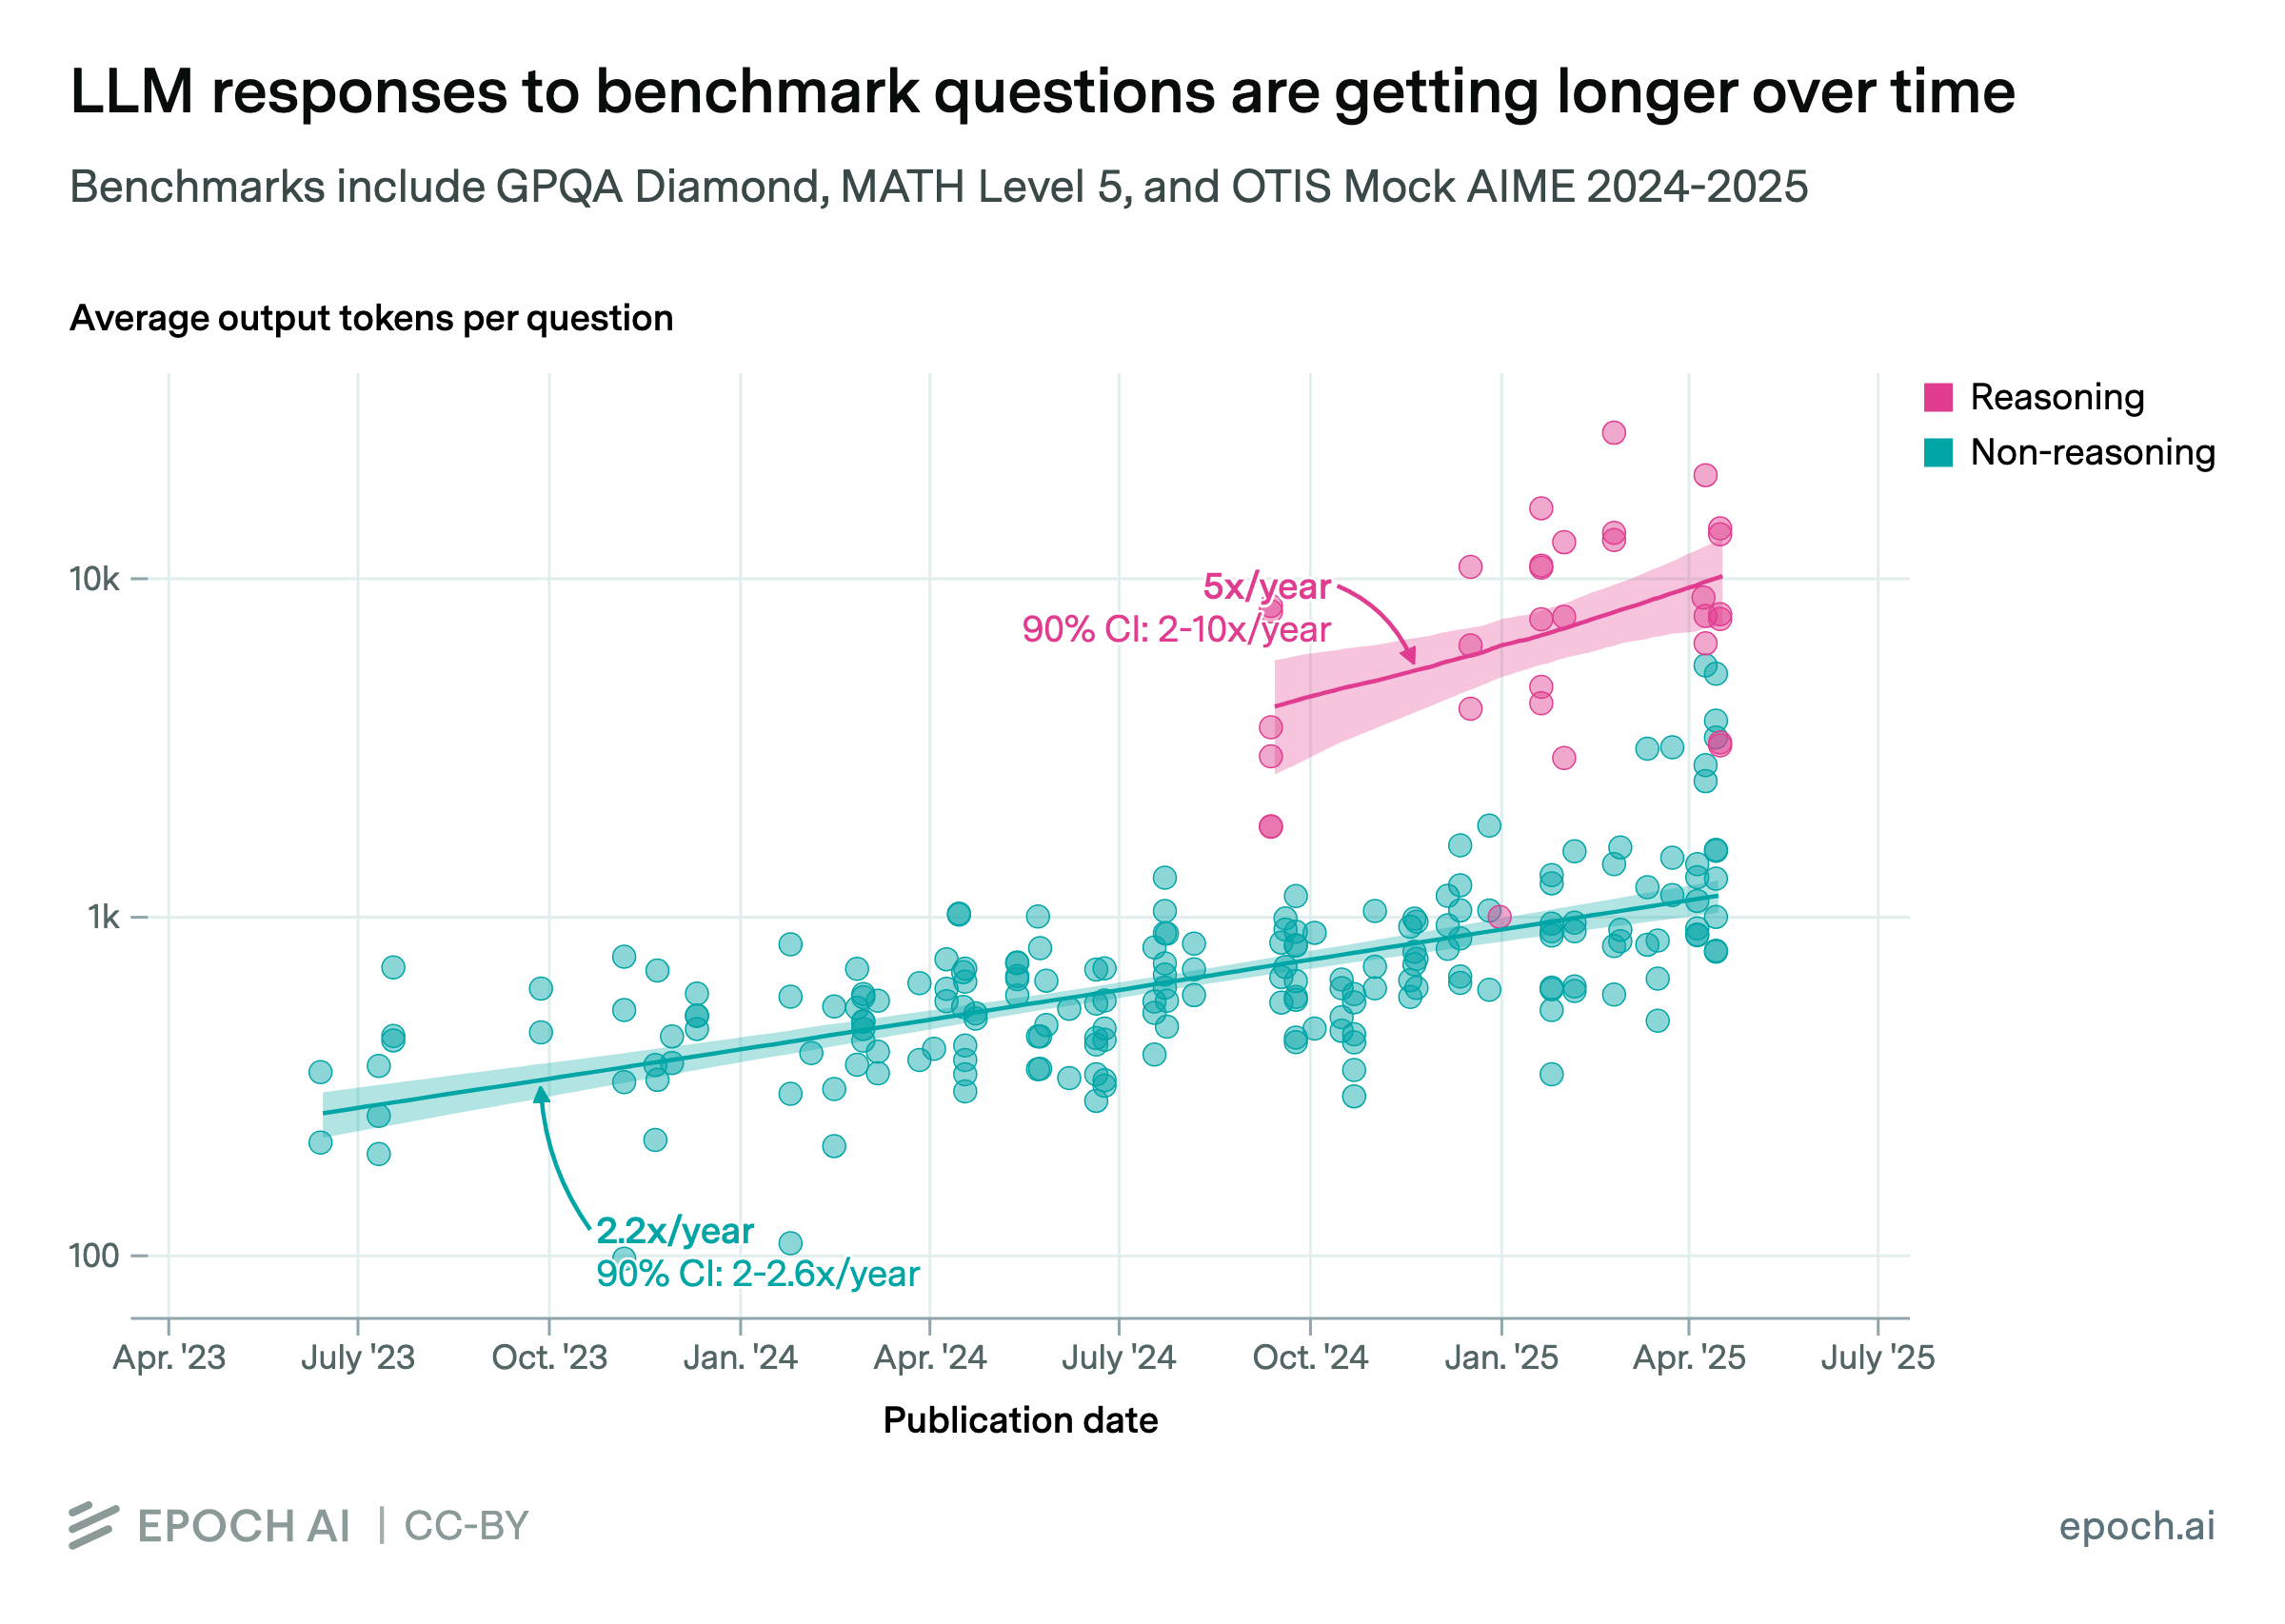
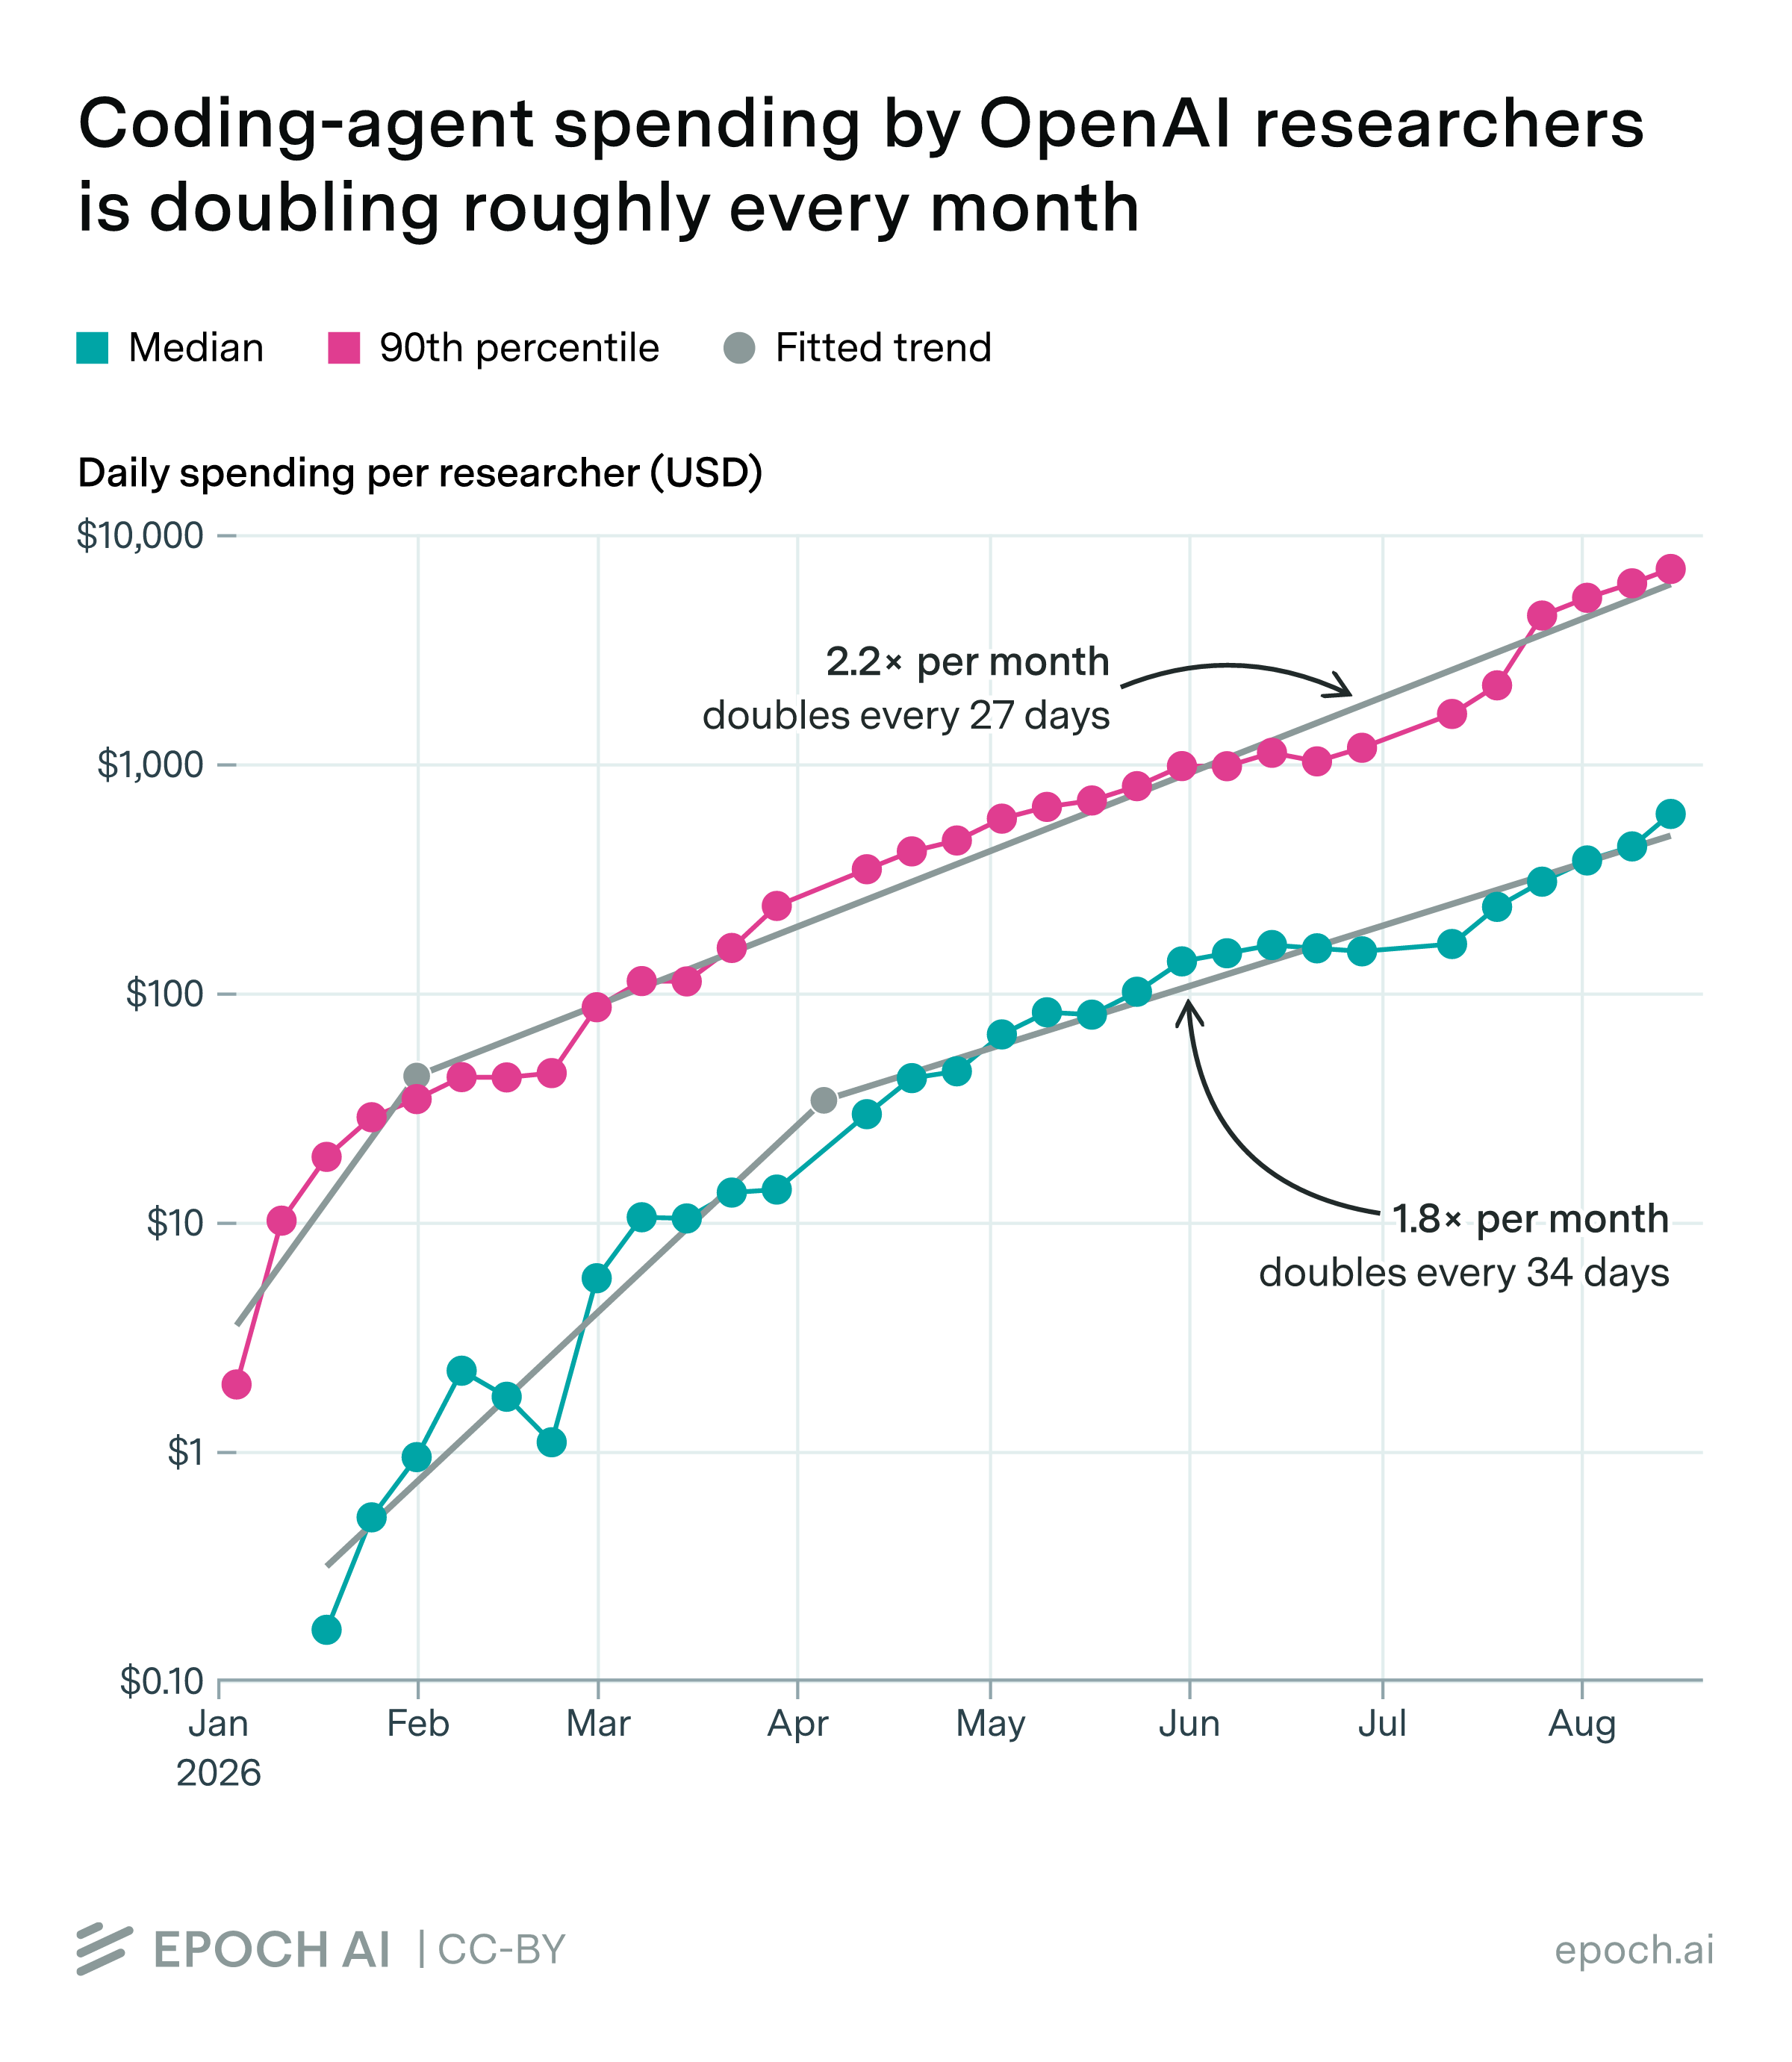
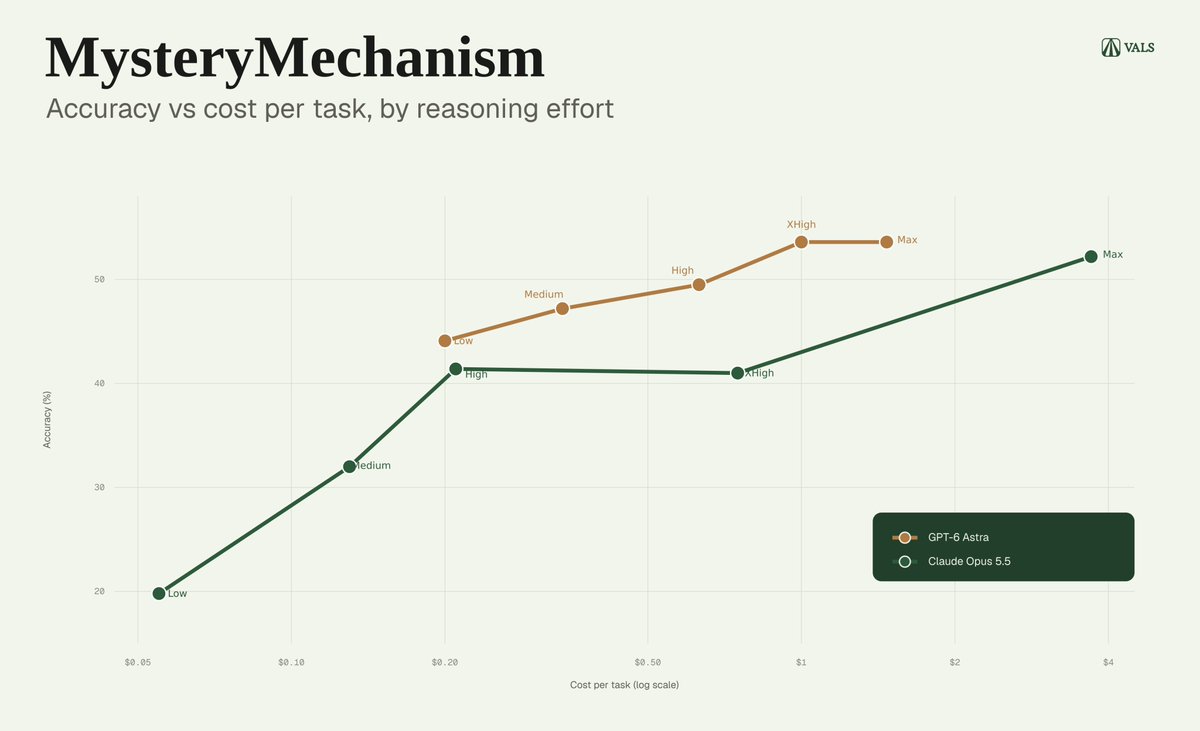
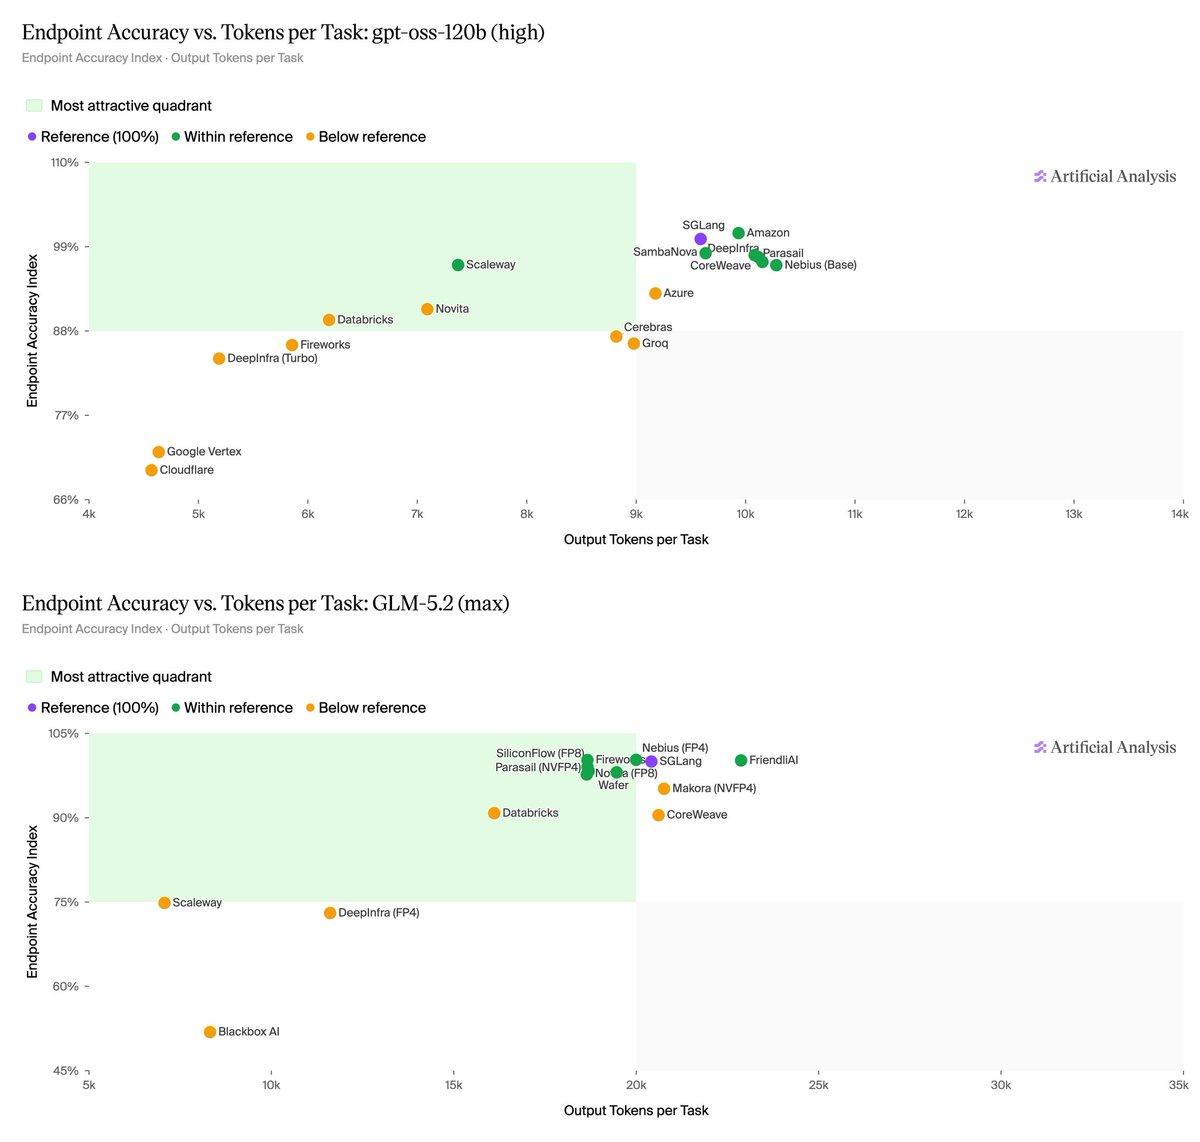
Reasoning models emit about 8x more tokenThe chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.Full definition → per answer and growing fast, so per-task cost and latency rise faster than per-token price suggests.
Terms in this piece · Glossary
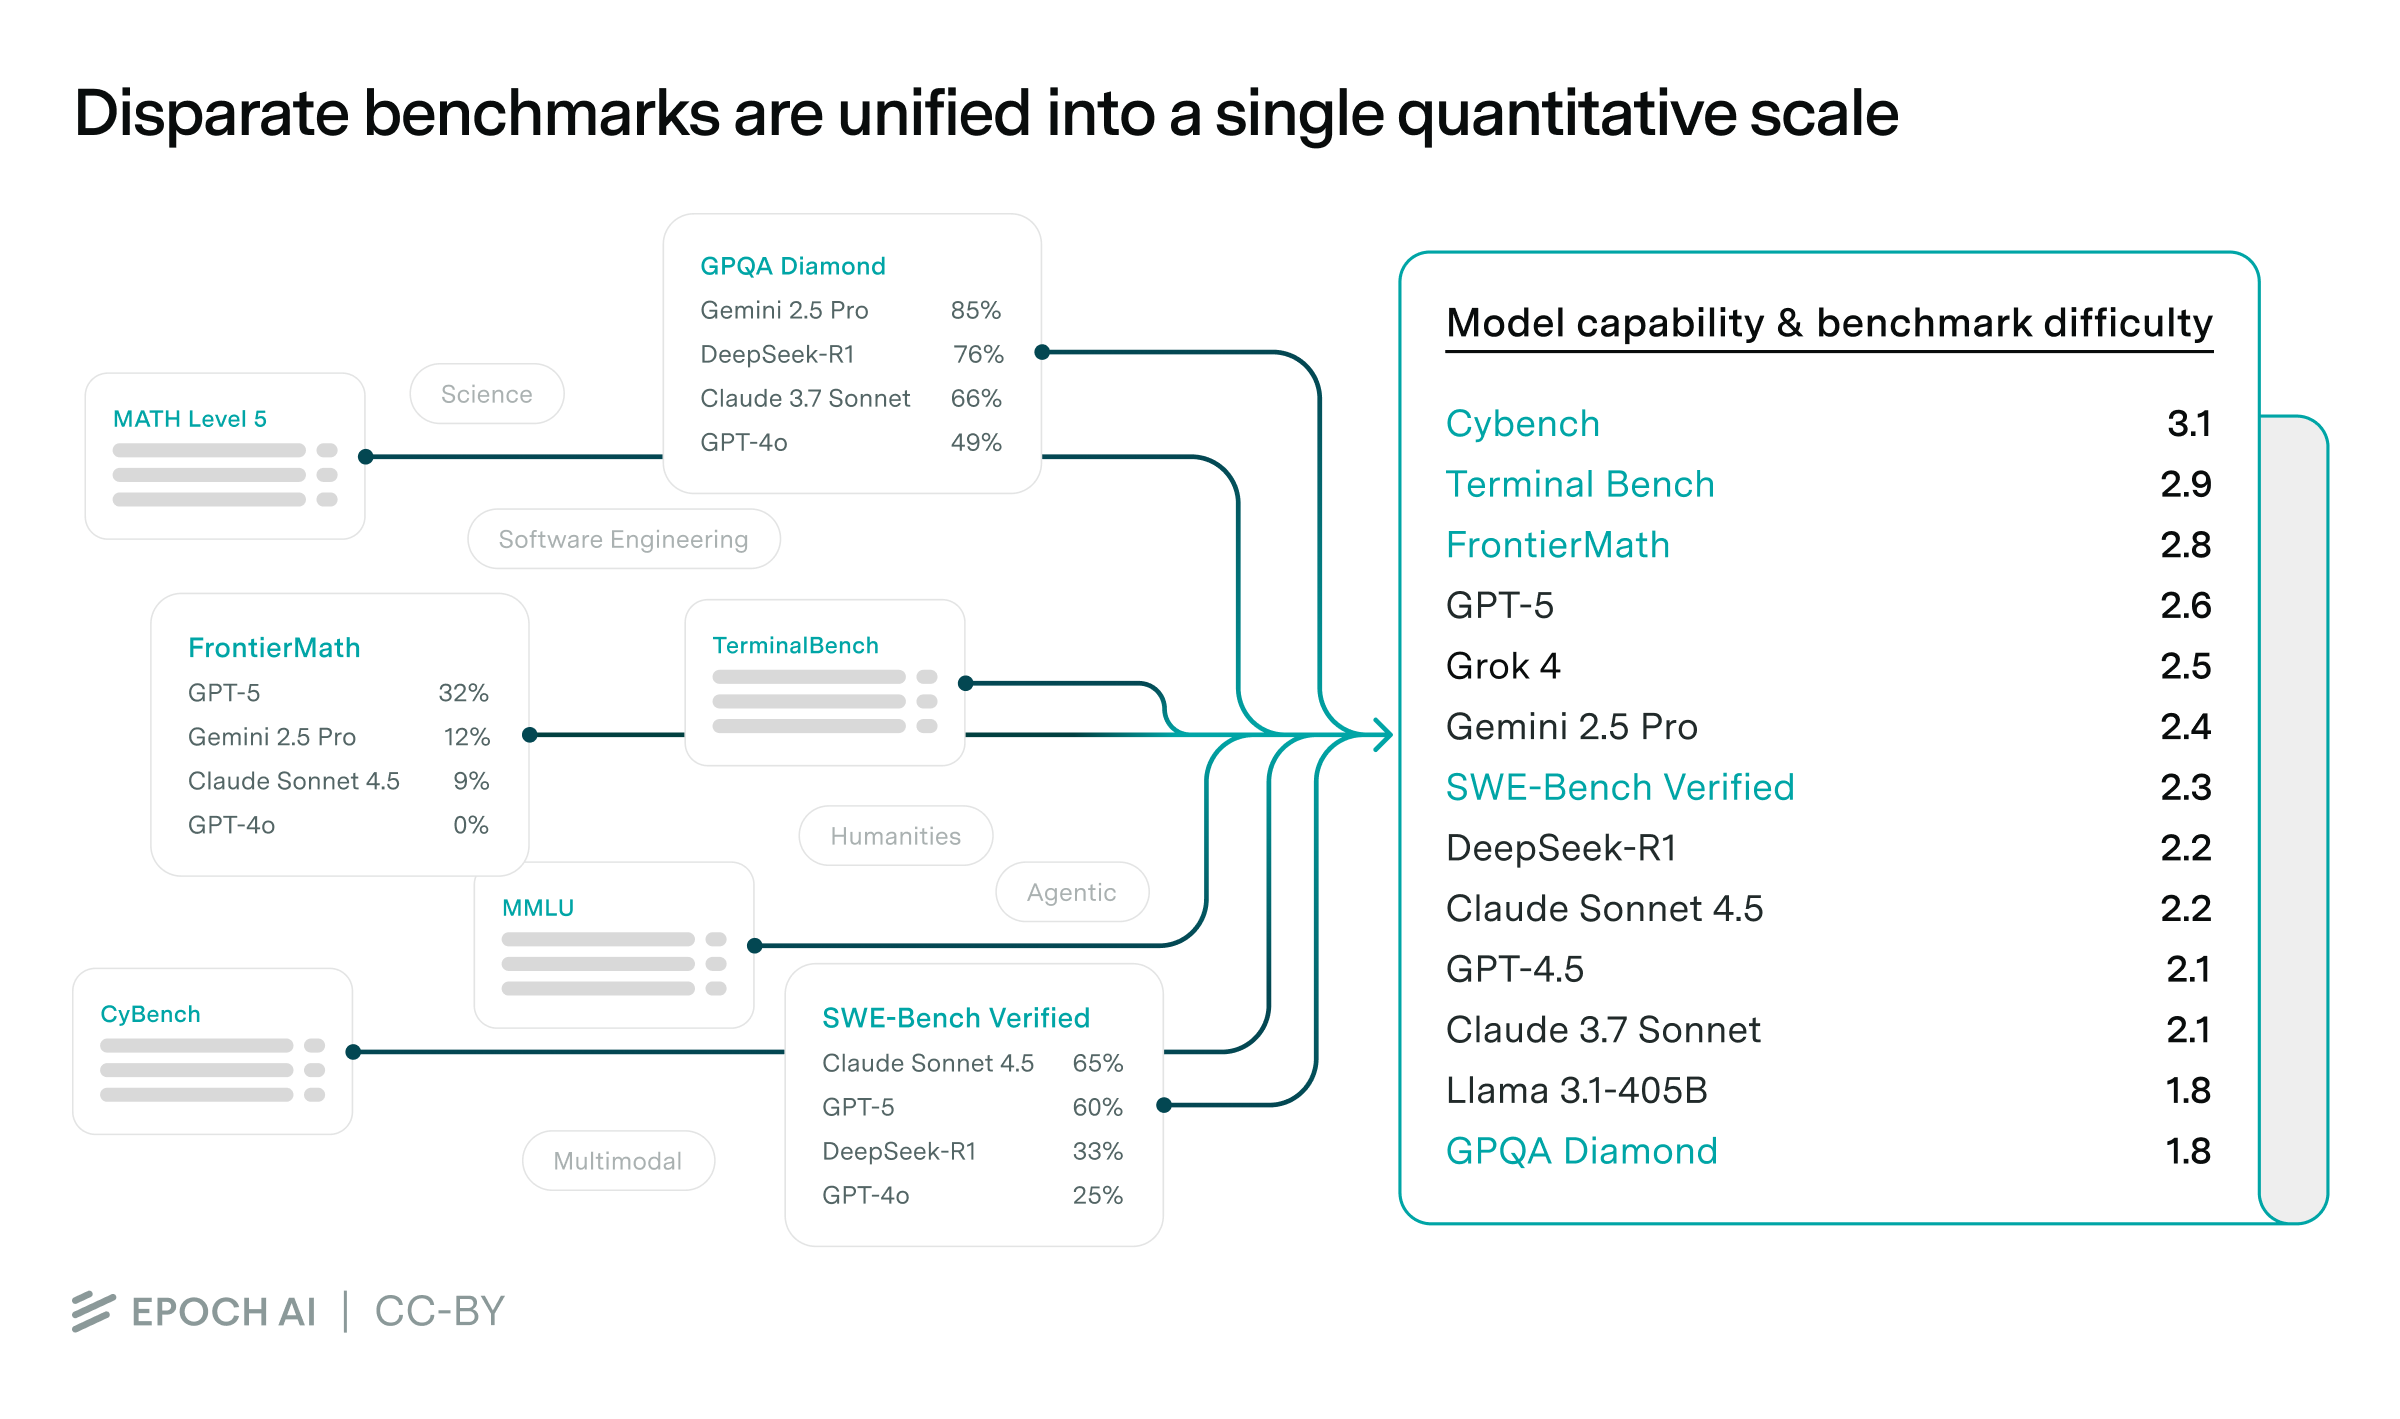
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.