Parsimony – an open-source benchmark for how much code AI models add
Source
parsimony.lasu.dev
Author
lasu
Date
Why it matters
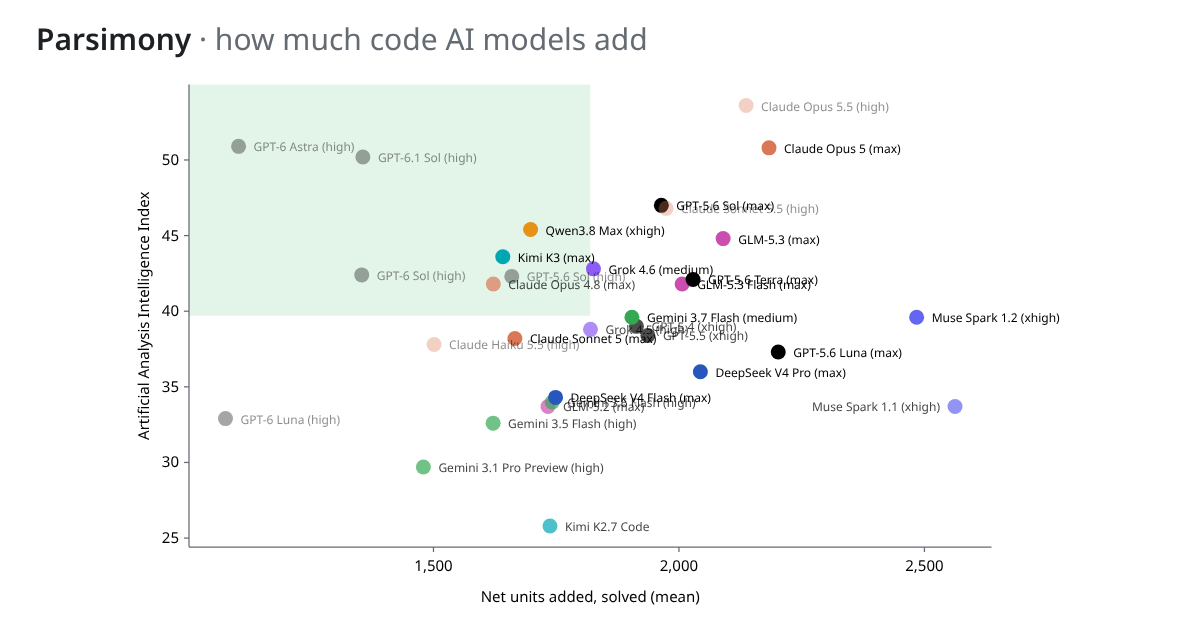
Solve rate ignores how much code a model adds. This counts net syntax units in AI agentAn AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.Full definition → patches, so you can compare how bloated each model's changes are before they land in a long-lived codebase.
Terms in this piece · Glossary
SWE-bench — The standard benchmark for AI coding agents: real GitHub issues from real repositories, scored by whether the agent's patch passes the project's own tests.
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.