TPU Inference Externalization Full Steam Ahead - InferenceX
- Source
- newsletter.semianalysis.com
- Author
- Alec Ibarra
- Date
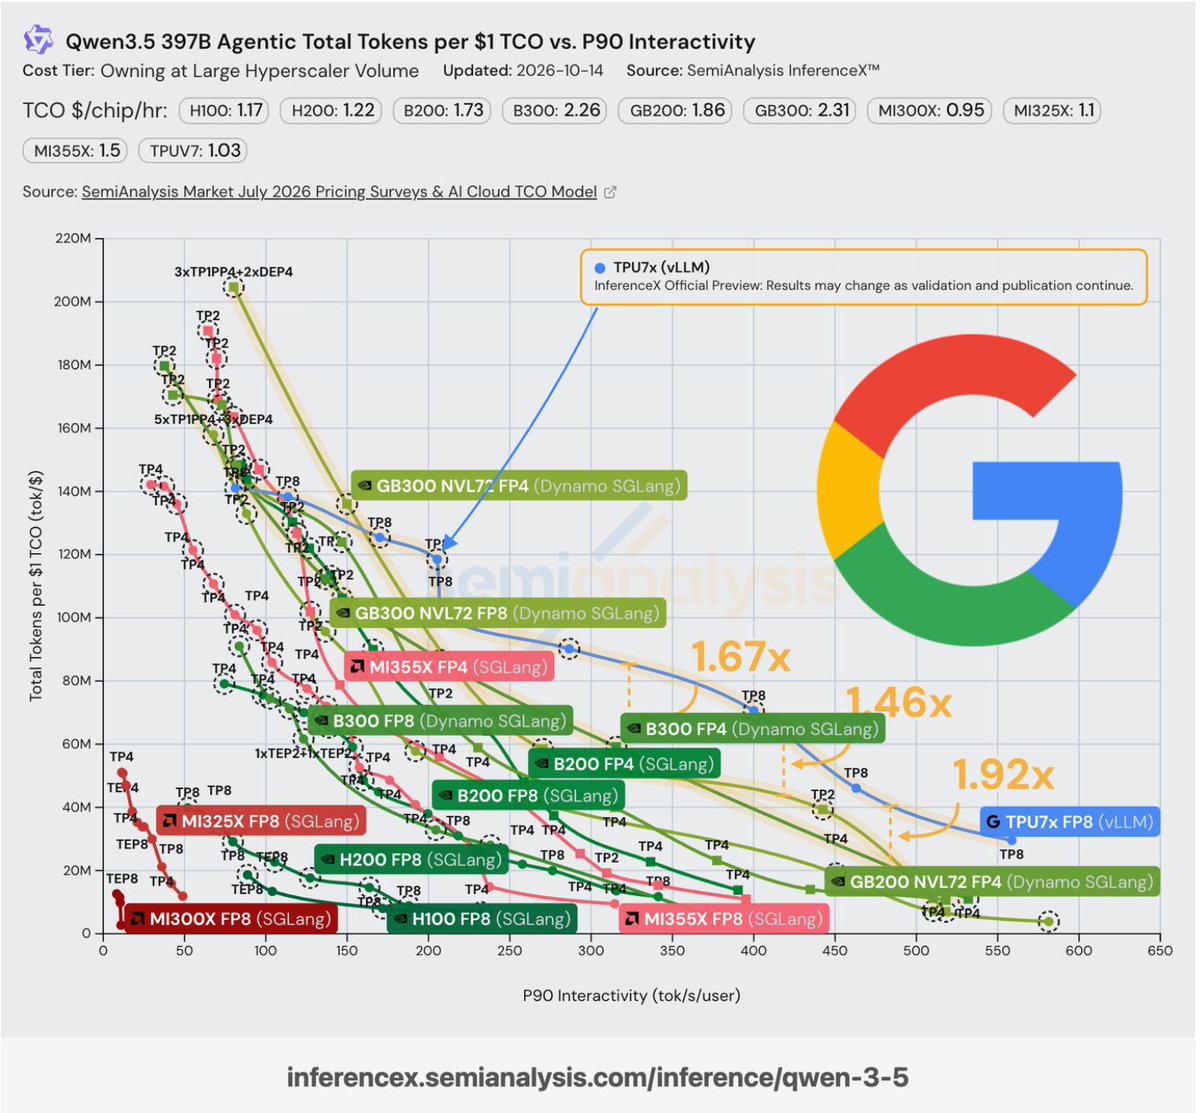
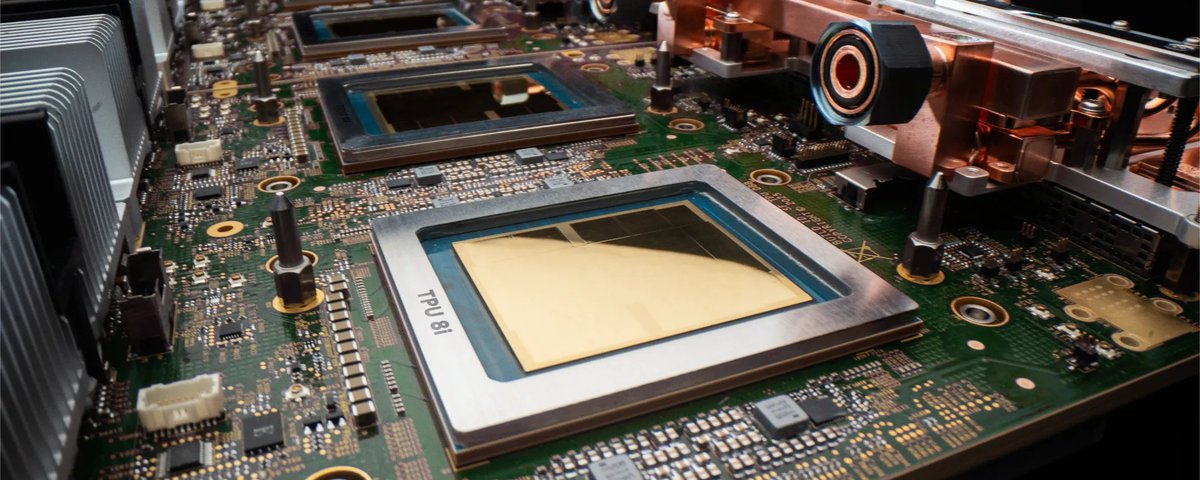
SemiAnalysis published the first independent benchmarks of Google's TPUv7 Ironwood pitted against Nvidia's B200 and B300, and the numbers favor Google by a wide margin: up to 50% better performance-per-dollar on inference workloads. The report goes further than a raw speed comparison, breaking down what Google's internal total cost of ownership looks like against what external customers actually pay to rent TPU capacity, a gap that matters for anyone deciding whether to build on Google's cloud silicon or stick with Nvidia GPUs. The timing lines up with Anthropic's reported push toward using over a million TPUs, which reads less like a hedge and more like a bet that TPU economics now clear the bar for a frontier lab's primary training and inference stack. If the benchmarks hold up under further scrutiny, they weaken the assumption that Nvidia hardware is the default choice for large-scale inference, and give every other lab and cloud buyer a concrete number to push back with in their own hardware negotiations.
Context
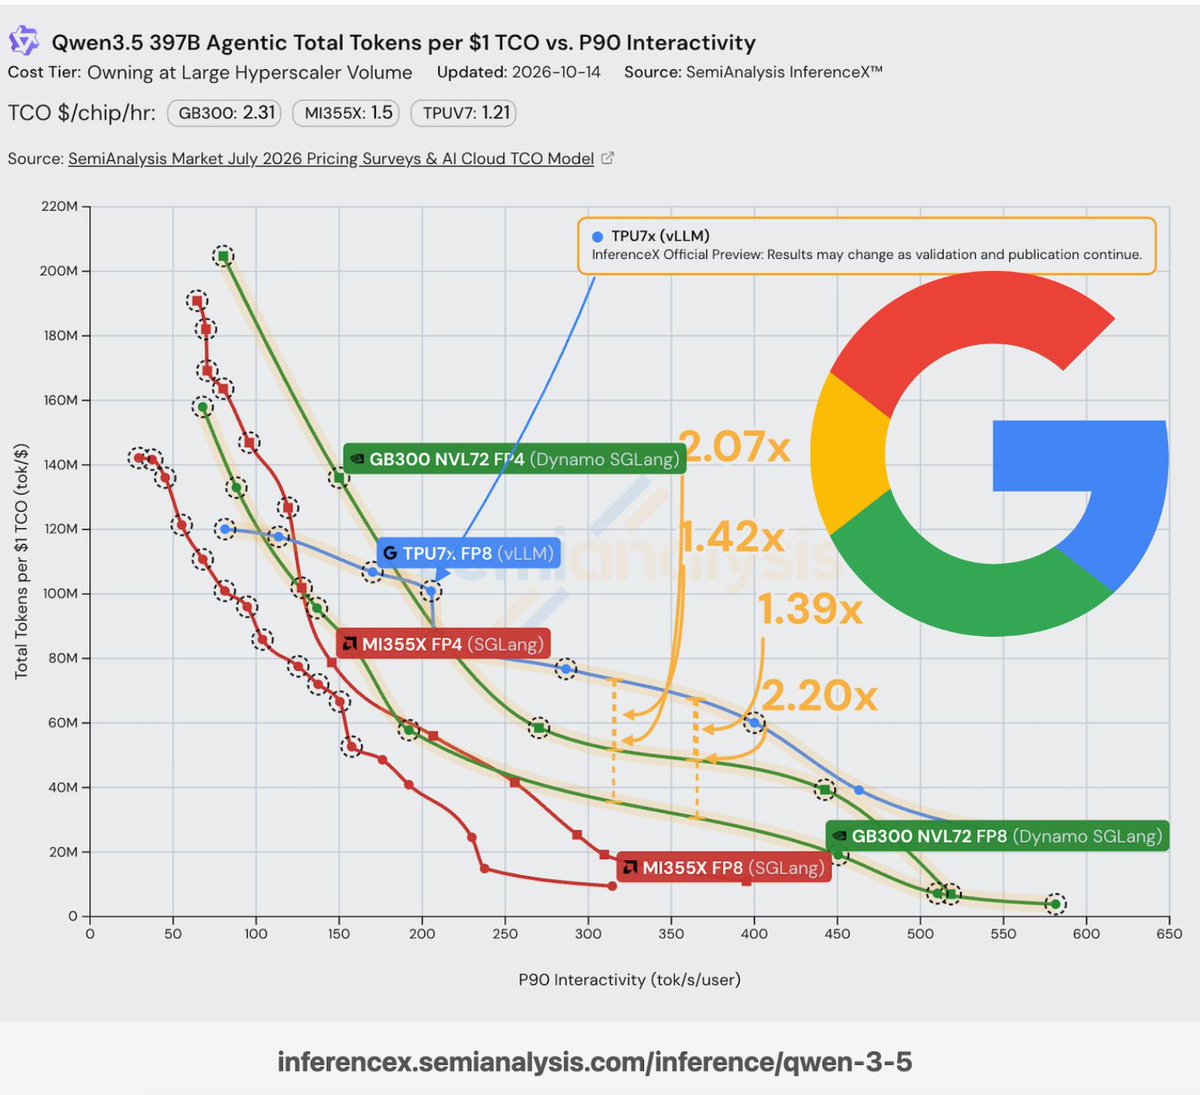
SemiAnalysis reports that Ironwood TPUv7 can offer lower costs even where its raw throughput trails competing GPUs. Its preview comparison used Qwen3.5-397B at the same eight-bit numerical precision. At a generation speed of 100 per second per user, it estimated $0.181 per million total tokens for Ironwood versus $0.222 for NVIDIA's B200, about 19% less. Those economics depend on modeled ownership costs and the tested serving setup. The useful finding is that lower hourly hardware costs can outweigh lower throughput at a specified response-speed target.
Checking sign-in…
Loading comments…