Tencent Hy4 tops CWE-Bench-AA at a fraction of the cost
- Source
- x.com
- Date

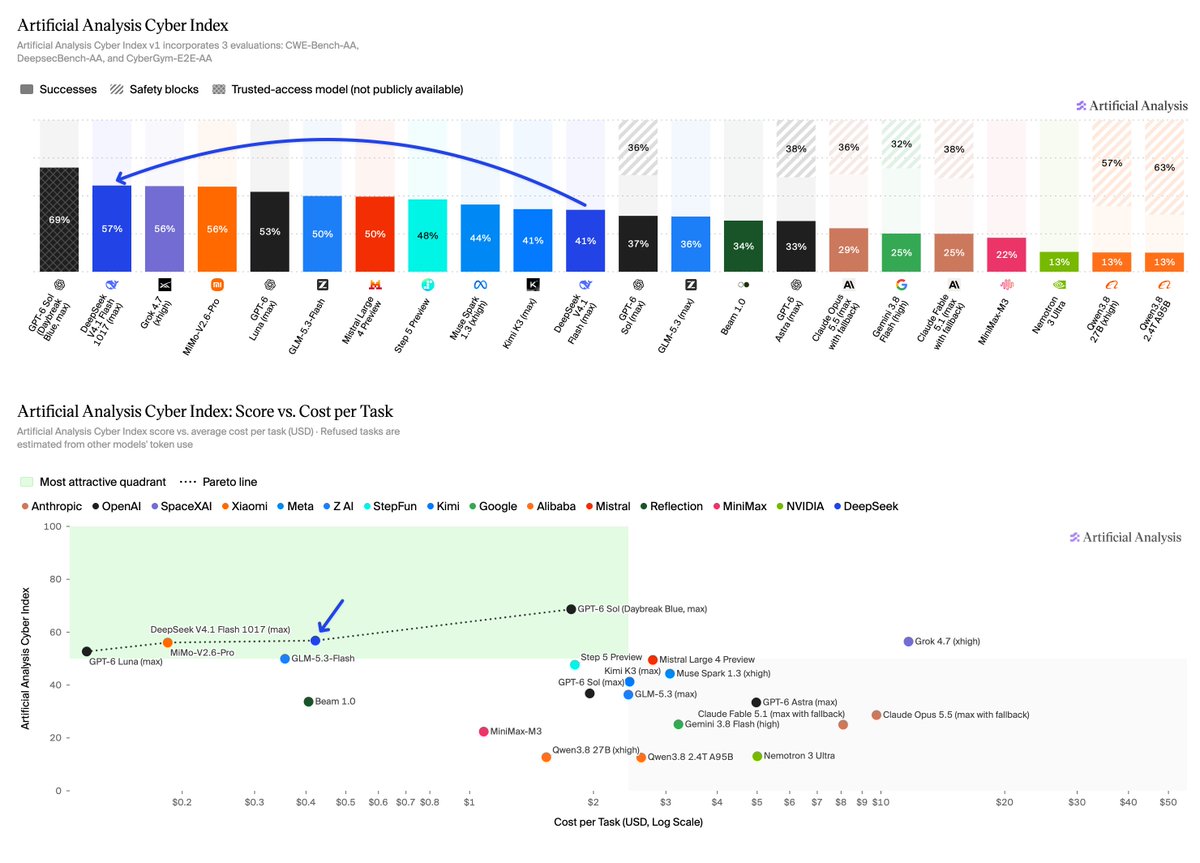
Tencent's Hy4 ranks #3 on the Artificial Analysis Cyber Index and #1 on CWE-Bench-AA @TencentHunyuan's Hy4 scores 58% on the Artificial Analysis Cyber Index, 1 point ahead of DeepSeek V4.1 Flash 1017 (max). It trails Kimi K3.1 Pro (64%) and the trusted-access GPT-6 Sol (Daybreak Blue, max) (69%). API pricing is $0.834/$2.501 per 1M input/output tokens. Key results: ➤ #1 on CWE-Bench-AA (76%). Hy4 leads DeepSeek V4.1 Flash 1017 (max) by 6 points on our implementation of @CollinearAI's CWE-bench v1, which tests agents' ability to find and fix real software vulnerabilities ➤ Strong capability for the cost. At $0.92 per task, Hy4 sits on the Capability vs. Cost Pareto frontier. It scores 2 points above Grok 4.7 (xhigh) at 1/11th the cost and 1 point above DeepSeek V4.1 Flash 1017 (max) at 2x the cost ➤ Fewer output tokens than peers. Hy4 uses 64k output tokens per task: 43% fewer than DeepSeek V4.1 Flash 1017 (max) and 37% fewer than Grok 4.7 (xhigh), but 49% more than Kimi K3.1 Pro and 56% more than GPT-6 Sol (Daybreak Blue, max)

Context
Tencent's Hy4 does better on security tasks than its general ranking would suggest. In Artificial Analysis's testing it places first on CWE-Bench-AA with 76%, 6 points ahead of DeepSeek V4.1 Flash 1017 (max) (Artificial Analysis on X). CWE-Bench-AA is Artificial Analysis's own implementation of Collinear AI's CWE-bench v1, which tests whether an can find and fix real software vulnerabilities. On the broader Artificial Analysis Cyber Index, Hy4 scores 58% and ranks third: 1 point ahead of DeepSeek V4.1 Flash, behind Kimi K3.1 Pro at 64% and GPT-6 Sol in a trusted-access configuration (Daybreak Blue, max) at 69%.
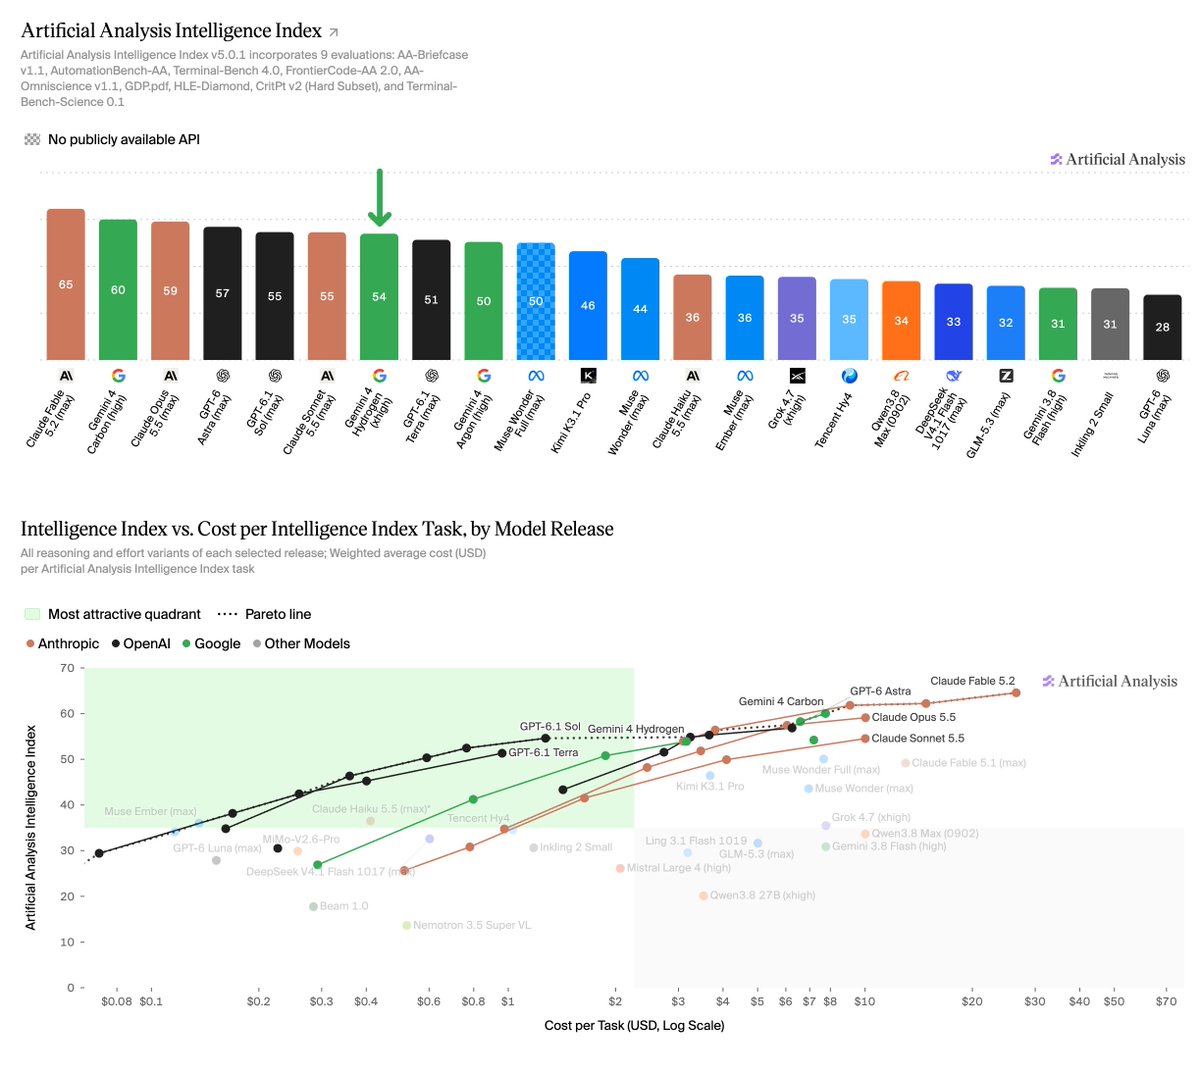
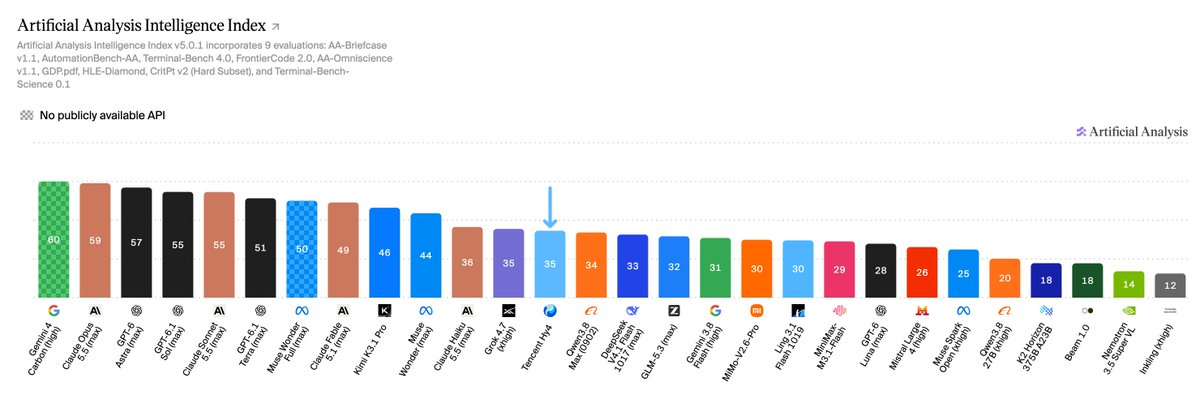
The contrast with the general results is the useful part. A week earlier, Artificial Analysis put Hy4 at 35 on its Intelligence Index, level with Grok 4.7 (xhigh) and well behind Kimi K3.1 Pro's 46, and measured an 89% rate on its AA-Omniscience knowledge test (earlier benchmark post). On vulnerability finding and fixing, the same model now leads the field that Artificial Analysis tested.
Cost is the other half of the claim. Hy4 costs $0.92 per task, which puts it on Artificial Analysis's capability versus cost Pareto frontier, meaning no tested model scores higher for less money. It scores 2 points above Grok 4.7 (xhigh) at one eleventh of the cost, and 1 point above DeepSeek V4.1 Flash, which costs half as much. Hy4 also used fewer output than some of these models: 64k per task, 43% fewer than DeepSeek V4.1 Flash and 37% fewer than Grok 4.7, but 49% more than Kimi K3.1 Pro and 56% more than GPT-6 Sol. Its API price is $0.834 per million input tokens and $2.501 per million output tokens. The post's chart was not read, so per-task costs for Kimi and GPT-6 Sol are not given here.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- hallucination — When a model states something false with full confidence — inventing facts, citations, or APIs that don't exist.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
Checking sign-in…
Loading comments…