SOV-Transcribe-1 becomes the top open-weights speech-to-text model
- Source
- x.com
- Date

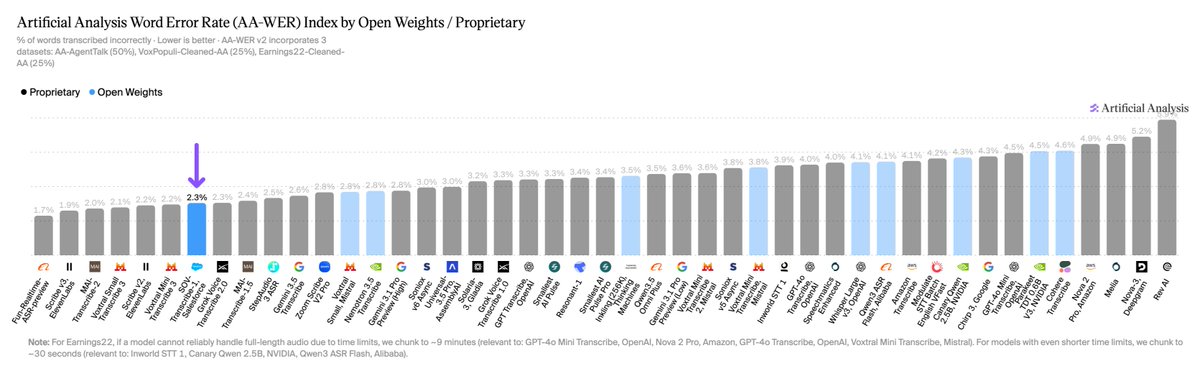
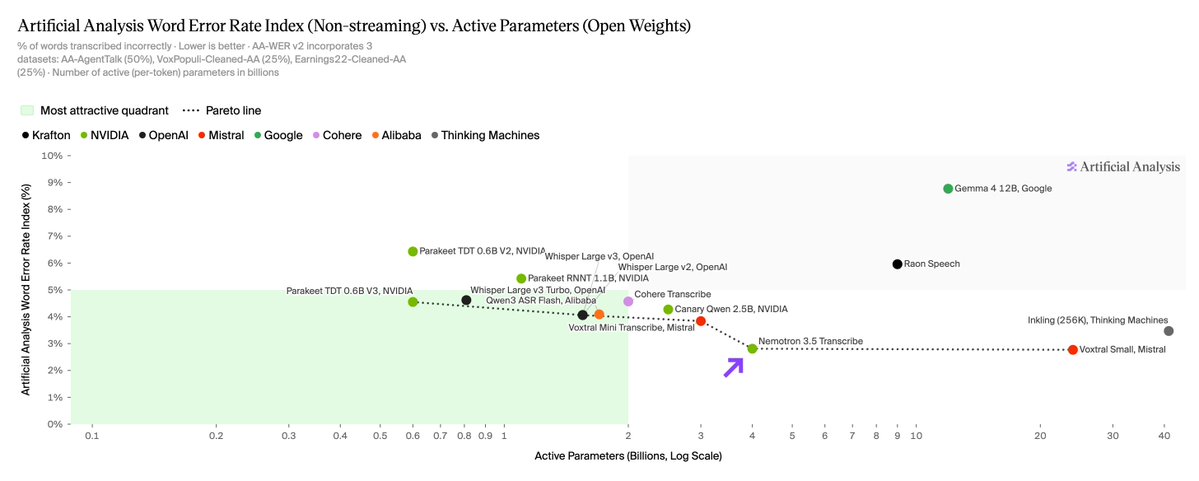
SOV-Transcribe-1 is the new #1 open weights Speech to Text model, scoring 2.3% on the AA-WER Index with 4.6B active parameters. It ranks #7 of 44 models overall, including proprietary models. Congratulations to @salesforce and the Missionforce Sovereign AI team on the release! 🧵
Context
SOV-Transcribe-1 is now the most accurate speech-to-text model with on Artificial Analysis's leaderboard. It scores 2.3% on the AA-WER Index and ranks 7th of 44 models when proprietary ones are included (Artificial Analysis on X). WER is word error rate, the share of words a model transcribes wrongly, so lower is better. Open weights means the model files can be downloaded and run on someone's own hardware. Salesforce's model card releases it under the Apache 2.0 license and says developers and enterprises can deploy and adapt it on their own infrastructure, keeping audio data and transcription behavior under their control (model card).
The post's figure of 4.6 billion active parameters needs the model card to make sense. The model has 26.6 billion parameters in total, but it is a design: a Whisper large-v3 audio encoder feeds a Gemma 4 26B A4B language model that routes each token through only part of its network, so only 4.6 billion parameters, counting the audio encoder, are active. It is built for non- transcription, meaning recorded audio rather than live speech, with clips of up to 30 minutes tested, and it covers English, French, German, Spanish, Italian, Portuguese and Dutch. Because the transcriber is a language model, instructions can ask for verbatim or cleaned-up text and supply names or domain terms to listen for. A separate small draft model, SOV-Transcribe-1-DFlash, speeds up decoding by proposing tokens for the main model to check, which the card says makes a single request roughly two to three times faster.
Artificial Analysis marked the post as the start of a thread, but only the first post and not its chart were read, so this explanation has no speed or price comparison. For scale, in September Artificial Analysis reported StepAudio 3 ASR at 1.7% as the top non-streaming model on the same index (earlier leaderboard post); the current leader was not in the material read.
- open weights — A model whose trained parameters are published for anyone to download and run — unlike API-only models you can access but never possess.
- mixture-of-experts — A model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.
- streaming — Sending a model's response token by token as it is generated, so the reader sees text immediately instead of waiting for the whole answer.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
Checking sign-in…
Loading comments…