Ling-2.6-flash targets agent loops with a hybrid linear architecture
- Source
- x.com
- Date

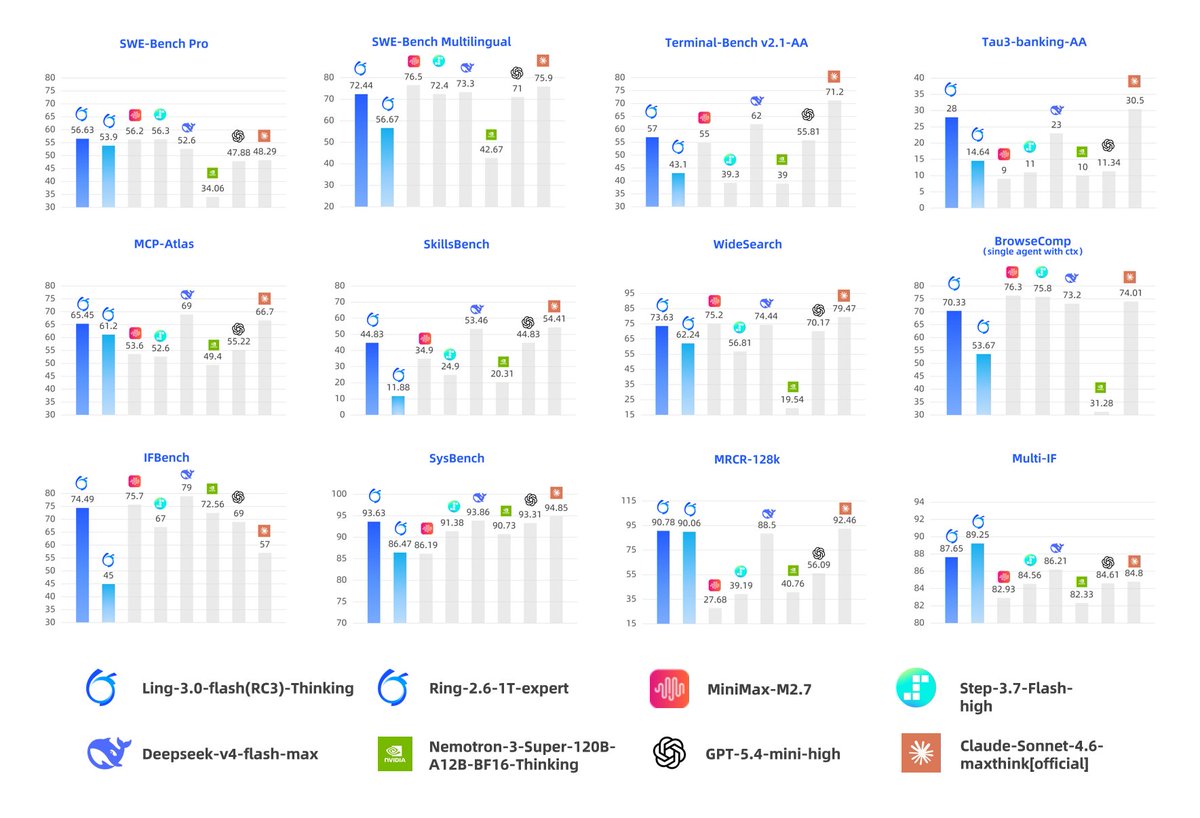
Designed for 🚀high token efficiency, Ling-2.6-flash is now opensource! ✅ Built for Agent scenarios ✅ Hybrid Linear Architecture ✅ Token-Efficiency Optimization ✅ Intelligence Delivered Blazingly Fast try out now: 🤖 Hugging Face: https://t.co/Z4dnBiWGU5 ⚙️ ModelScope: https://t.co/AA2uY7COkR #OpenSource #LLM #inlcusionAI #AIAgent
Context
Running an through many steps of a task means paying a per- cost repeatedly, so a model that does more with fewer tokens changes the economics of long agent loops. Ant Open Source, releasing under InclusionAI, describes Ling-2.6-flash as built specifically for that case, using a hybrid linear architecture aimed at token efficiency. It was open-sourced the same week as the larger Ling-2.6-1T flagship, with weights on Hugging Face and ModelScope.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- attention — The mechanism that lets a model weigh which earlier words matter for the word it's currently processing — the core operation of a transformer.
Checking sign-in…
Loading comments…