Introducing Ling-3.2-flash, Ant Ling's native multimodal model: 560B total / 25B active parameters.
Stronger complex visual understanding, long-horizon multimodal agents, 3D understanding & interaction, and medical intelligence.
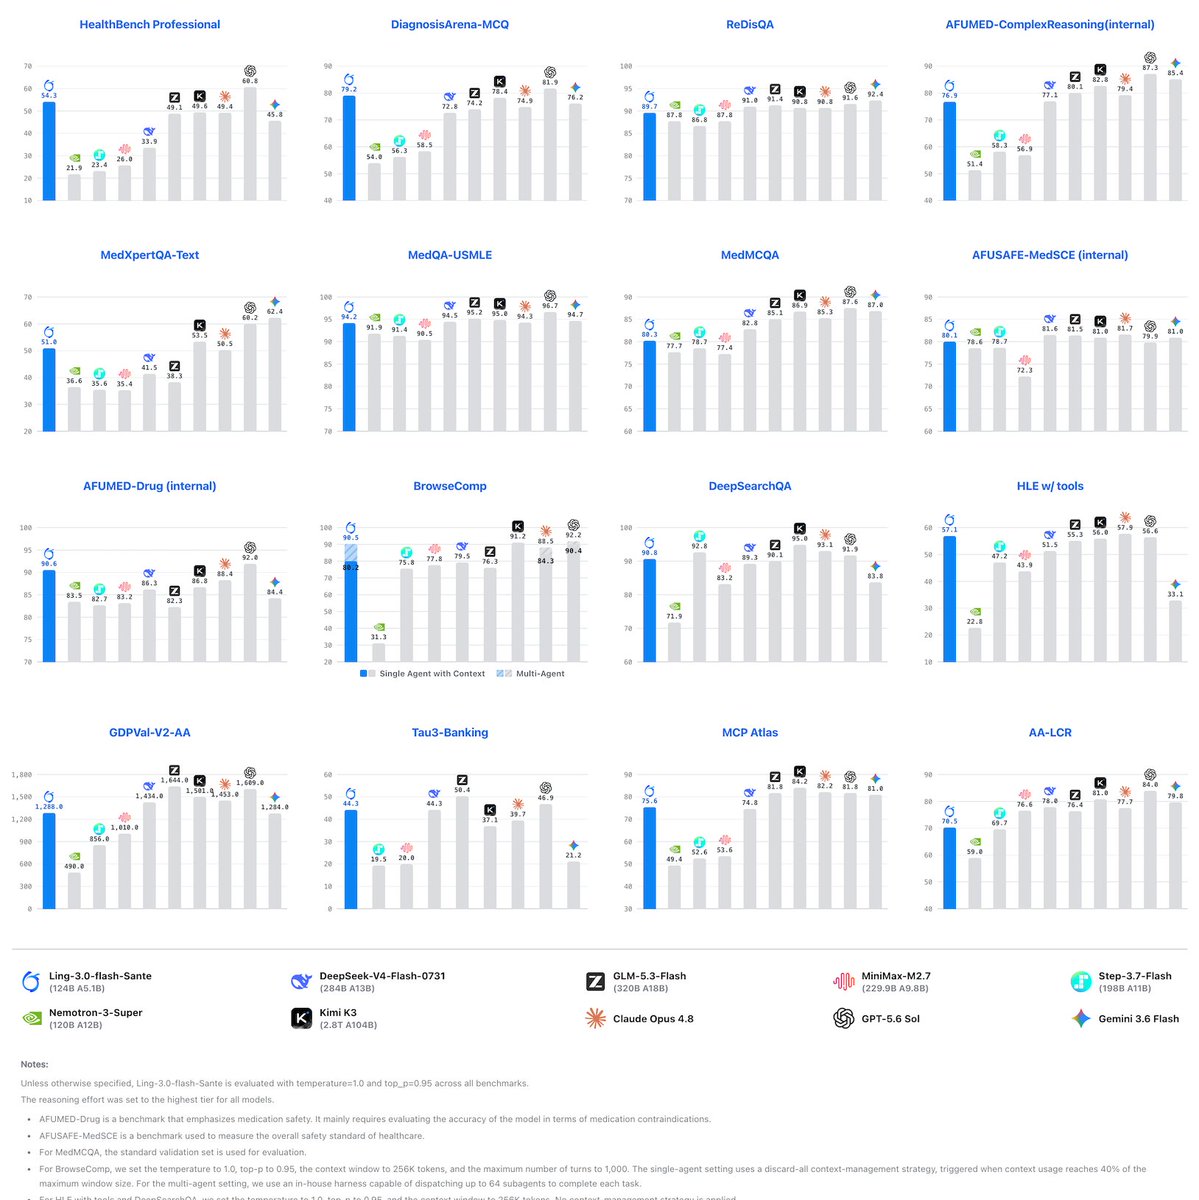
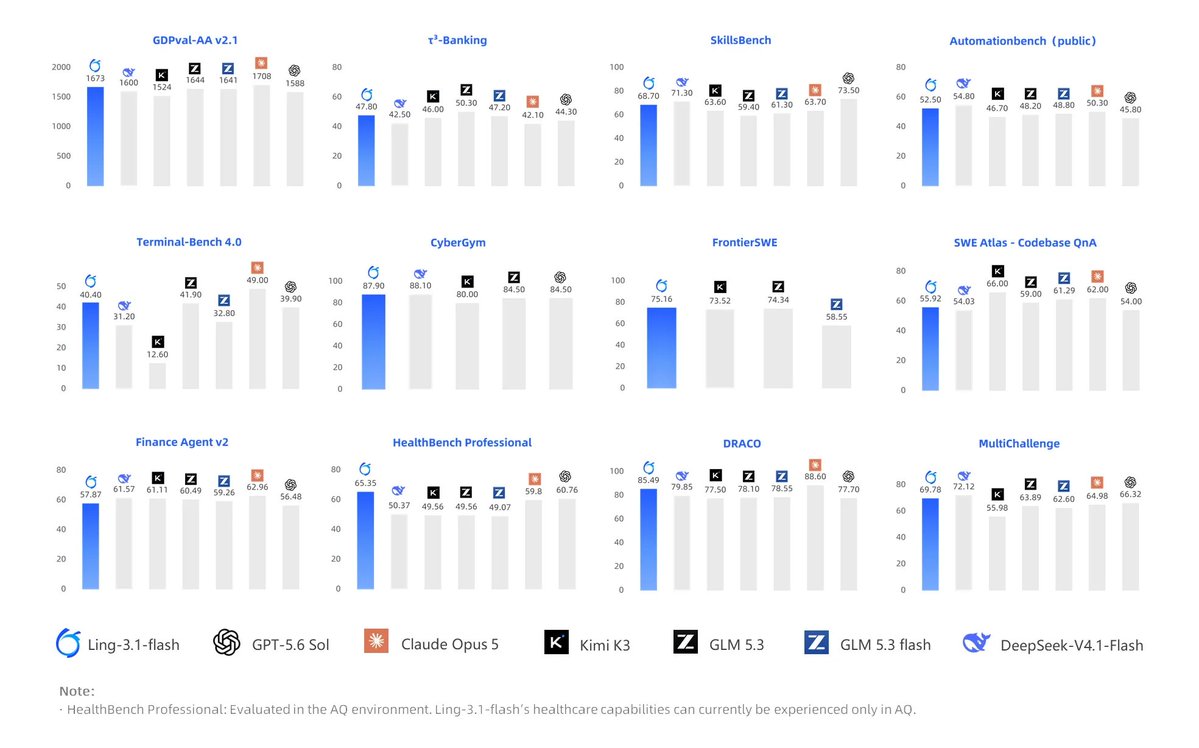
Outscores Opus 5 (max) in release evaluations:
- OmniDocBench1.5: 92.21 vs 90.56
- ZEROBench(Sub): 43.71 vs 39.52
- Vision2Web: 85.86 vs 80.20
Ling-3.2-flash is a 560B (25B active) multimodalA model that works with more than text — reading images, audio, or video, and sometimes generating them too.Full definition → model aimed at long-horizon visual agents and frontend work. Its benchmarkA standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.Full definition → claims versus Opus 5 are self-reported, so verify them before relying on it.
Terms in this piece · Glossary
multimodal — A model that works with more than text — reading images, audio, or video, and sometimes generating them too.
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.