👏🏻Congratulations!Step3-VL-10B was selected for HuggingFace Daily Papers…
Source
huggingface.co
Author
StepFun
Date
Context
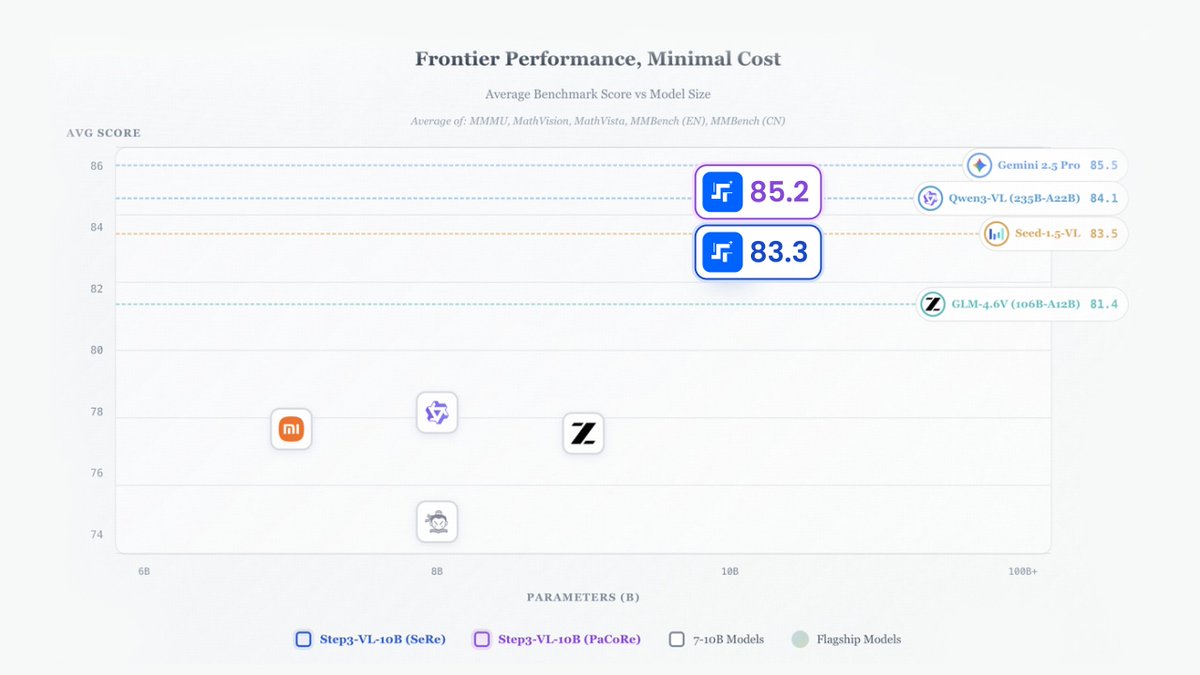
StepFun's Step3-VL-10B shows how a compact image-and-text model can improve its answers by spending more computation on each question. Its Parallel Coordinated Reasoning mode combines 16 independently generated reasoning attempts into context windowThe maximum amount of text a model can consider at once — its working memory for the current conversation or task.Full definition → for a final answer. In the authors' comparison, its MMMU score rises from 78.11% with sequential reasoning to 80.11% with this mode. The model remains the same size, but answering requires multiple attempts and a larger context budget. That distinction matters when interpreting its strongest benchmarkA standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.Full definition → results. Technical report.
Terms in this piece · Glossary
context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
multimodal — A model that works with more than text — reading images, audio, or video, and sometimes generating them too.
inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
 postStepFun Open-Sources Step Code, a CLI Coding Agent Benchmarked on Terminal-Bench
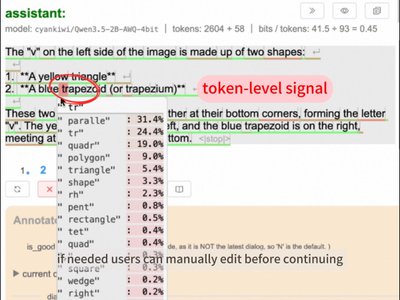 postStepFun Open-Sources onPanda, Its Internal LLM Annotation and Debug Tool
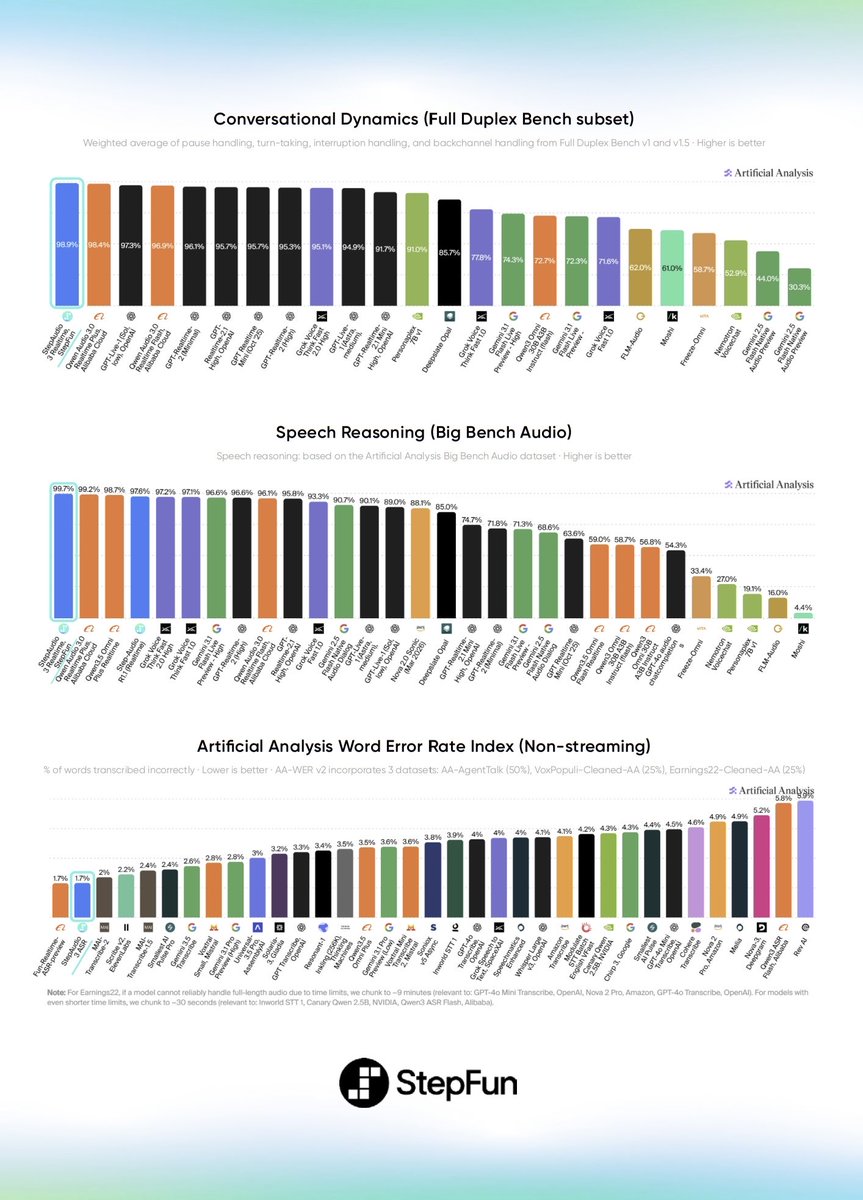 postStepFun debuts StepAudio 3 voice model family, tops real-time benchmarks
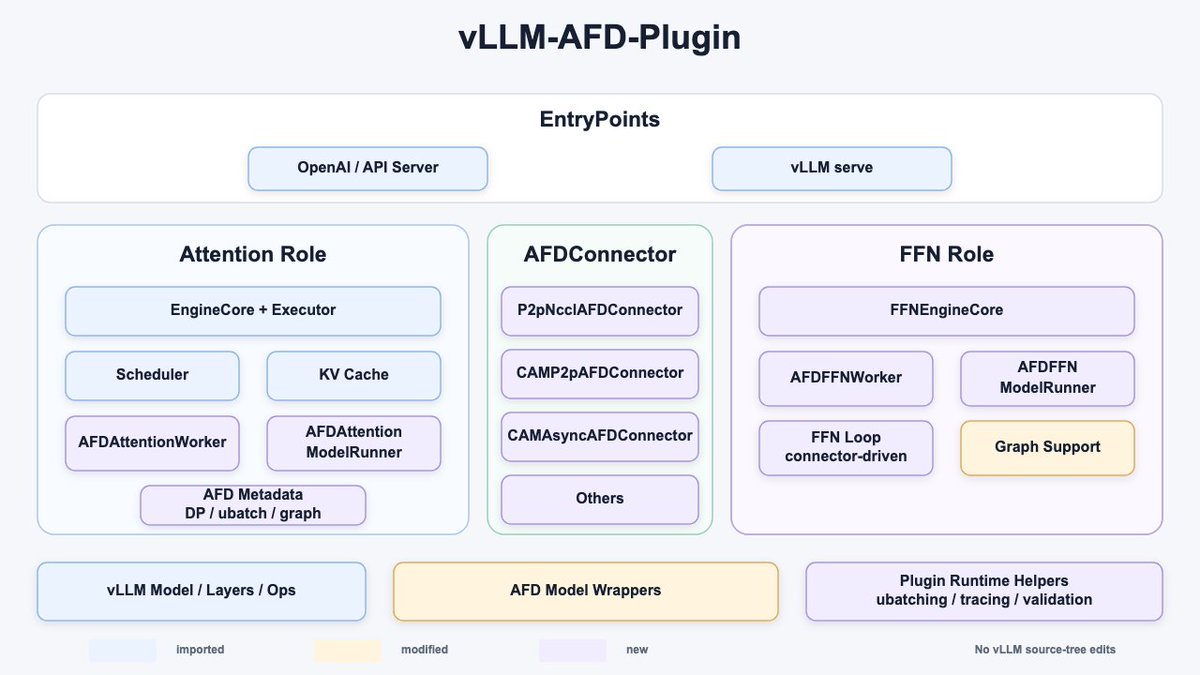 postvLLM gains an experimental Attention-FFN disaggregation plugin for MoE