Neural Networks: Zero to Hero
- Source
- github.com
- Author
- Andrej Karpathy
- Date
Context
Andrej Karpathy's Neural Networks: Zero to Hero teaches neural networks by having learners build and train them. The opening lesson assumes basic Python and some high-school calculus. The sequence then moves into language models, with accompanying notebooks and exercises. The course outline makes the progression explicit: learn the training machinery before tackling a .
One later exercise asks learners to calculate the training gradients themselves instead of relying on automatic differentiation. That makes the course useful for understanding where training calculations come from and diagnosing mistakes, rather than only learning how to call a model library.
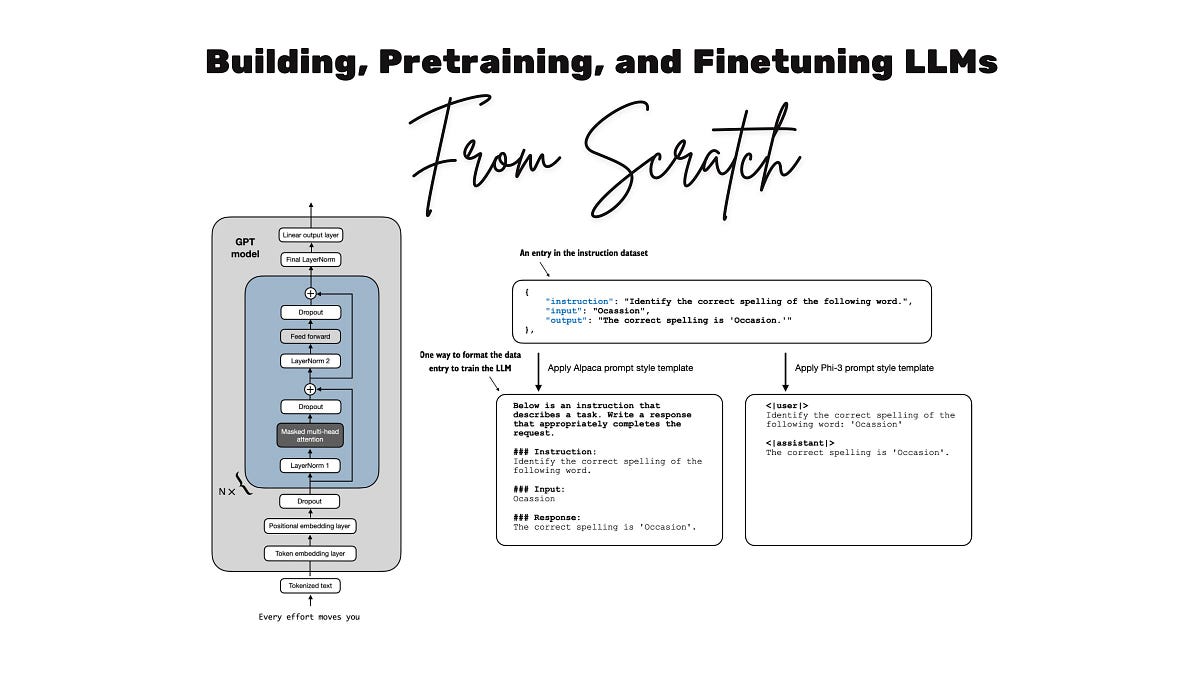
- transformer — The neural network architecture behind modern AI models, built on attention — letting every word directly consider every other word in parallel.
“A course on neural networks that starts all the way at the basics. The course is a series of YouTube videos where we code and train neural networks together.”
“We implement a bigram character-level language model, which we will further complexify in followup videos into a modern Transformer language model, like GPT.”
“We learn why training deep neural nets can be fragile and introduce the first modern innovation that made doing so much easier: Batch Normalization.”

Checking sign-in…
Loading comments…