Andrej Karpathy is an AI researcher at Anthropic and an educator known for explaining neural networks through working code. A founding member of OpenAI and former director of AI at Tesla, he created open-source projects including micrograd and nanoGPT.[1][3][4][9]
Start with Neural Networks: Zero to Hero →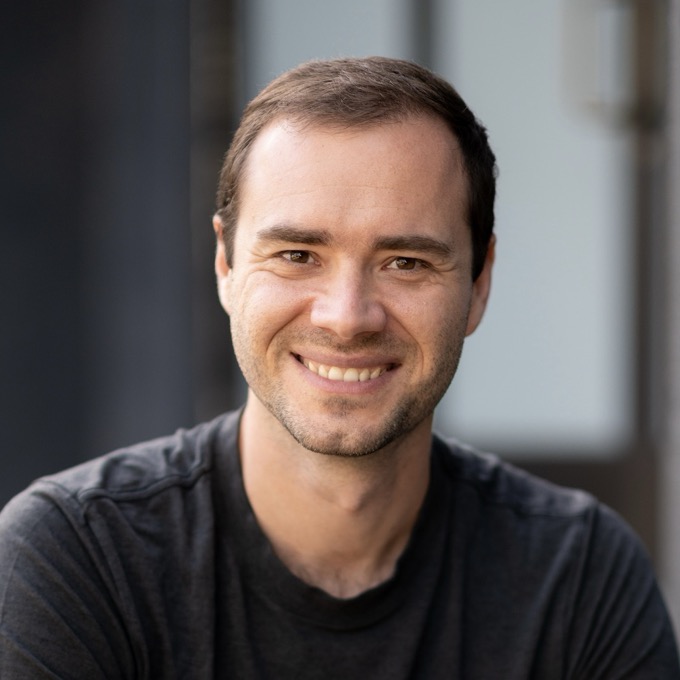
Education
Links
Website YouTube Blog Google Scholar X · karpathy
 GitHub · karpathy
AI researcher · Anthropic
Background
Karpathy studied computer science and physics at the University of Toronto, then completed a master’s degree at the University of British Columbia. At Stanford, he worked with Fei-Fei Li on the relationship between images and language. Their image-description research learned correspondences between regions in a picture and words in a sentence, then used those correspondences to generate descriptions. This let a model describe parts of an image instead of only assigning a single label to the whole picture.[1][8][7]
Career
Karpathy joined OpenAI as a founding researcher in 2015. From 2017 to 2022, he led computer vision for Tesla’s Autopilot, with a team responsible for data labeling, training neural networks, and deploying them on Tesla’s inference hardware. He returned to OpenAI in 2023 to build a team working on midtraining and synthetic data. In May 2026, he announced that he had joined Anthropic and was returning to research and development. He also said he intended to resume his education work in time.[1][9]
Contributions
Teaching neural networks
Karpathy’s Neural Networks: Zero to Hero course teaches deep learning by building the machinery in code. It begins with backpropagation, the calculation that tells a network how to adjust its parameters, and progresses toward language models. The lessons connect mathematical ideas to implementations that a learner can run and modify. His earlier teaching includes Stanford’s CS231n course on neural networks for visual recognition.[2][8]
micrograd and learning by implementation
micrograd makes the mechanics of neural-network training small enough to inspect. It records arithmetic operations in a graph and works backward through that graph to calculate how each input affects the result. A small neural-network library sits on top. The repository includes a demonstration that learns to separate two classes of points, letting readers follow the same basic training process used in larger systems without starting with a large framework.[3]
From nanoGPT to nanochat
nanoGPT provides a compact implementation for training and fine-tuning GPT language models. Its model definition and training loop make the relationship between architecture, data, and optimization visible in ordinary Python code. The repository now directs users to nanochat and marks nanoGPT as deprecated. nanochat extends the work into a pipeline for training a model and talking to it through a chat interface. It also maintains experiments that measure how quickly a model can reach a specified GPT-2 benchmark score. Those results describe a particular evaluation, not equivalence to every capability of a commercial assistant.[4][5]
Tools for following research
Karpathy also built arxiv-sanity-lite to help readers work through research papers. Users tag papers they find interesting, and the application recommends similar papers using the text of their abstracts. The project addresses a different part of research work from model training: deciding what to read in a growing literature. Its implementation and setup instructions are public.[6]
Tools, writing & talks
Writing, research & talks
Start here
Neural Networks: Zero to Herokarpathy.aiA course that builds neural networks in code, starting with backpropagation and progressing toward language models.
Start with the first micrograd lesson and build along to see how a neural network learns. You will need Python programming skills and basic derivatives; the course then works toward language models.
Course creator[2]Original source- Build nanoGPTgithub.com
A video lecture and code walkthrough that builds a GPT language model from scratch and trains it on text.
Course by Andrej KarpathyOriginal source Andrej Karpathy sketches a funnel of LLM experience, from billions with minimal contact to a few thousand with internal frontier access, and attributes the widening perception gap to problem ambition, jagged RL-shaped capability, and tiered access.
Catalog workOriginal sourceKarpathy argues agents will take a decade to mature, framing them as interns that cannot yet be trusted with real work, and discusses the capability gaps in tools like Claude and Codex that hold them back.
Catalog workOriginal sourceAndrej Karpathy argues that software is undergoing a second fundamental shift in a few years, with LLMs creating a new programming paradigm and a large amount of software to write and rewrite.
Catalog workOriginal source
Tools
- nanoGPTgithub.com
A compact GPT training implementation whose repository now directs users to its successor, nanochat.
Creator · Language-model training; deprecated[4]Original source - microgradgithub.com
A small automatic-differentiation engine and neural-network library for learning how training works.
Creator · Neural-network learning library[3]Original source - llm.cgithub.com
Language model training in C and CUDA, exposing the computations normally handled by machine learning frameworks.
Repository by Andrej KarpathyOriginal source - Caloriegithub.com
Simple web page for logging daily calories, built as a personal tool by Andrej Karpathy.
Catalog workOriginal source - rustbpegithub.com
Rust implementation of BPE tokenizer training by Andrej Karpathy, supplying the training code tiktoken lacks.
Catalog workOriginal source - HN Time Capsulegithub.com
Uses LLMs to revisit decade-old Hacker News discussions and score how their predictions and ideas held up.
Catalog workOriginal source - rendergitgithub.com
Renders any git repository into a single static HTML page for human reading or pasting into an LLM.
Catalog workOriginal source - makemoregithub.com
Character-level autoregressive language model that generates new names or words from a small training set.
Catalog workOriginal source - reader3github.com
Python tool from Andrej Karpathy for reading books together with LLMs, annotating and asking questions along the way.
Catalog workOriginal source - minbpegithub.com
Minimal, clean implementation of the Byte Pair Encoding tokenization algorithm used by GPT and most modern LLMs.
Catalog workOriginal source - autoresearchgithub.com
Experiment in which AI agents autonomously research single-GPU nanochat training, proposing hyperparameter tweaks.
Catalog workOriginal source - LLM Councilgithub.com
Karpathy experiment where an ensemble of LLMs debates a question and arrives at a synthesized answer.
Catalog workOriginal source - llama2.cgithub.com
Runs Llama 2 inference in a single file of pure C, serving as a minimalist reference for how LLM inference works.
Catalog workOriginal source - minGPTgithub.com
Minimal PyTorch re-implementation of GPT in about 300 lines, written for understanding transformer language models.
Catalog workOriginal source - nanochatgithub.com
A pipeline for training a language model and using it through a chat interface, with experiments measuring training efficiency.
Creator · Model training and chat[5]Original source - arxiv-sanity-litegithub.com
A paper-discovery application that recommends research using abstract text and a reader's tagged interests.
Creator · Research-paper discovery[6]