Meta's first streaming speech model undercuts the field on price
- Source
- x.com
- Date

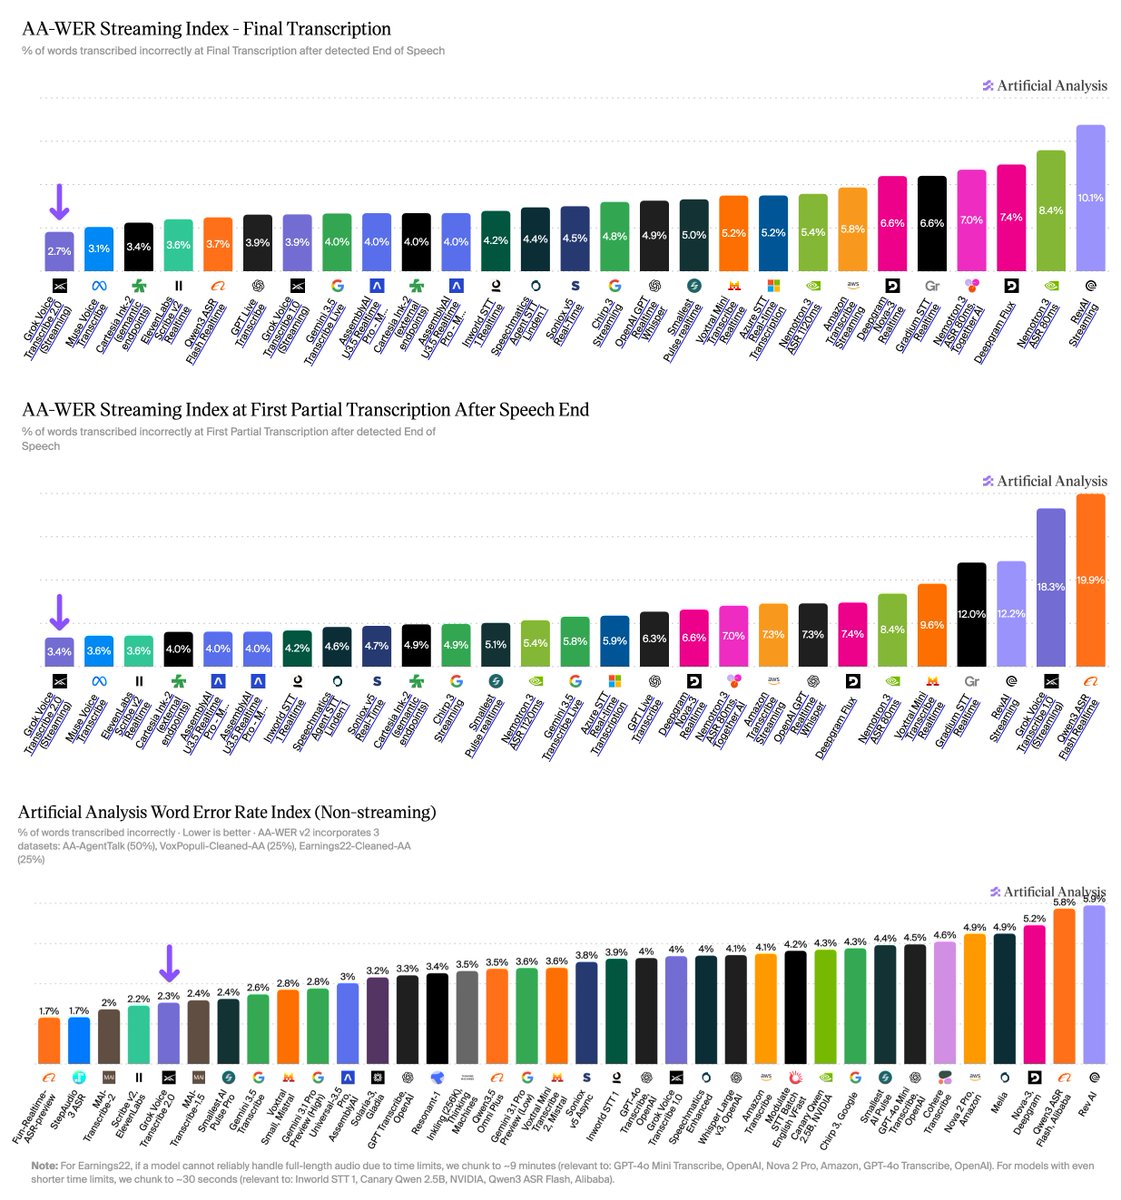
Meta has released Muse Voice Transcribe, taking the #1 spot for Final Transcript accuracy on AA-WER Streaming with 3.1% WER at 0.16s after end of speech Muse Voice Transcribe is the first streaming Speech to Text model developed by Meta Superintelligence Labs. Meta states that the model was trained on more than 70 languages, with 25 extensively verified, and supports audio inputs exceeding one hour without required post-processing. It processes audio in 80ms chunks and is available through the Meta Model API, Meta AI for Mac and Muse Code. Key takeaways ➤ Final Transcript: Muse Voice Transcribe achieves 3.1% WER at 0.16s after end of speech. It is more accurate and faster than Cartesia Ink-2 (semantic endpoints) at 3.4% and 0.43s, and more accurate but slower than Cartesia Ink-2 (external endpoints) at 4.0% and 0.07s. It is also more accurate, though slightly slower, than ElevenLabs Scribe v2 Realtime at 3.6% and 0.14s. ➤ First Partial Transcript: The model achieves 3.6% WER at 0.13s, just ahead of ElevenLabs Scribe v2 Realtime on accuracy and latency. It is more accurate and faster than Cartesia Ink-2 (semantic endpoints) at 4.9% and 0.17s, and more accurate but slower than Cartesia Ink-2 (external endpoints) at 4.0% and 0.07s. ➤ Price: Muse Voice Transcribe costs $0.18 per hour, or $3 per 1,000 minutes. This is below Cartesia Ink-2 at $4 and less than half the $6.50 charged for ElevenLabs Scribe v2 Realtime and Deepgram Flux. See more details below ⬇️

On First Partial Transcript, Muse Voice Transcribe achieves a 3.6% WER at 0.13s after end of speech, just ahead of ElevenLabs Scribe v2 Realtime on accuracy and latency. Muse is more accurate than Cartesia Ink-2 with external endpoints at 4.0% WER and 0.07s, while trading some speed, and is both more accurate and faster than AssemblyAI Universal-3.5 Pro Realtime, whose Max Accuracy and Min Latency modes achieve 4.0% WER at 0.18s and 0.17s, respectively.

Muse Voice Transcribe is available for $0.18 per hour, equivalent to $3 per 1,000 minutes of audio, below Cartesia Ink-2 at $4 per 1,000 minutes and less than half the $6.50 charged for ElevenLabs Scribe v2 Realtime and Deepgram Flux.

Full results: https://t.co/wDb6a2nhqV Methodology: https://t.co/ePPoyfUXXm
Context
Artificial Analysis, an AI model evaluator, ranked Meta's Muse Voice Transcribe first for final-transcript accuracy in its September 1 streaming speech-to-text comparison. means the text is produced while the audio arrives, and accuracy is reported as word error rate (WER), the share of words transcribed wrongly. Muse scored 3.1% WER, with final text arriving 0.16 seconds after speech ended. ElevenLabs' Scribe v2 Realtime was slightly faster at 0.14 seconds but less accurate at 3.6%, and Cartesia's Ink-2 with external endpoints was faster still at 0.07 seconds with 4.0% WER.
The thread also reports Muse's price as $0.18 per audio hour, or $3 per 1,000 minutes, below each competitor price it lists: $4 for Cartesia Ink-2 and $6.50 for ElevenLabs Scribe v2 Realtime and Deepgram Flux. The comparison therefore has three separate measures: errors, delay after speech ends, and cost. In this Muse led on accuracy and was cheaper than the priced alternatives listed, but it did not finish fastest.
- streaming — Sending a model's response token by token as it is generated, so the reader sees text immediately instead of waiting for the whole answer.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
Checking sign-in…
Loading comments…