Meta's Muse Voice Transcribe decides word by word when to commit
- Source
- x.com
- Date

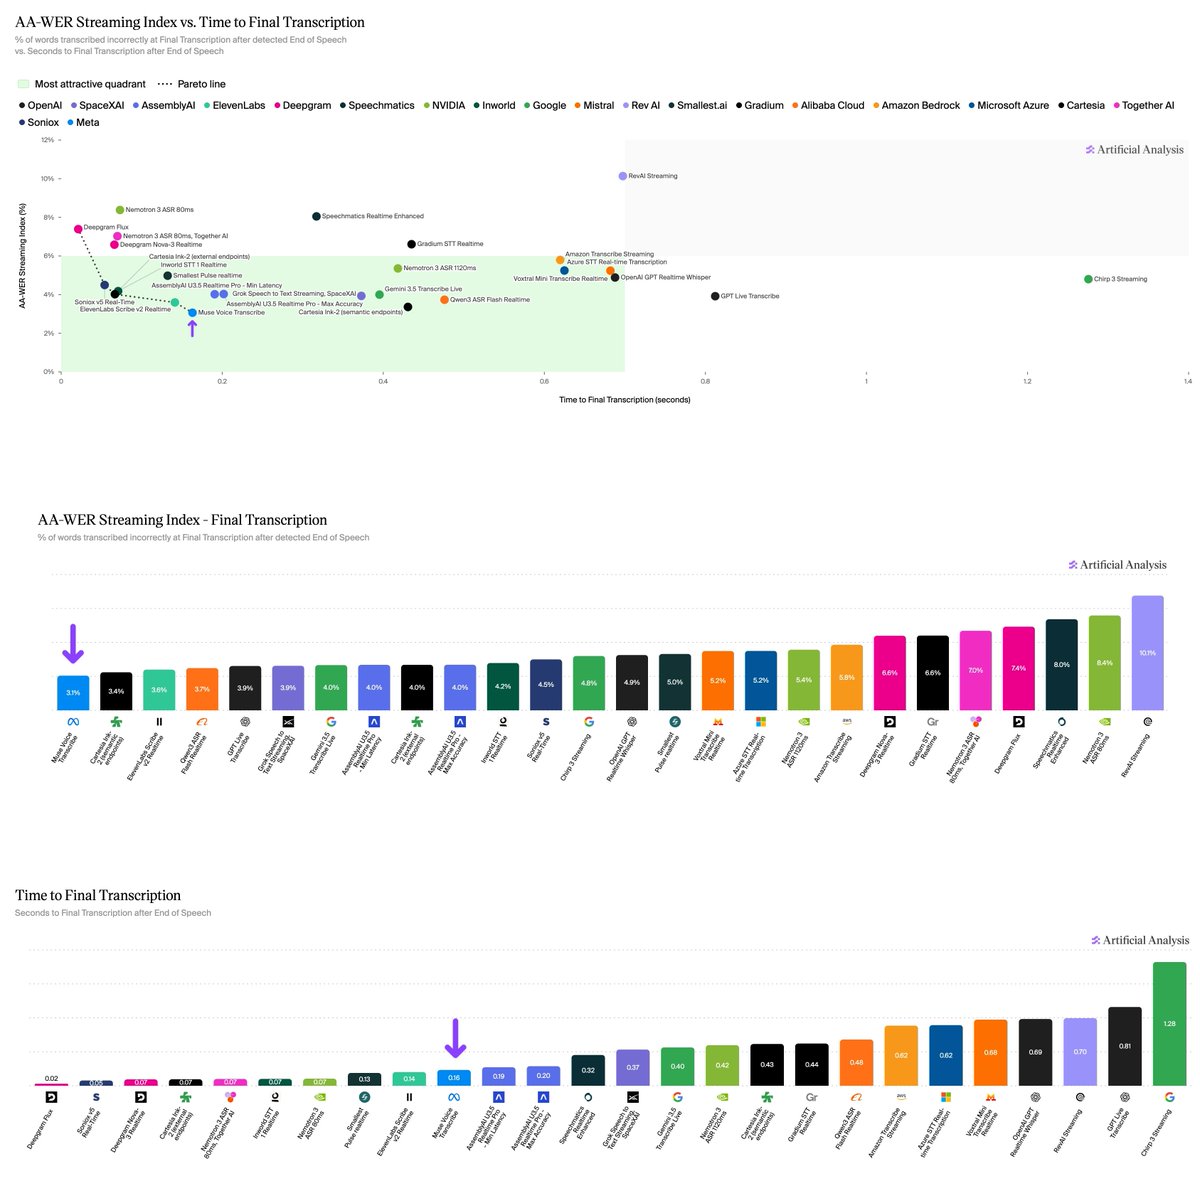
Introducing Muse Voice Transcribe, the first real-time audio perception model from Meta Superintelligence Labs. Muse Voice Transcribe delivers real-time streaming ASR, diarization with 20+ speakers, and endpointing. It’s multilingual with seamless code-switching and improves accuracy with language, keyword, and context biasing. The model ranks first on @ArtificialAnlys streaming speech-to-text and on public diarization benchmarks.


Muse Voice Transcribe is an autoregressive multimodal LLM from the Muse Spark family. Audio is processed in 80ms chunks (12.5 Hz), one token each, and at every chunk the model decides whether to keep listening or emit text. RL with combined word error rate and delay rewards gives it adaptive delay: it waits longer on hard words and commits sooner on easy ones, trading accuracy against latency word-by-word.

With adaptive delay, Muse Voice Transcribe achieves the pareto frontier on speed-accuracy trade-off measured by time to final transcription.
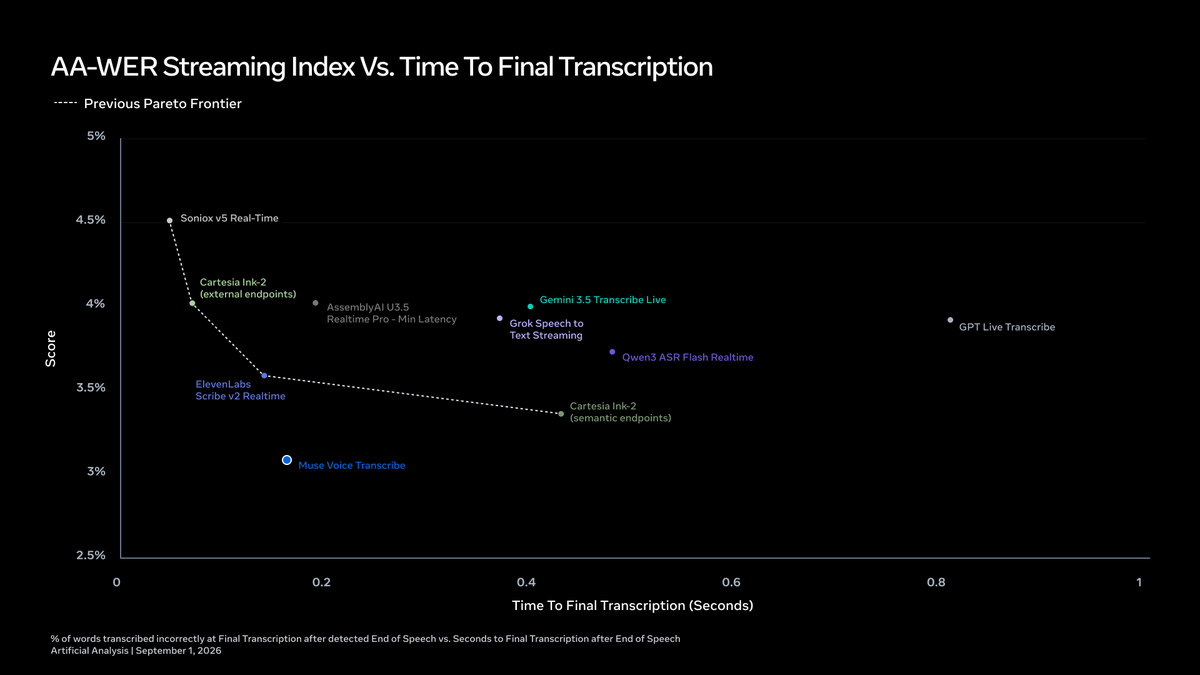
Muse Voice Transcribe is available today via Meta Model API, Meta AI for Mac, and Muse Code. Learn more: https://t.co/lLNaPF8DlC
Context
Meta's Muse Voice Transcribe makes the decision to wait for more speech part of transcription itself. According to its launch explanation, the model processes incoming audio in 80-millisecond chunks and decides after each chunk whether to keep listening or produce text. Reinforcement learning with rewards for both word accuracy and shorter delay gives it adaptive delay: it commits sooner on easier words and waits longer on difficult ones. The 80-millisecond figure describes the incoming chunks; the time before a word is finalized varies with that decision. Technical launch thread.
- streaming — Sending a model's response token by token as it is generated, so the reader sees text immediately instead of waiting for the whole answer.
Checking sign-in…
Loading comments…