Fish Audio previews Drama 3, a plain-language-controllable TTS model
- Source
- x.com
- Date

Introducing Drama 3 (preview): the most controllable TTS model ever. Describe the tone, pacing, and character in simple language, without thinking in audio tags. Shift your voice mid-sentence, generate a multi-character scene, or fix only a single word. Comment DRAMA to get an API key 🐟

Context
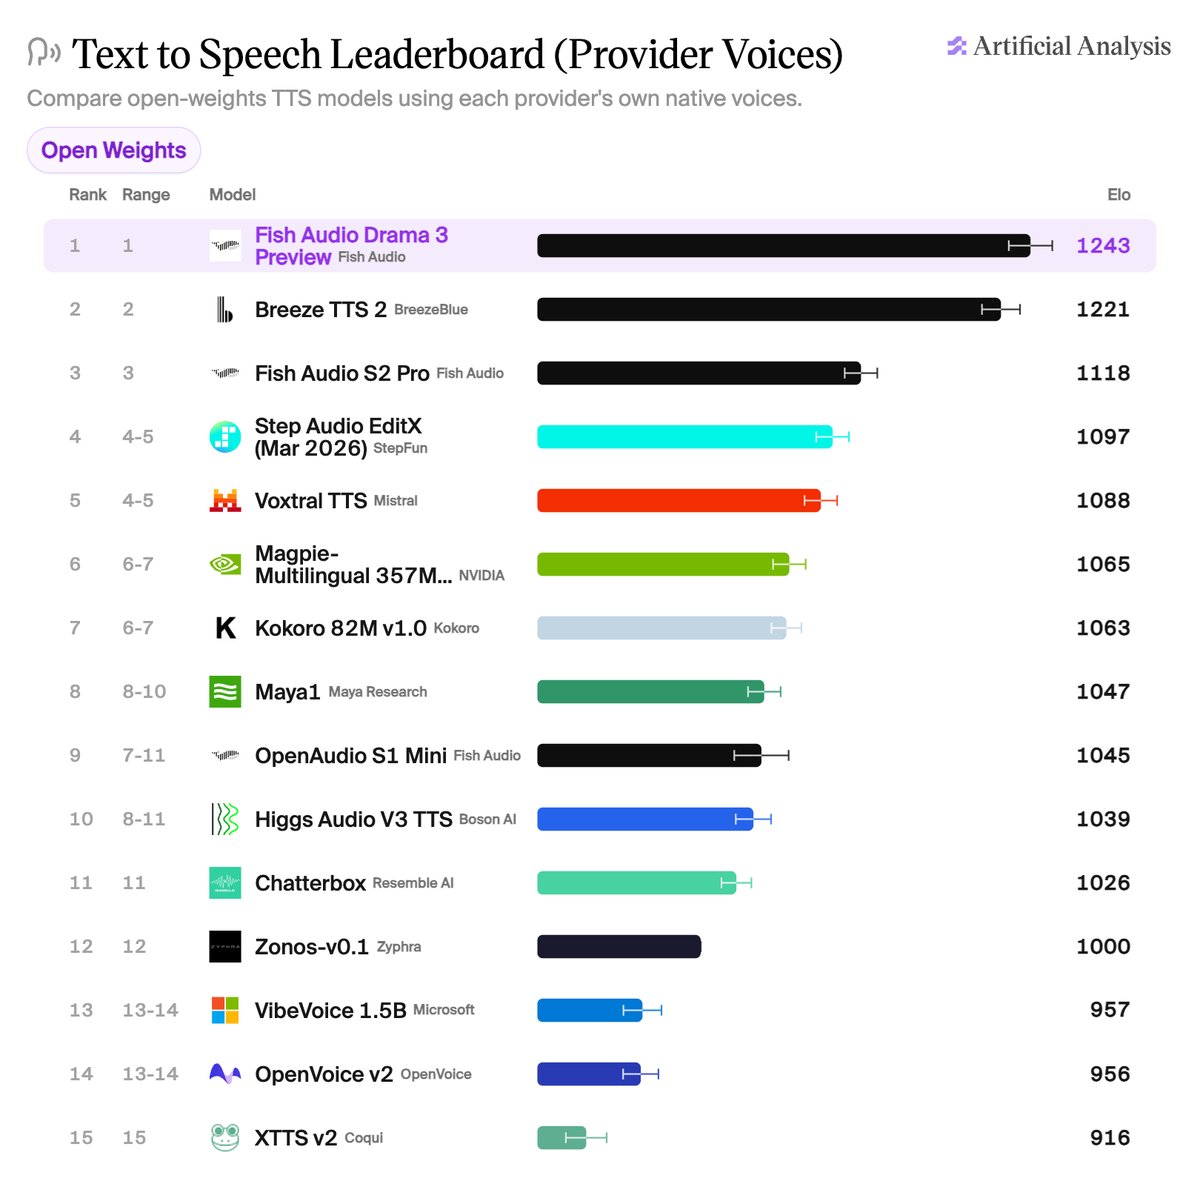
Fish Audio has opened a preview of Drama 3, a text-to-speech model it describes as controllable through plain descriptions rather than the inline audio tags many expressive TTS systems use. In Fish Audio's announcement, a user describes tone, pacing, and character in ordinary language, and the model is said to let someone shift voice mid-sentence, generate a scene with multiple characters, or regenerate a single word.
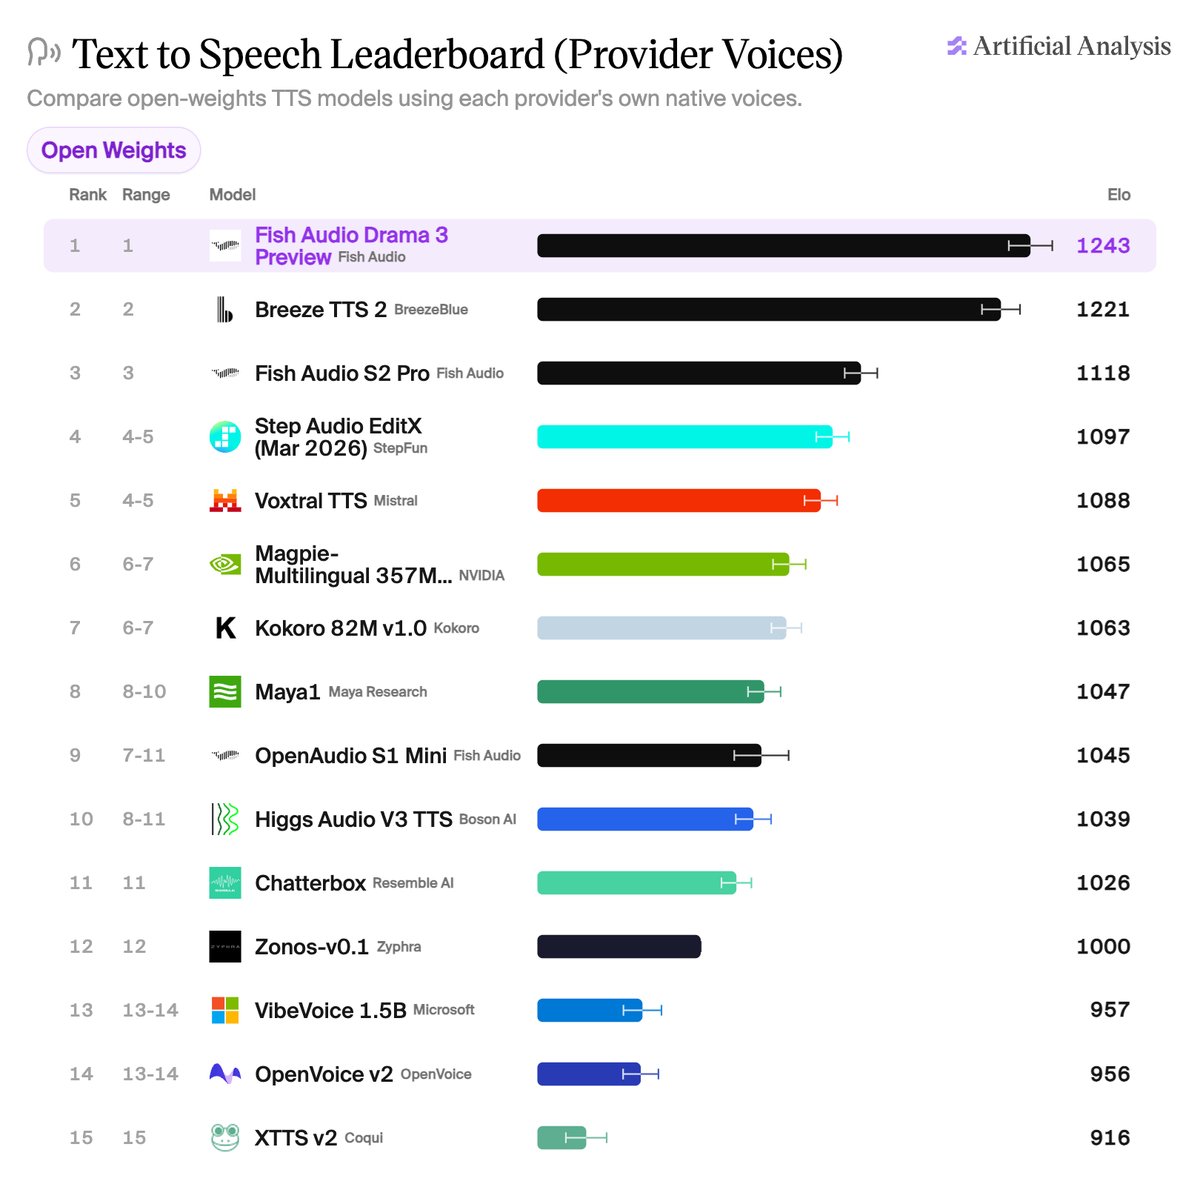
Fish Audio calls it 'the most controllable TTS model ever,' its own characterization rather than an independently measured comparison. Other 2026 voice releases pursue similar territory with different mechanics: Google's Gemini 3.1 Flash TTS takes bracketed style cues embedded in a script, and StepFun's StepAudio 2.5 already accepts plain-language direction for emotion and pacing. What would set Drama 3 apart, if the preview holds up, is combining natural-language direction with mid-utterance voice switching and multi-character generation in one model, a capability the announcement describes but that has not been tested outside Fish Audio's own demonstration.
Access for now runs through a waitlist rather than open sign-up: Fish Audio is granting API keys to people who comment 'DRAMA' on the announcement, so independent testing of these claims is not yet widely available.
Checking sign-in…
Loading comments…