MiniMax M3.1 Flash gets 2-bit Unsloth GGUFs for local hosting
- Source
- x.com
- Date

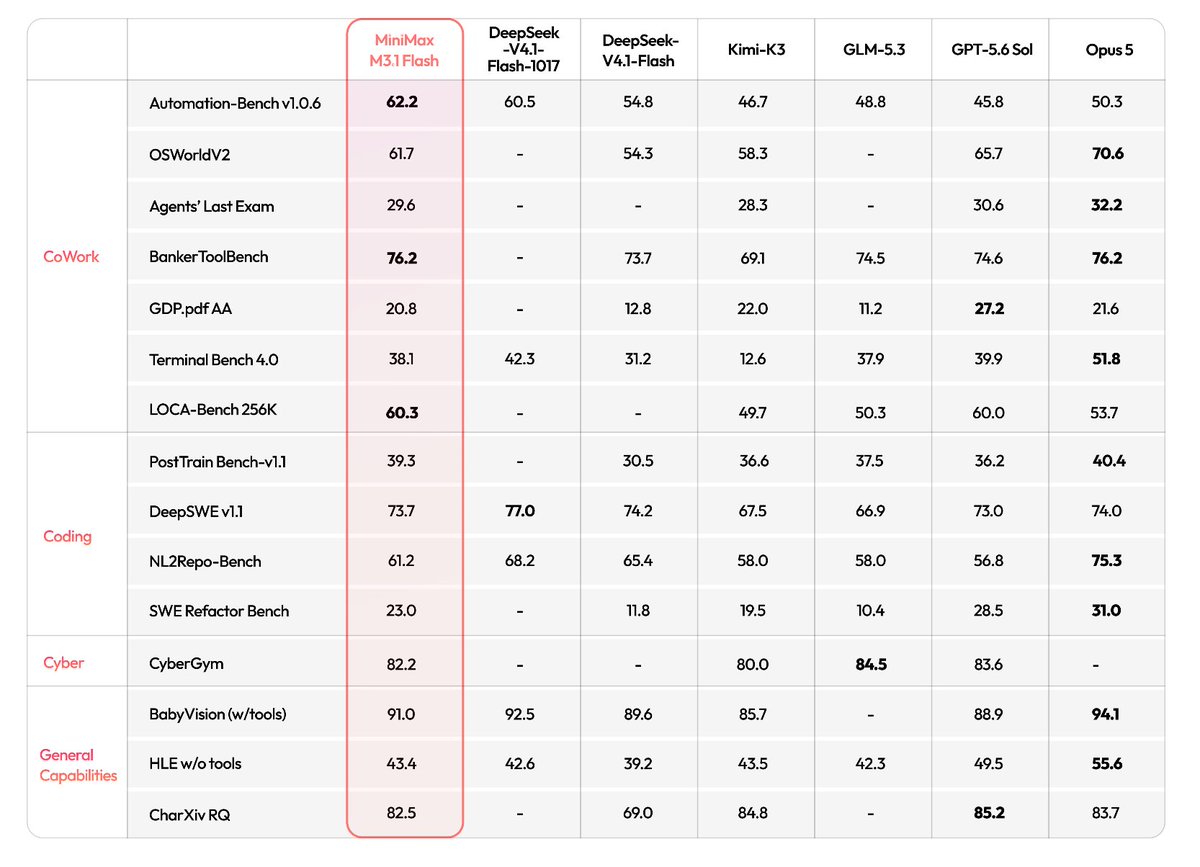
MiniMax M3.1 Flash meets the @UnslothAI community. 🐙🦥✨ Unsloth’s Dynamic GGUFs bring our 428B MoE model to a 143.9GB 2-bit footprint, with 91.5% top-1 token agreement in their evaluation across seven domains. That means a lower memory barrier to self-hosting, deployment through Unsloth Desktop and llama.cpp, and an OpenAI-compatible API for existing apps and agents. With 78K+ GitHub stars and over 500M model downloads on Hugging Face, Unsloth gives M3.1 Flash a path into an established community of developers running, evaluating and building with open models. Open weights. Local control. More ways to build.

A 428B now fits in a 143.9GB 2-bit that runs through llama.cpp and Unsloth Desktop with an OpenAI-compatible API. That lowers the memory needed to self-host an model behind existing agents.
- mixture-of-experts — A model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- quantization — Shrinking a model by storing its numbers less precisely — like rounding — so it runs faster and fits on smaller hardware, at a small quality cost.
- open weights — A model whose trained parameters are published for anyone to download and run — unlike API-only models you can access but never possess.
Checking sign-in…
Loading comments…