Today we are announcing our biggest bet yet on our own silicon.
- Source
- x.com
- Date

Today we are announcing our biggest bet yet on our own silicon. Starting next calendar year, we will scale our Maia family to multi-gigawatt deployments, making it the primary inference system for our own product and services. And we’re introducing Maia 300, which delivers 40% more tokens per watt compared to leading GPU-based systems. We are already deploying Maia 200 across the US, Europe, and Australia, delivering up to 1.7x more tokens per watt across experiences in Teams and Copilot. Our goal is to build on the full-stack efficiency gains we’ve already seen, while continuing to bring the latest innovations from across the ecosystem into our fleet.
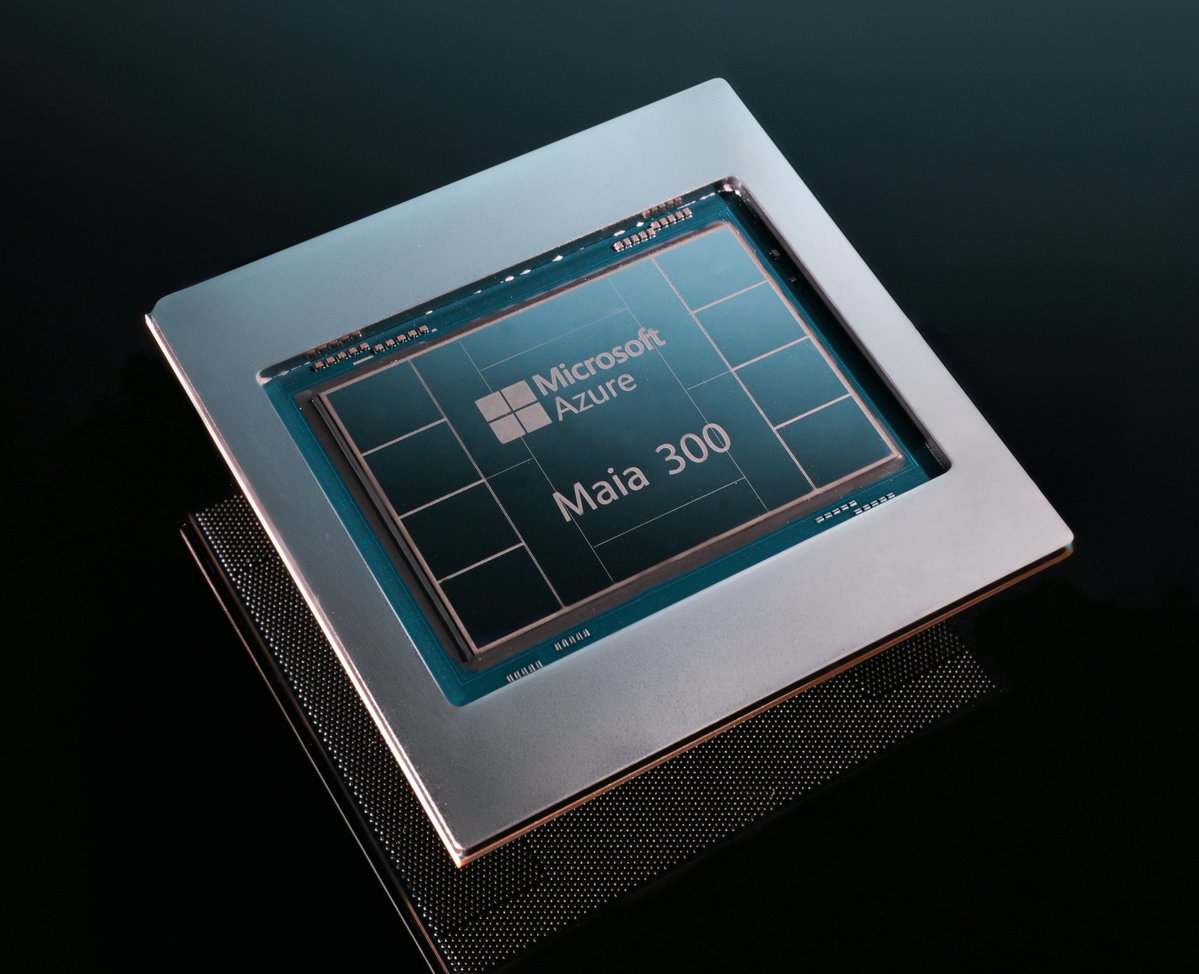
Microsoft is moving its own onto in-house silicon at multi-gigawatt scale from next calendar year, claiming large -per-watt gains. That shapes inference cost and capacity for products built on its platforms.
 postOpenAI's first inference chip posts results, deploys by year-endOpenAI
 articleSpaceX 10GW in 2027 – Why It’s Real, Will Drive $300B ARR for SpaceX, and Why Microsoft Will Be the Largest OfftakerJeremie Eliahou Ontiveros
 postLocal inference crosses over: the M5 Ultra and the 1,000x claimAlex Cheema
Checking sign-in…
Loading comments…