OpenAI's first inference chip posts results, deploys by year-end
- Source
- x.com
- Date

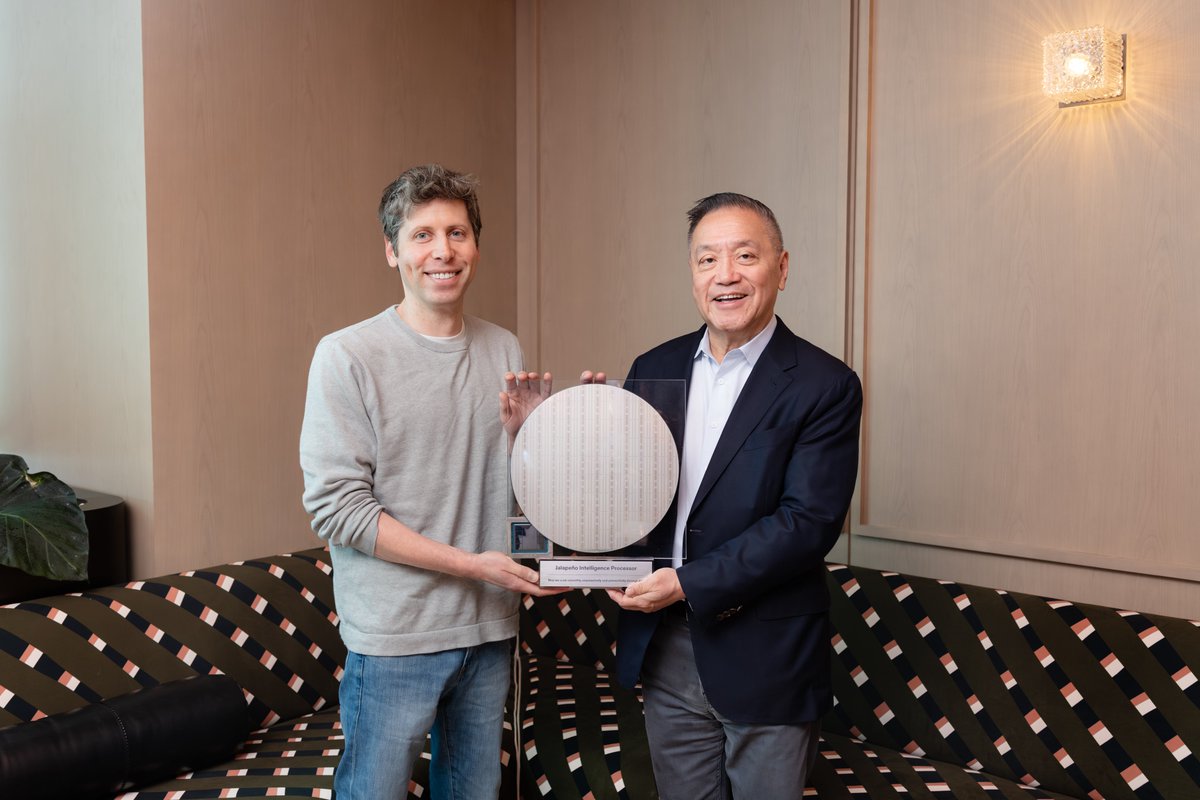
Since announcing Jalapeño, our first custom inference chip, we’ve been testing it and the system around it. The results show a major advance: more intelligence from every watt and faster responses, delivering both higher throughput and lower latency in one architecture without sacrificing efficiency.

Jalapeño means faster ChatGPT responses, more responsive Codex sessions and agents, and reliable access as demand continues to grow.

We plan to begin deploying Jalapeño in OpenAI’s compute infrastructure by year-end. It’s the first step in a multigenerational roadmap: Gen 2 is deep in development, and Gen 3 is taking shape. Each generation will push efficiency and speed further. https://t.co/OLO0OUVt13
capacity and latency for Codex and the API ride on this silicon; a year-end deployment date is a concrete signal about headroom and responsiveness under load.
- inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
Checking sign-in…
Loading comments…