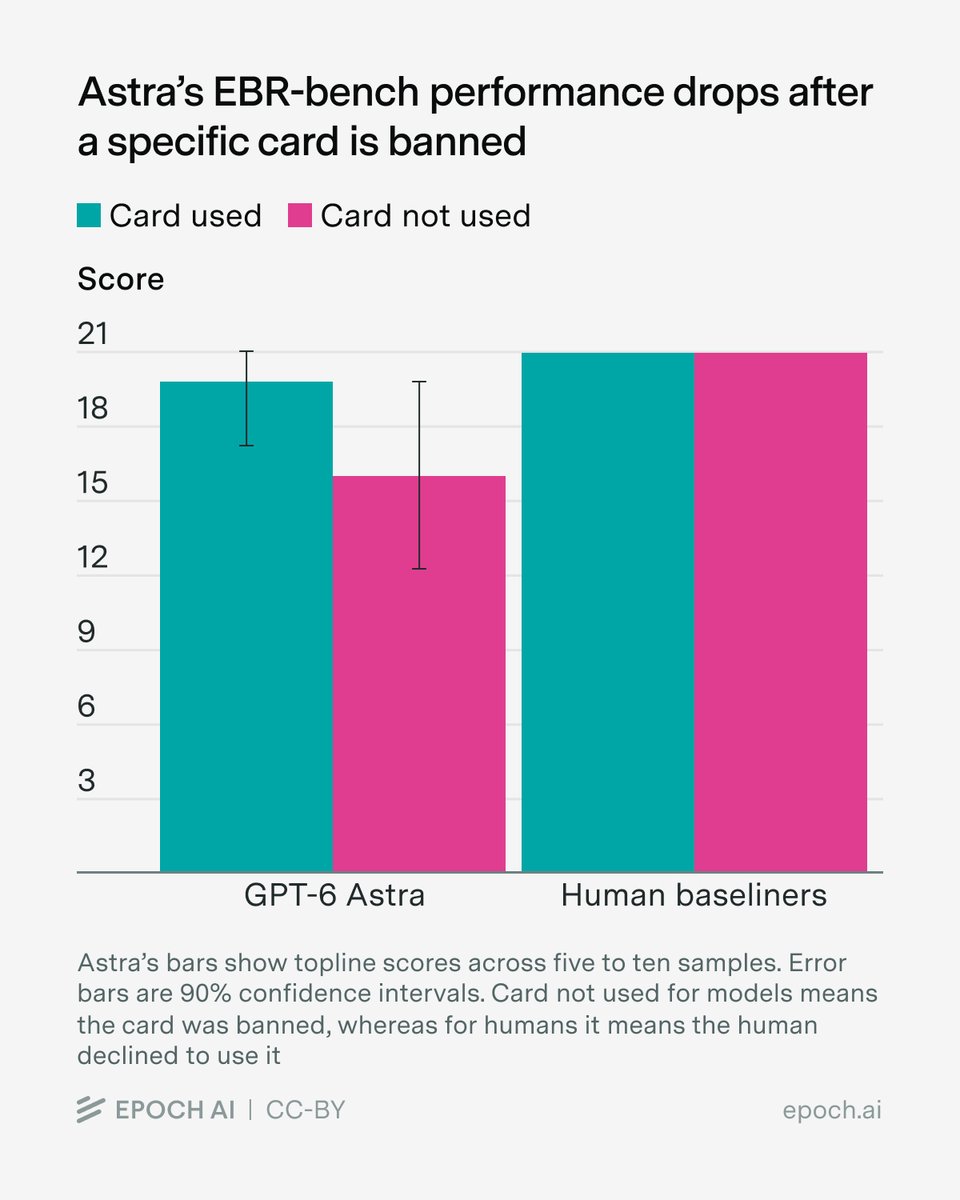
EBR-bench gives early evidence that models struggle to improve through repeated attempts, a limit for long-running agents.
Key takeaways · AI-distilled
EBR-bench has models repeatedly play the board game Earthborne Rangers to test learning from experience; Epoch says it so far sees little evidence that models improve across attempts, and positions the benchmarkA standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.Full definition → as a detector for when that changes.
MirrorCode, co-developed with METR, lets AI code autonomously for weeks to rebuild real programs from scratch, some tens of thousands of lines long; the best model scored 56% at the time of the brief.
Researcher Luke Emberson counted about 1,500 high- and critical-severity CVEs disclosed by 21 notable organizations in June, more than 3.5x the prior monthly record, a spike that followed Anthropic's April Claude Mythos Preview announcement.
GPT-4 led the Epoch Capabilities Index for roughly a year after its March 2023 release; the next-longest lead, by o1, lasted a little over three months.
A Gradient Update by JS Denain and Anson Ho argues futurist claims about automated research building nanotech or Dyson swarms rest on capability gains alone, and proposes exploratory engineering with explicit AI-capability assumptions instead.
Terms in this piece · Glossary
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.