Open-weight cyber capability trails closed frontier by 6-7 months
Source
epoch.ai
Author
Epoch AI
Date
Why it matters
Open-weight models now match where closed models stood 6-7 months ago on cyber tasks, which informs security-risk timelines and model access decisions. GLM-5.3's score rests on only three benchmarkA standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.Full definition → results.
Key takeaways · AI-distilled
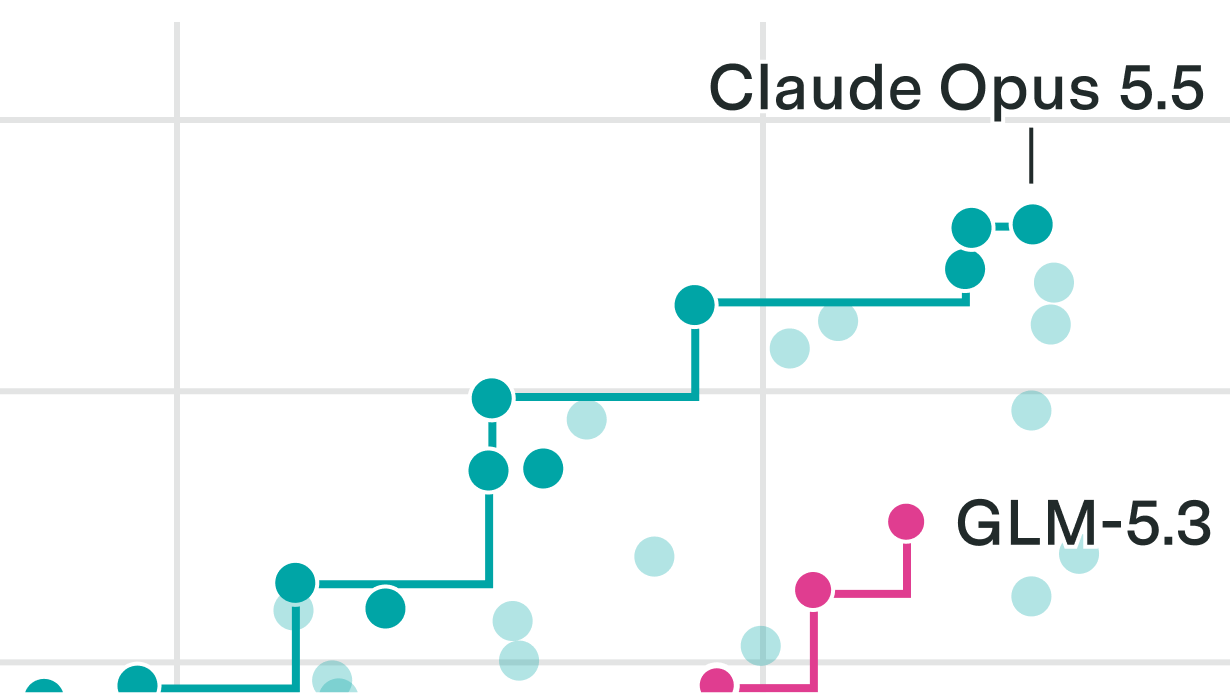
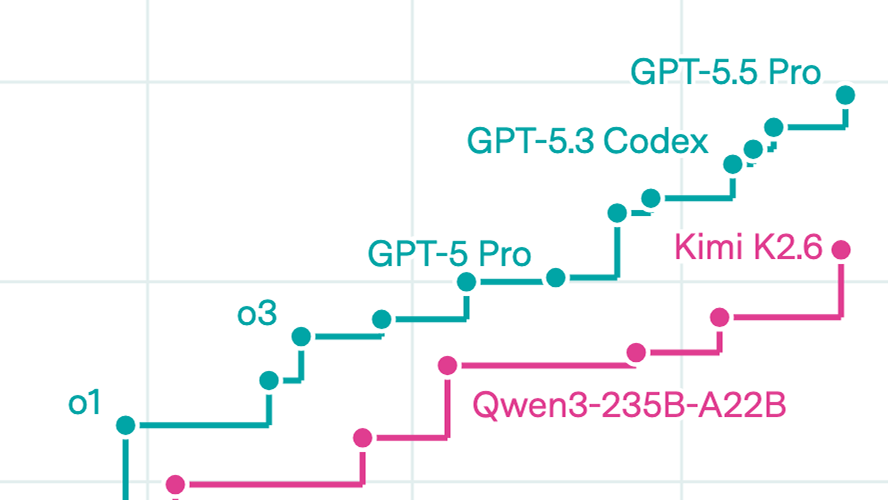
Epoch's Cyber ECI puts GLM-5.3 at 160, the top open weightsA model whose trained parameters are published for anyone to download and run — unlike API-only models you can access but never possess.Full definition → score, between GPT-5.4 (157, March 2026) and Claude Mythos Preview (165, April 2026), which is how Epoch derives the 6-7 month open-closed lag.
The closed frontier kept moving: Claude Opus 5.5 and GPT-6 Astra both score 171 on the Cyber ECI, about 11 points above the best open-weight model.
Epoch flags thin evidence: Opus 5.5's score rests on four Anthropic-reported benchmarks, and Opus 5.5 and GPT-6 Astra share no benchmarks, so their confidence intervals overlap almost entirely.
CAISI did not name the US models it evaluated, so Epoch attributed those results to the models it judged most likely to be leading at the time, such as GPT-6 Astra and Claude Mythos Preview.
The October refit grew the index to 76 models and 35 cyber benchmarks and lowered several top scores, Claude Mythos 5 by 3.9 points and GPT-5.6 Sol by 4.7, so earlier Cyber ECI figures are not directly comparable.
Terms in this piece · Glossary
open weights — A model whose trained parameters are published for anyone to download and run — unlike API-only models you can access but never possess.
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.