Epoch AI Benchmarks GPT-6.2 Astra: ECI Parity, Weak Research Tasks
- Source
- x.com
- Date

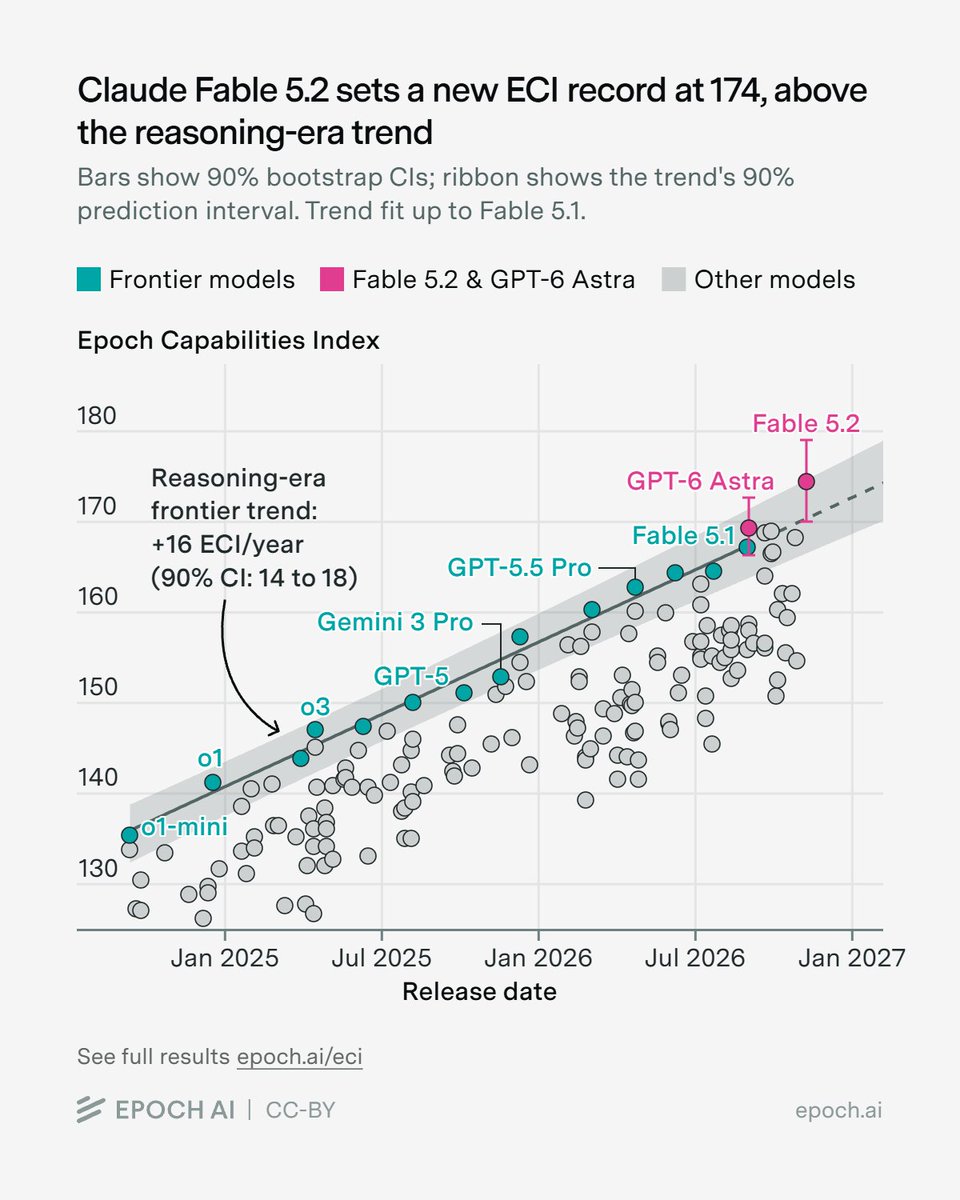
GPT-6.2 Astra scores 174 on the Epoch Capabilities Index (ECI), on par with Fable 5.2 and joining it above what the pre-Astra trend for reasoning models would have predicted. This is based on testing we did prior to launch using only our own benchmarks. The ECI is continually updated as more benchmark results become available, and so these values may change in the future.

Context
Epoch AI, a research group that tracks AI progress, scores OpenAI's GPT-6.2 Astra at 174 on its Epoch Capabilities Index (ECI), the same score it gave Anthropic's Claude Fable 5.2 on November 9. The ECI combines results from more than 50 benchmarks into one scale, Epoch's documentation explains. It estimates how hard each is by comparing models that were tested on several of them, so a model scores higher by doing well on harder benchmarks. That lets Epoch compare models released years apart, after any single benchmark has become too easy to separate them.
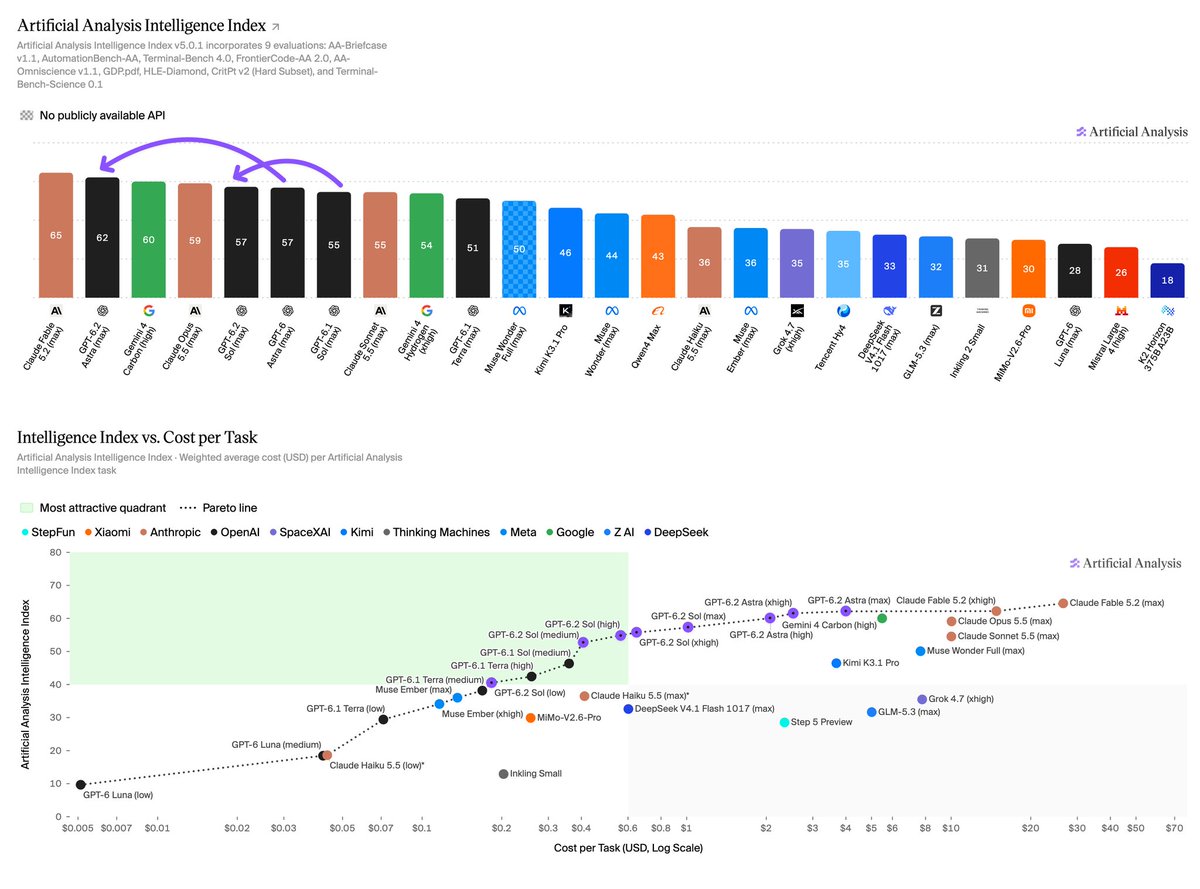
The two models are effectively tied, and Epoch's own numbers show why. Its published scores put GPT-6.2 Astra at 174.17 and Fable 5.2 at 173.5, with 90% credible intervals, the range Epoch considers likely for each true score, of 170.29 to 178.58 and 170.09 to 177.36. The ranges almost coincide, so the index cannot say which model is more capable. Both sit four to five points above GPT-6 Astra's 169.2, the top score until Fable 5.2 arrived. Artificial Analysis, using a different set of tests, also places the two at the top but puts Fable 5.2 ahead, with GPT-6.2 Astra second on its Intelligence Index.
Epoch's other claim is that both models beat its forecast. The chart in the post draws a frontier trend for reasoning models of 16 ECI points per year (90% interval 14 to 18), fitted to models up to Fable 5.1, which was released just before the first GPT-6 Astra, so it describes progress before the Astra generation. GPT-6.2 Astra sits above that trend line, though on the chart it appears to fall inside the shaded band marking the trend's 90% prediction interval. Epoch also says the score comes from pre-launch testing on its own benchmarks only, and that the index is continually updated and may change as more results arrive.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
Checking sign-in…
Loading comments…