automode is much safer than any other permission system out there, especially re
- Source
- x.com
- Date

automode is much safer than any other permission system out there, especially reviewing them yourself excited to announce we're rolling it out to everyone by default, with no overhead cost for the classifier https://t.co/blrgUhRyt0
Context
Thariq's claim that auto mode is safer than reviewing permission prompts yourself rests on Anthropic's own testing, which its rollout article describes. In Claude Code, auto mode replaces most approval prompts with a classifier: a separate model check on each tool call, targeted at blocking actions that are irreversible, destructive or directed outside the user's environment. When it blocks something, Claude usually looks for a safer route or asks; after three blocks in a row, or twenty in a session, Claude Code falls back to manual approvals. Thariq was quoting a ClaudeDevs announcement that gives the same 89% figure.
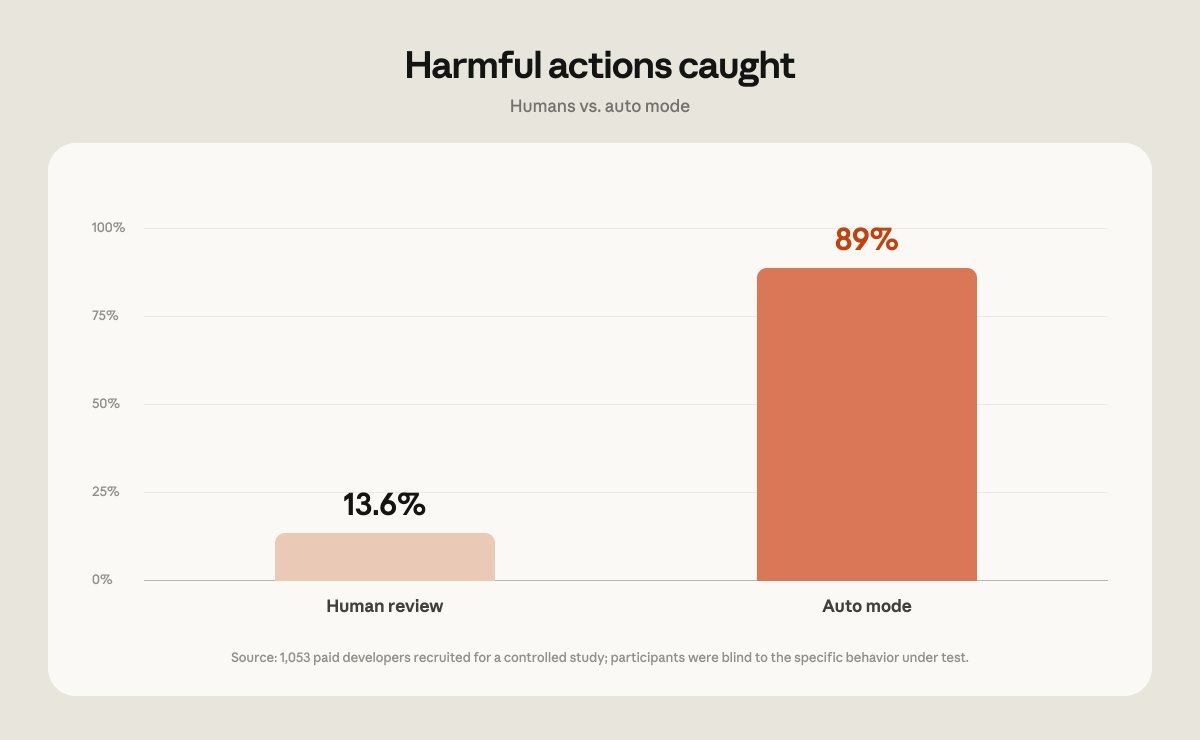
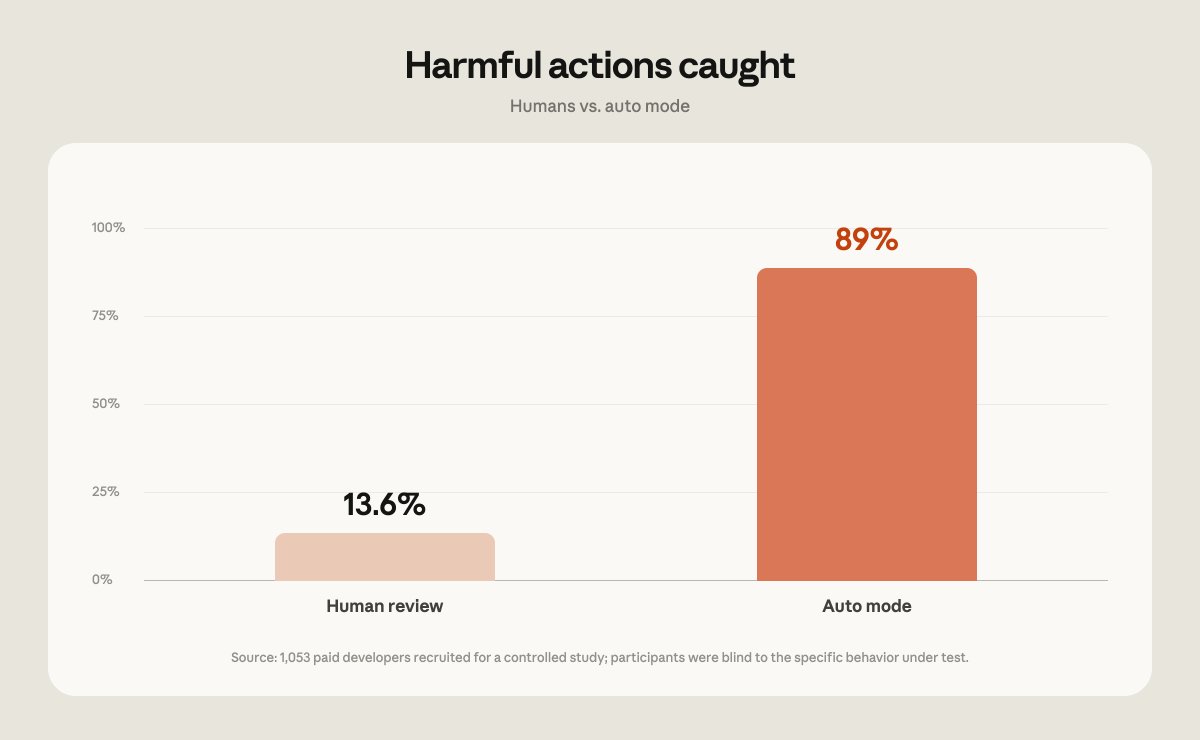
The headline result comes from a controlled study with 1,053 paid testers working in a test environment. Partway through each session, one permission prompt was swapped for a clearly dangerous command. Testers caught it 13.6% of the time, while auto mode blocked 89% of the same commands. Anthropic also reports that users approve 97% of permission prompts, which it reads as many people clicking through by habit. That supports Thariq's comparison with reviewing prompts yourself, but the study compares auto mode with manual review in Claude Code, not with other products' permission systems. Anthropic's technical write-up, covered in an earlier Intel item, adds the cost: the full classifier missed 17% of 52 real overeager actions in its , and against careful manual approval it calls auto mode arguably a regression.
"No overhead cost" refers to . The classifier uses a small number of extra tokens per tool call, and from August 7 Anthropic stopped charging Claude Code users on Pro, Max, Ultra and Team plans for them. "Everyone by default" is narrower than it sounds: new sessions on Pro, Max and Team plans default to auto mode from August 14, users who pinned a default see no change, and the August article kept auto mode opt-in for the time being on Claude Enterprise, the Claude API and partner clouds such as Amazon Bedrock, with a stated plan to make it the default there later.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
Checking sign-in…
Loading comments…