Gemini Flash Adds Agentic Video Understanding at Up to 88% Fewer Tokens
- Source
- x.com
- Date

We’re bringing agentic video understanding to our latest Gemini models. They can now analyze videos with better accuracy while using up to 88% fewer tokens. 🧵

Instead of scanning an entire file, Gemini reasons across the video’s transcript, audio, and frames, dynamically adjusting the frame rate to pull the exact moments needed. The efficiency gains are most significant for long-form content, from 10-minute guides to multi-hour recordings. Agentic video understanding is rolling out to 3.7 Flash, 3.6 Flash, and 3.5 Flash-Lite via API in @GoogleAIStudio and coming soon in the @GeminiApp. Find out more →


Context
Google DeepMind says Gemini can now analyze video by searching it rather than reading all of it. In Google's agentic video feature, the model dynamically searches, scans and inspects target segments across frames, audio and transcripts, whereas standard processing ingests video at a fixed frames-per-second rate (1 FPS by default). That lets the model spend its effort on the moments needed to answer a question.
In DeepMind's announcement chart, Gemini 3.7 Flash used 88% fewer per query on two long-video benchmarks, 1H-VideoQA and LVBench (397.6K down to 47.7K, and 300.3K down to 36.0K), and 58.4% fewer on a third, Minerva, with higher accuracy in all three. The chart's footnote gives the conditions: high thinking level, low media resolution, and 1 FPS static processing as the baseline. These are DeepMind's results, not a fixed discount for every video.
 postGemini 4 Argon: early science results and free access for 10,000 researchers
 postGemini 4 Argon writes its own robot training simulation from video
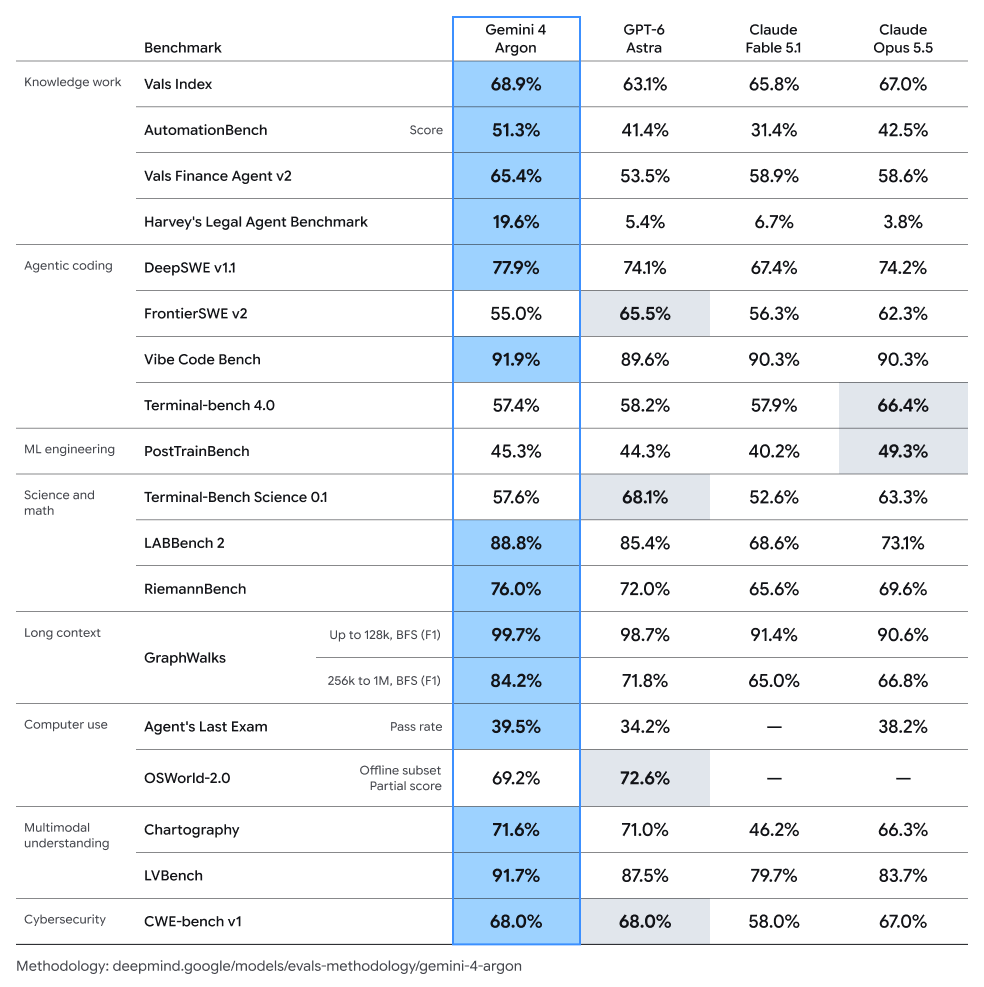 postGemini 4 Argon debuts with 1M-token output, trusted-tester access first
 postDeepMind's AlphaGenome Atlas already finding disease-causing DNA variants
Checking sign-in…
Loading comments…