Gemini 4 Carbon takes #1 on Intelligence Index, second on coding agents
- Source
- x.com
- Date

Google’s Gemini 4 Carbon is the new #1 on the Artificial Analysis Intelligence Index v5, and second only to Claude Opus 5.5 on the Artificial Analysis Coding Agent Index Gemini 4 Carbon scores 59 on Intelligence Index v5, driven by leading performance in complex reasoning, knowledge, and scientific tasks. It also has large gains in coding and knowledge work, particularly when compared to other Gemini models, but it is not leading in all these areas. As with launch of Gemini 4 Argon, Gemini 4 Carbon is being rolled out to selected users and is not yet publicly available. Google is offering a 50% launch discount, with no confirmed end date. All our charts and figures use standard pricing for both Gemini 4 Carbon and Argon. Key results for Gemini 4 Carbon with high reasoning: ➤ Gemini 4 Carbon leads the Intelligence Index v5, with the #1 score in 4 of the 9 Index evaluations: HLE-Diamond, Terminal-Bench-Science, AA-Omniscience, AutomationBench-AA. Carbon makes substantial gains elsewhere but is not leading in coding and knowledge work ➤ Behind only Claude Opus 5.5 on coding agents: With Antigravity CLI, Gemini 4 Carbon (high) scores 59 only 3 points behind Claude Code with Claude…
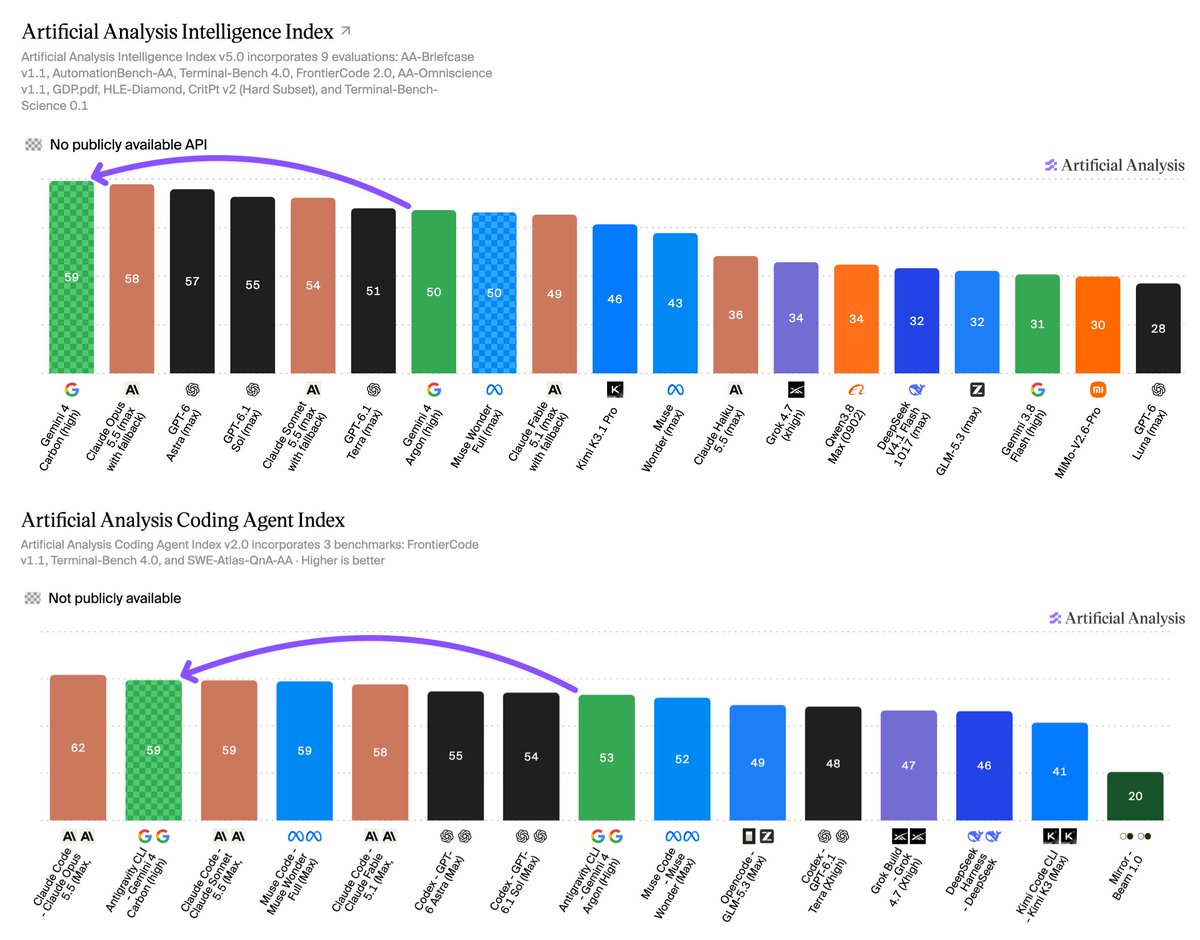
Gemini 4 Carbon trails only Claude Opus 5.5 on coding benchmarks while using 29% fewer output per task. Accuracy gains come with a rise from 4% to 11%, and access is limited to selected users for now.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- hallucination — When a model states something false with full confidence — inventing facts, citations, or APIs that don't exist.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
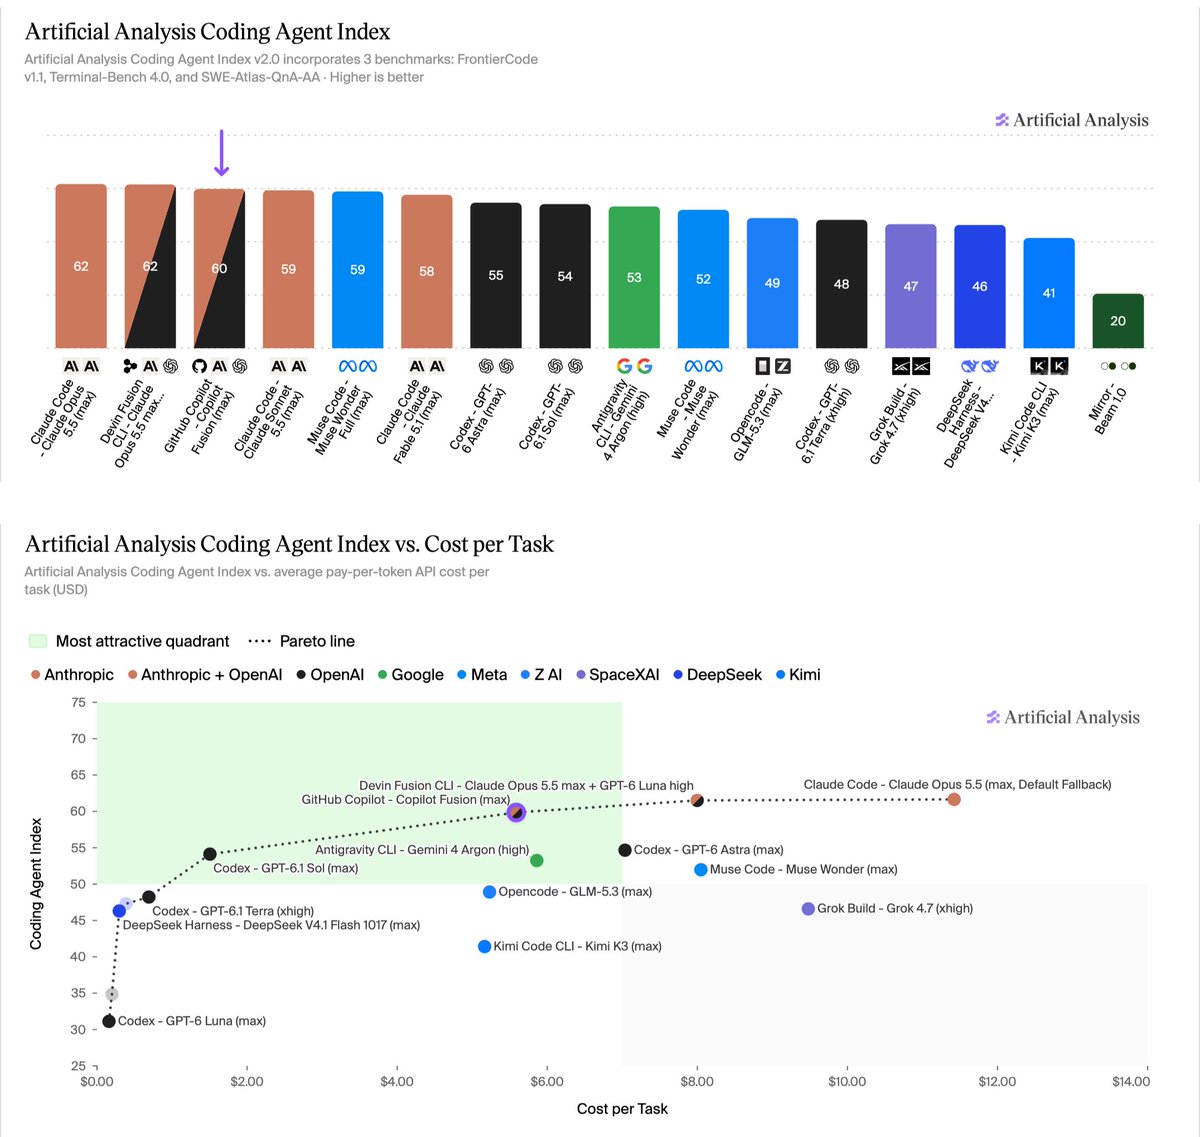 postCopilot Fusion nears Opus 5.5 coding scores at half the cost per task
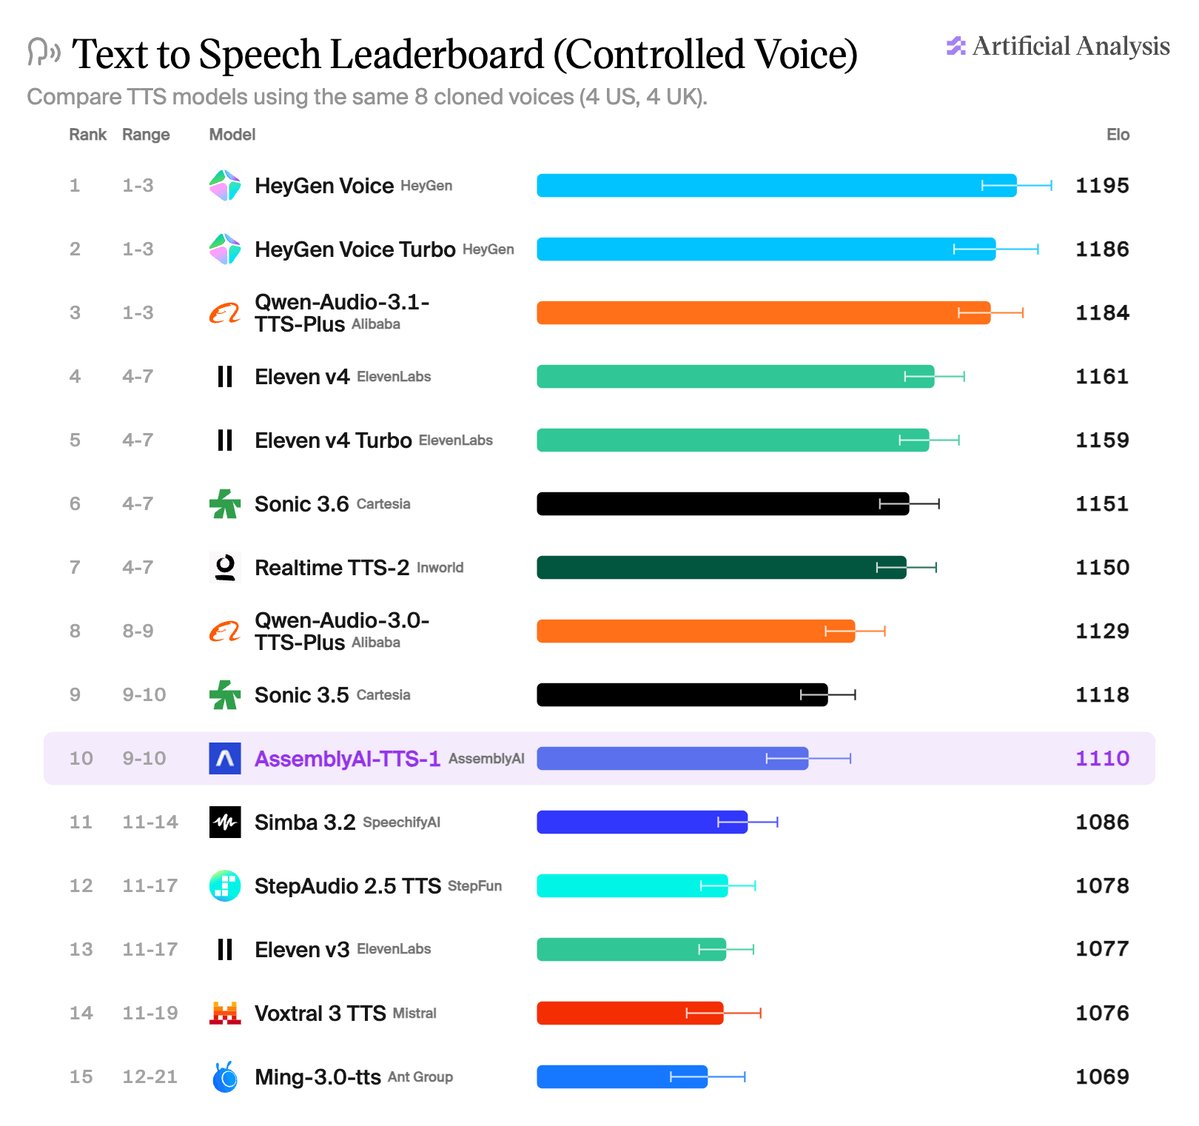 postAssemblyAI-TTS-1 debuts: top-12 voice arena rank at $15 per 1M characters
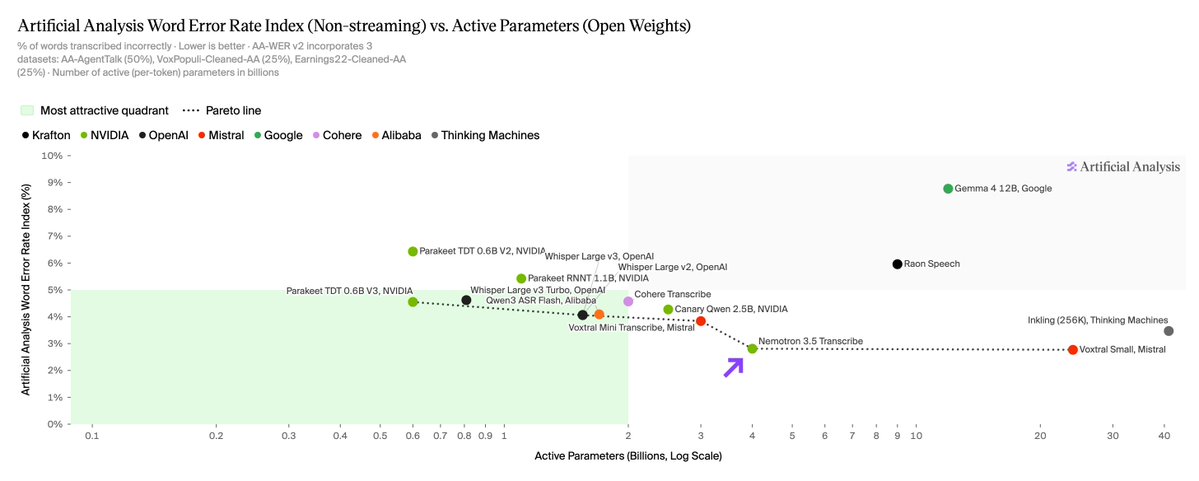 postNemotron 3.5 Transcribe ties for top open-weight STT at 4B active params
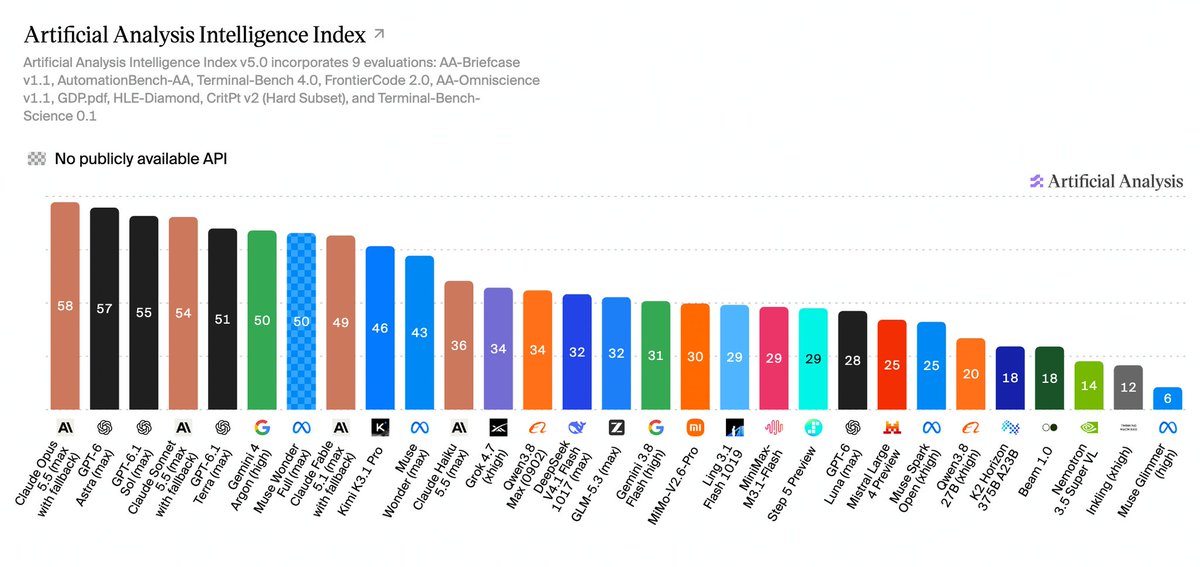 postIntelligence Index v5 goes majority-private and adds agentic coding and science
Checking sign-in…
Loading comments…