MathArena revises ArXivMath and BrokenArXiv with agent harnesses
- Source
- x.com
- Date
Context
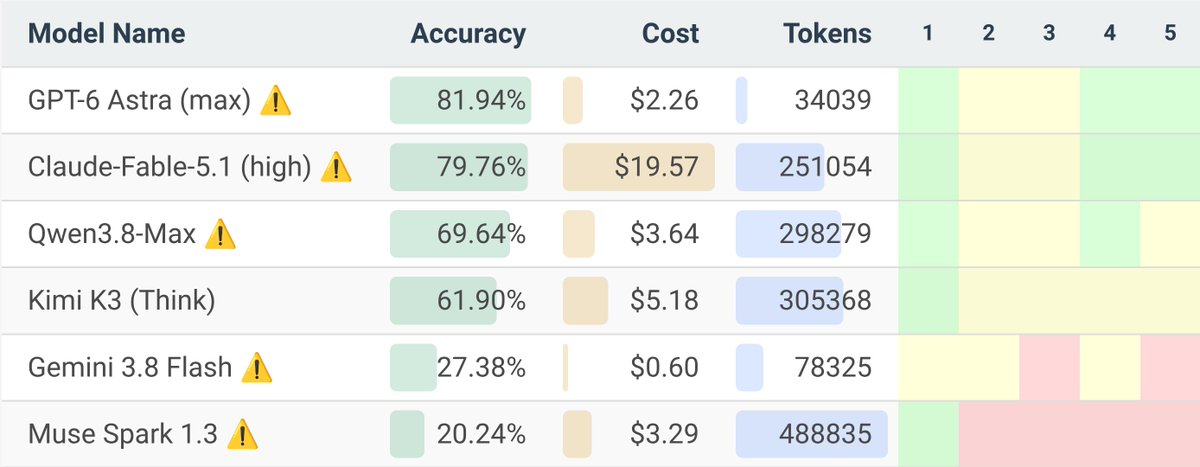
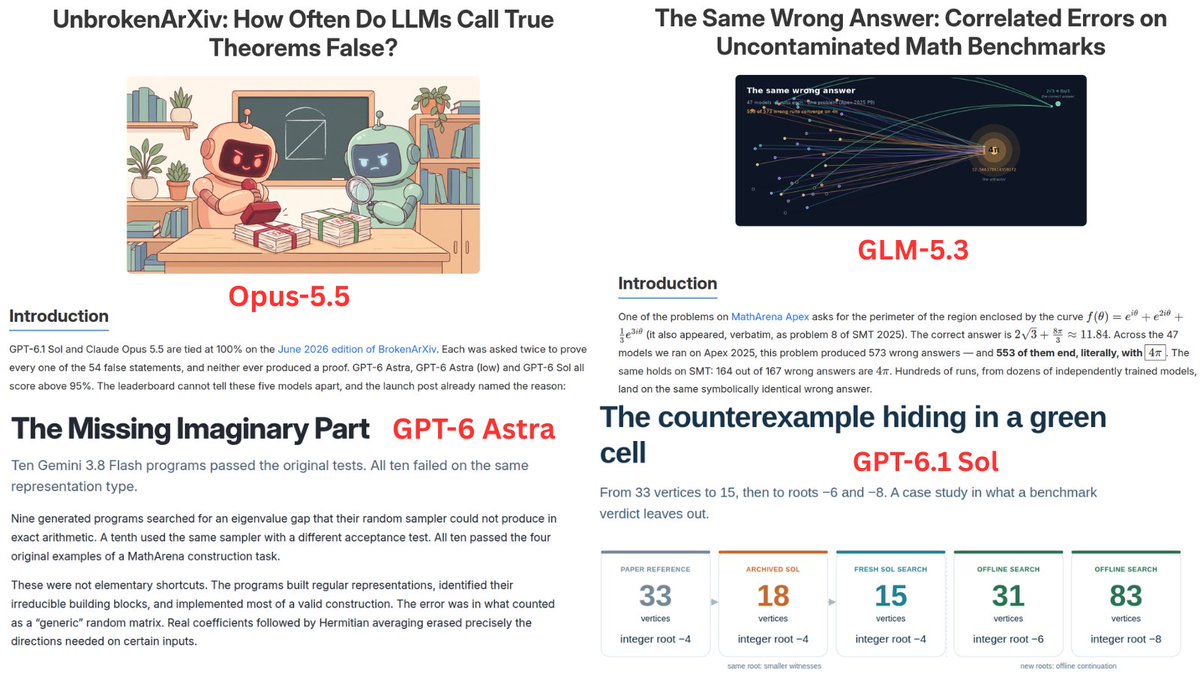
ArXivMath and BrokenArXiv, two math benchmarks, are changing both their questions and how models attempt them. In the release announcement, Jasper Dekoninck says the benchmarks now focus on conjectures refuted on ArXiv in the preceding month, and that models are run inside a instead of being called directly through their APIs.
A harness is the surrounding software that a model runs within, rather than a bare request to the model. The evaluation repository's README lists settings for harness-backed runs, including an optional exact harness version and a configuration covering the Docker image, resource limits and workspace. It describes these settings generally and not for these two benchmarks, so the supported point is limited: a result from a harness run depends on how that environment was set up as well as on which model answered.
- agent harness — The scaffolding around a model that turns it into a working agent — the loop, the tools it can call, and the rules for when to stop.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
Checking sign-in…
Loading comments…