The most dangerous part of an AI agent is not what it thinks. It is what the sys
- Source
- x.com
- Date

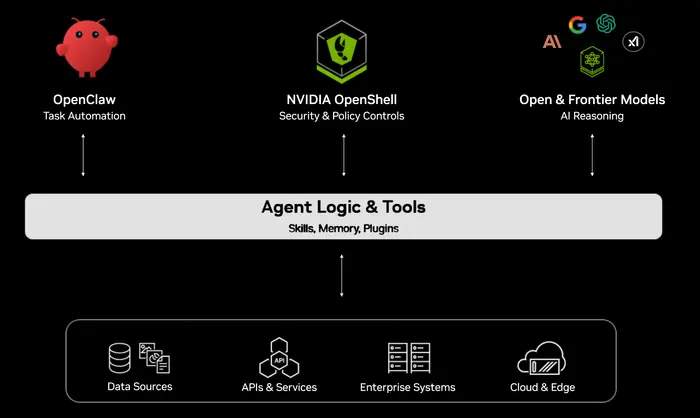
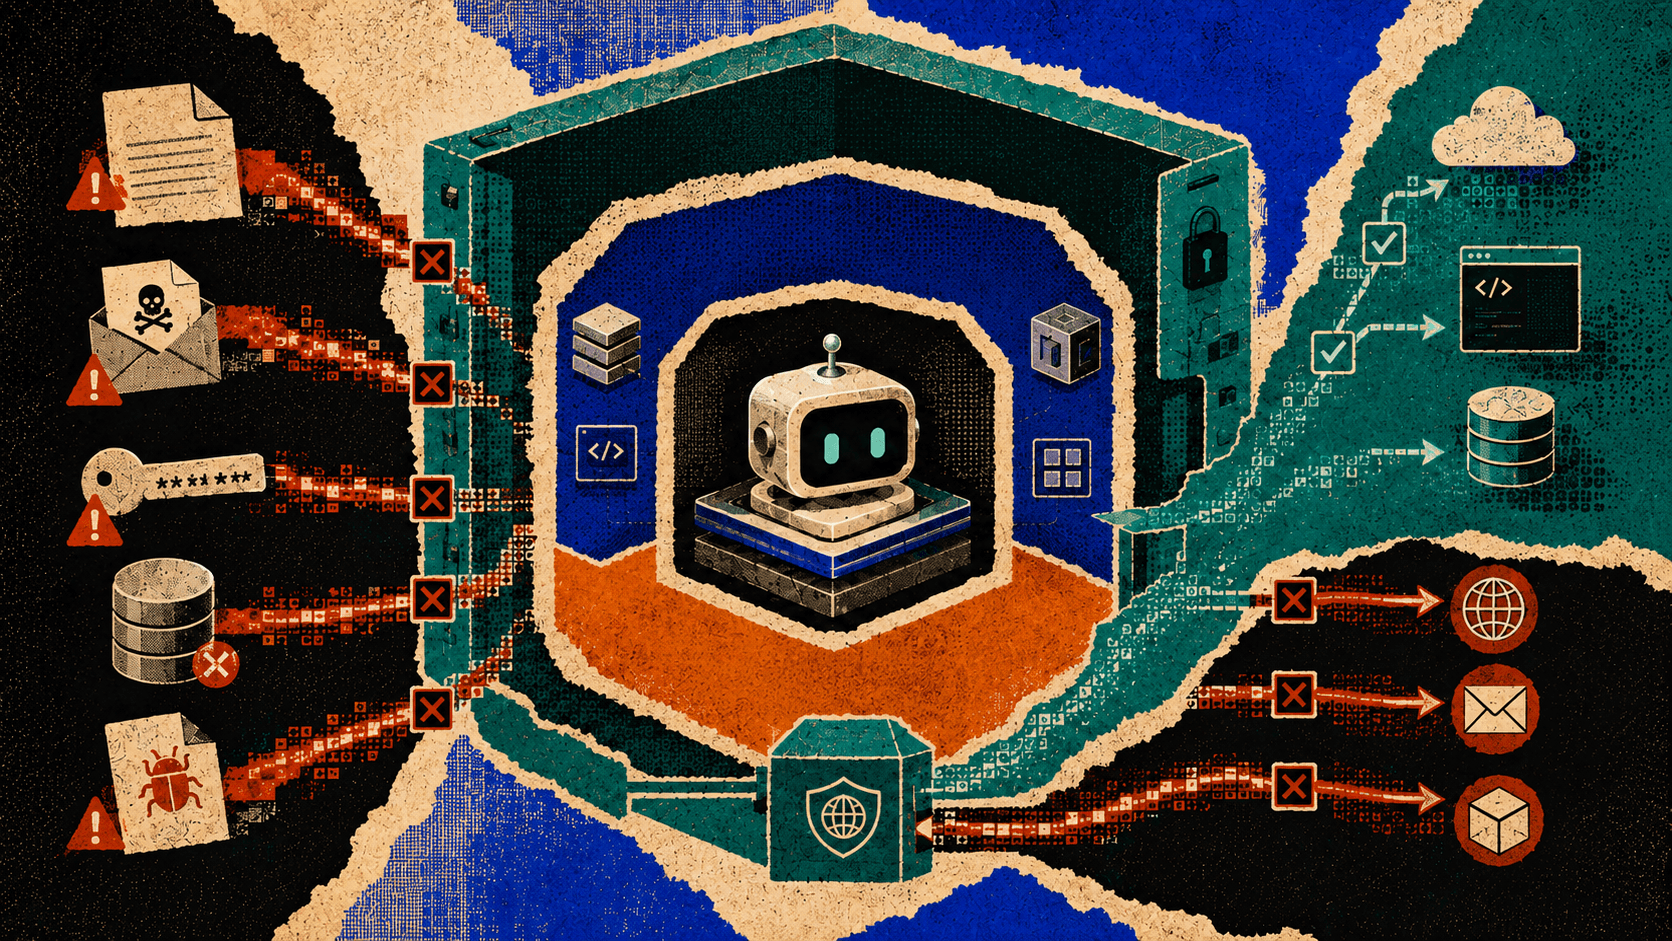
The most dangerous part of an AI agent is not what it thinks. It is what the system lets it do. Agents have already deleted 200+ emails, wiped a production database, and caused an outage while following what they believed was the correct action. Another system prompt does not fix that. Agent security is moving into three system layers: > Infrastructure: sandbox execution and keep credentials outside the agent > Runtime: reduce the attack surface and isolate each session > Network: inspect outbound requests before they leave the boundary @NVIDIAAI's NemoClaw handles the infrastructure layer with Docker, Landlock, seccomp, network namespaces, and a gateway that injects API keys only after approval. NanoClaw reduces the runtime surface with a small codebase and isolated ephemeral containers. CrabTrap treats the network as the final control point. Low-risk requests pass through static rules. High-risk requests go to an LLM judge and, when needed, a human approver. The security model changes once you assume the agent will eventually make the wrong decision.
Context
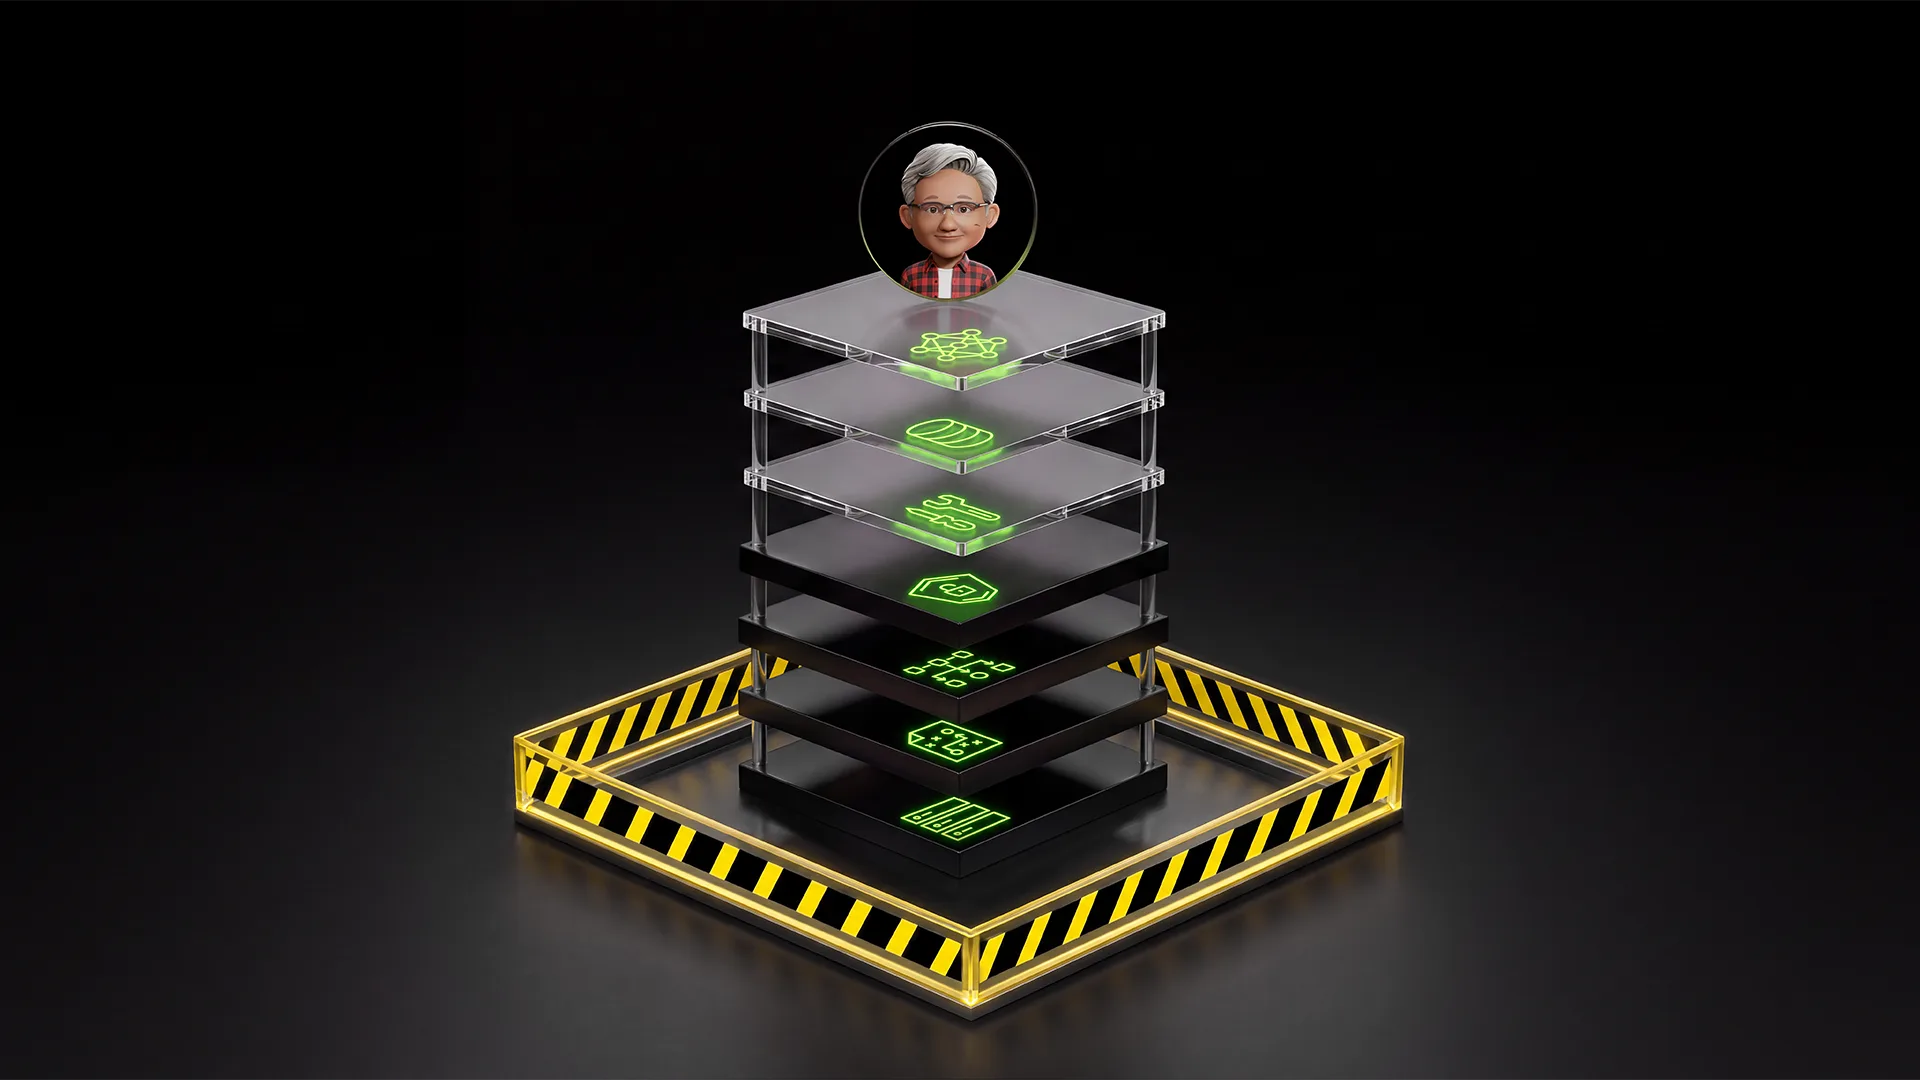
AlphaSignal argues that an 's danger lies in what the surrounding system lets it do, so the limits have to be enforced outside the model rather than written into its instructions. The post says agents have already deleted more than 200 emails, wiped a production database and caused an outage while following what they believed was the correct action, though it does not name or source those incidents. Adding another does not fix that, in AlphaSignal's view, because the design should assume the agent will eventually make the wrong decision. Andrew Ng made the same case six weeks later. He wrote that OpenWorker, an open-source he is working on, is building on NVIDIA's OpenShell and will support running each agent's commands inside a sandbox, where secret API keys, browser login credentials and access to arbitrary websites are inaccessible by default. Those restrictions, he wrote, are implemented in deterministic code rather than by prompting an LLM, which can make mistakes or be subverted by .
AlphaSignal divides that outside enforcement into three layers and names a project for each. At the infrastructure layer, NVIDIA's NemoClaw runs the agent in a sandbox built with Docker, Landlock, seccomp and network namespaces, and its gateway injects API keys only after approval, so the credentials stay outside the agent. At the runtime layer, NanoClaw shrinks what can be attacked by keeping its codebase small and isolating each session in a short-lived container. At the network layer, CrabTrap checks outgoing requests before they leave: static rules pass low-risk requests, while high-risk ones go to an LLM judge and, when needed, a human approver. These project descriptions are AlphaSignal's summary.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- system prompt — The standing instructions a model receives before any user input — defining its role, rules, tools, and tone for the whole conversation.
- agent harness — The scaffolding around a model that turns it into a working agent — the loop, the tools it can call, and the rules for when to stop.
- prompt injection — An attack that hides instructions in content an AI will read — a webpage, email, or document — tricking it into following the attacker instead of the user.
Checking sign-in…
Loading comments…