OFASys: Enabling Multitask Learning with One Line of Code!
- Source
- qwenlm.github.io
- Author
- Qwen Team
- Date
Context
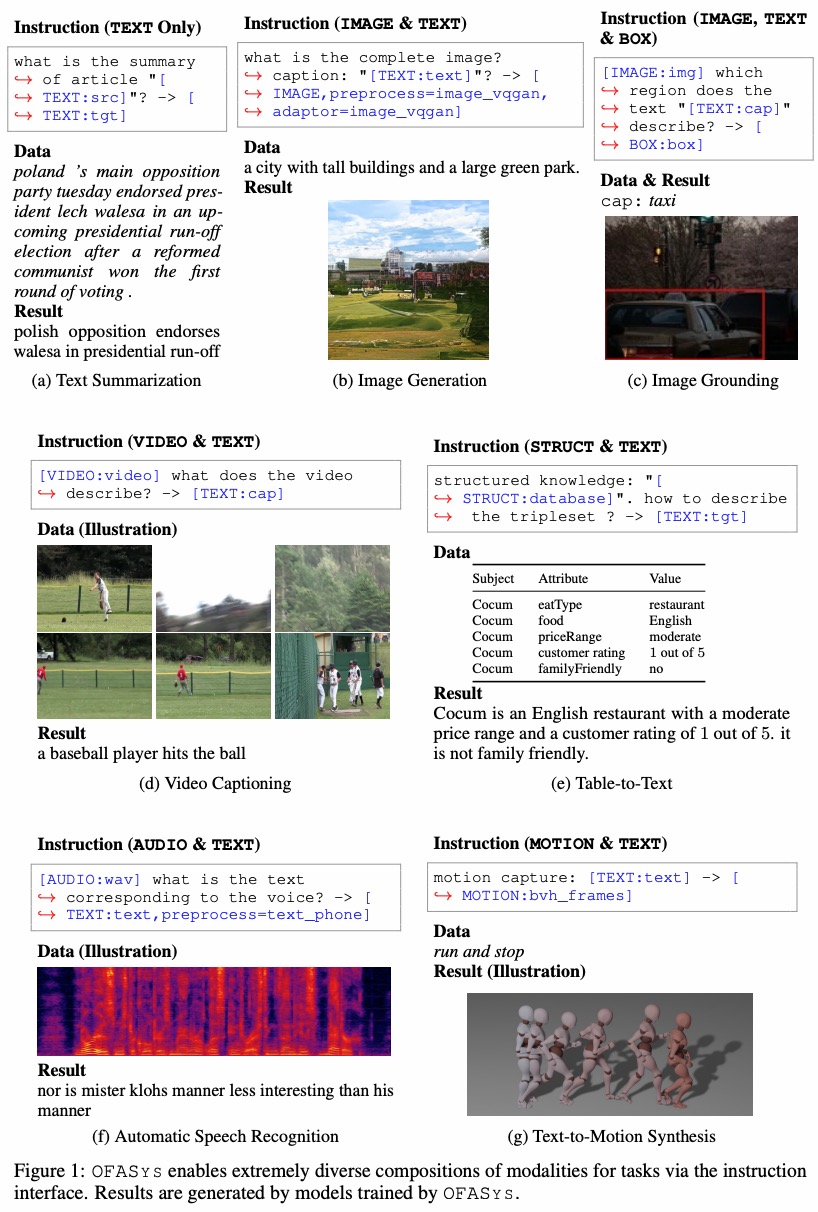
OFASys lets researchers describe a task's inputs and outputs through a shared instruction format, then assembles the processing needed to train or run it. In the Qwen team's system description, an image-captioning task names the image input and the text output; the framework selects components that convert those data types into sequences a shared model can process.
For multiple tasks, OFASys shares trainable components and schedules work across tasks and devices. Its one-line interface therefore describes the task while the framework handles much of the underlying coordination. This can make experiments spanning text, images, and other data types easier to organize; the datasets and model training remain part of the work.
- multimodal — A model that works with more than text — reading images, audio, or video, and sometimes generating them too.
“We all see an opportunity towards a real generalist model by multimodal multitask learning.”
“For example, it is hard to set up multiple tasks concerning multiple modalities, and it is hard to organize multitask learning, e.g., how to batchify your data and how to make your training stable.”
Checking sign-in…
Loading comments…