Generalizing an LLM from 8k to 1M Context using Qwen-Agent
- Source
- qwenlm.github.io
- Author
- Qwen Team
- Date
Context
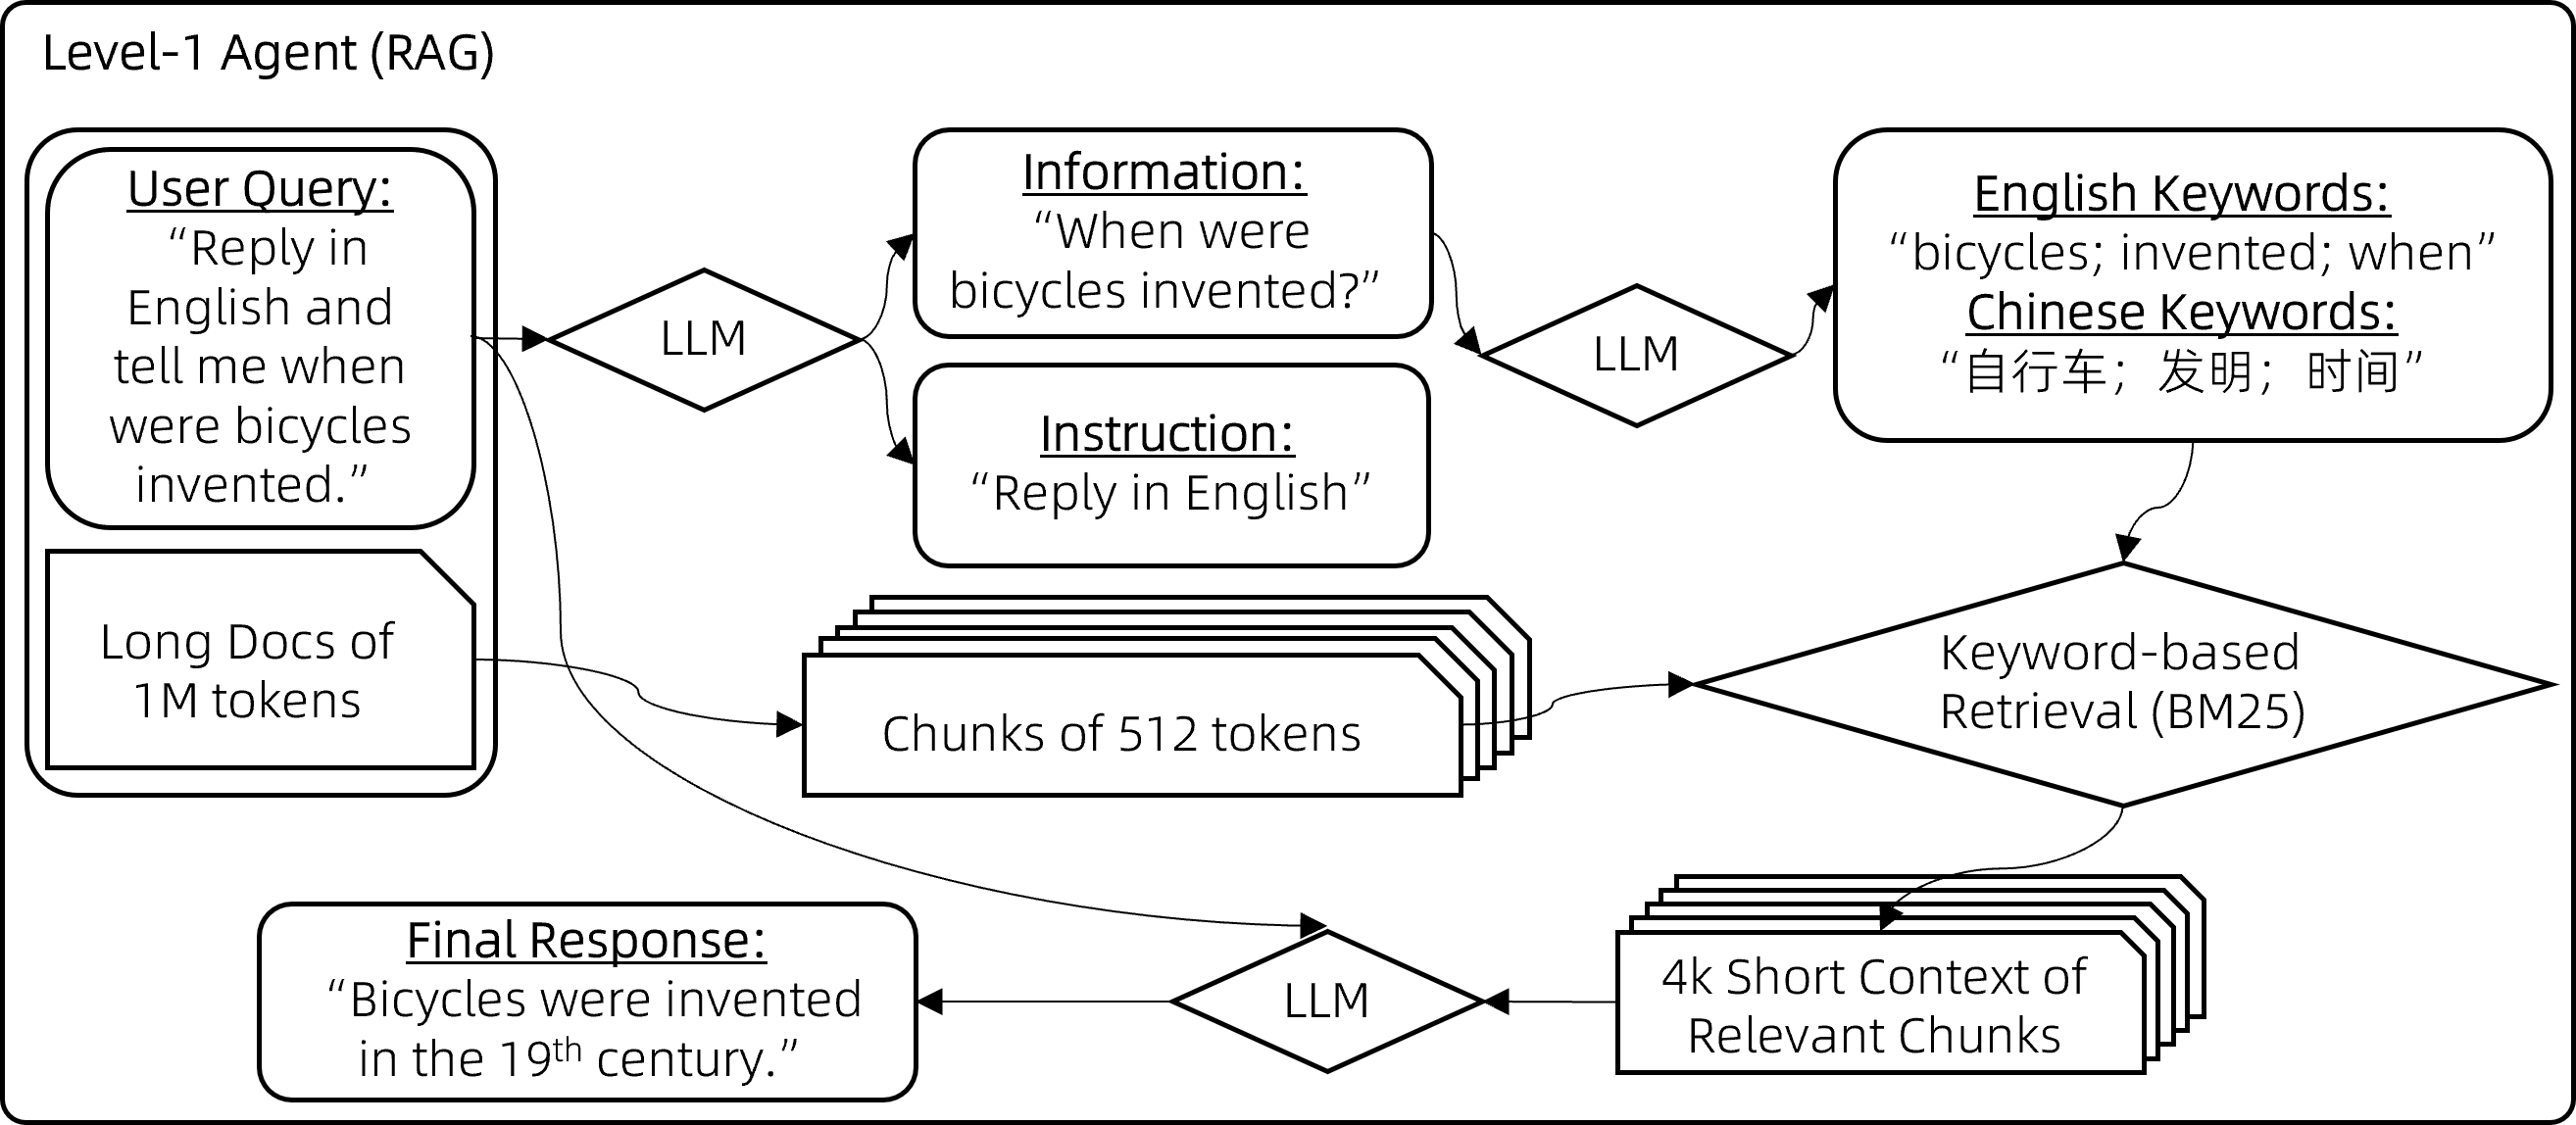
Qwen's million-token processes a long document through many smaller model calls. The Qwen-Agent design splits text into chunks, asks the model to extract relevant passages, and uses keyword retrieval to fit supporting material into its limited . For questions requiring several connected facts, an outer agent asks successive subquestions and retains the answers.
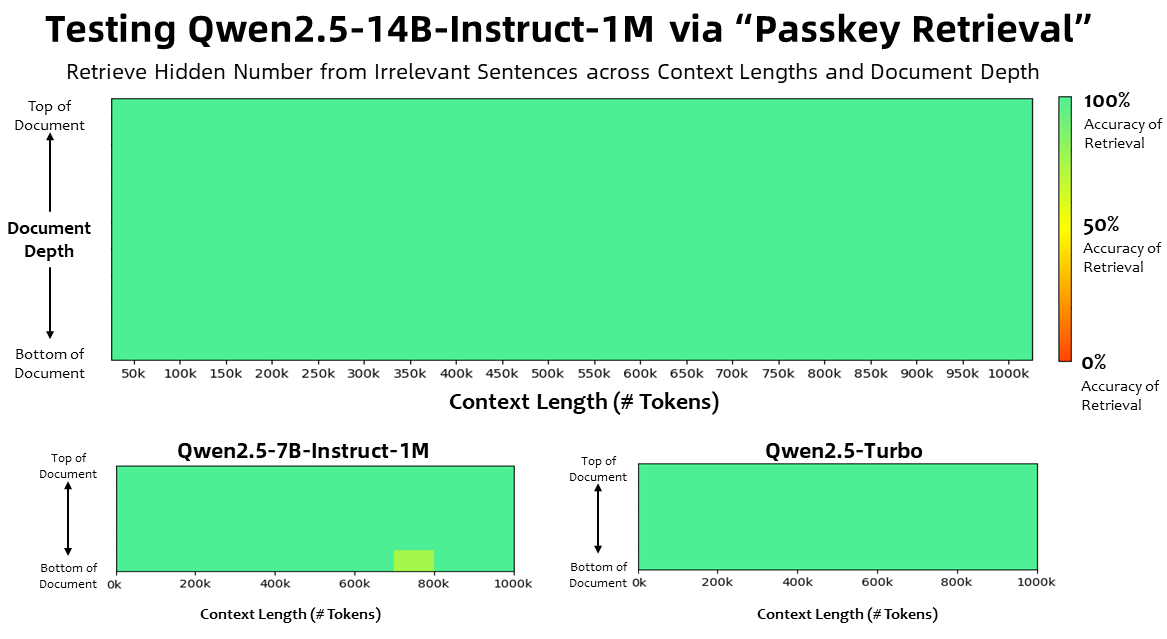
This expands the document the system can search without enlarging the model's native context window. The million-token demonstration tested finding one hidden fact. More demanding comparisons used 256,000-token benchmarks, and the authors explicitly lacked a reliable million-token for real-world comprehension. The supported advance is a document-processing workflow, with broader comprehension still needing evaluation.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- RAG — Retrieval-augmented generation — fetching relevant documents first and pasting them into the model's context so it answers from your data instead of memory.
Checking sign-in…
Loading comments…