Qwen1.5-MoE: Matching 7B Model Performance with 1/3 Activated Parameters
Source
qwenlm.github.io
Author
Qwen Team
Date
Context
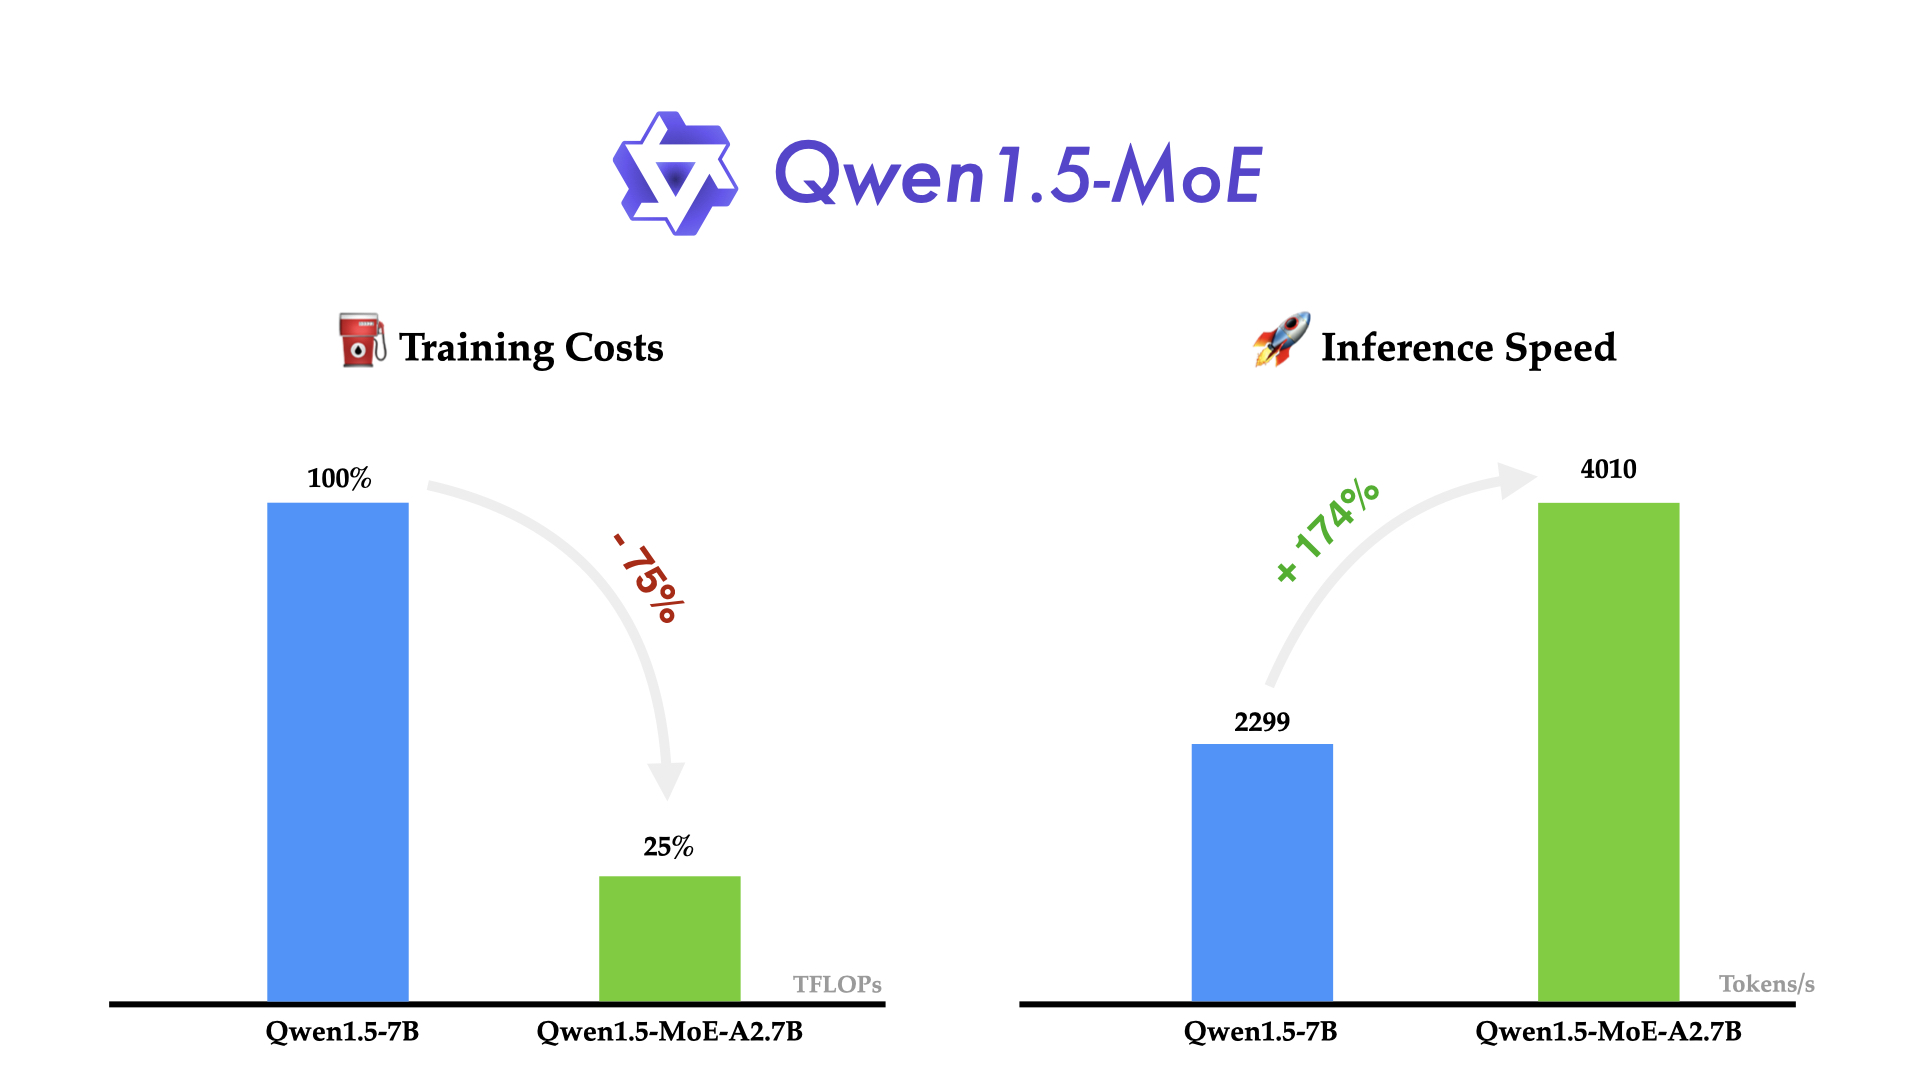
Qwen's Qwen1.5-mixture-of-expertsA model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.Full definition → uses only part of its learned parameters for each input, but the full model is much larger than its 2.7B active-parameter label suggests. The architecture and size table list 14.3 billion total parameters, with 2.7 billion active.
The model divides computation among expert components. Four shared experts are always active, alongside four selected from 60 other experts. This reduces computation at each step while retaining a larger collection of weights. The team reports competitive results against contemporary 7B models and explicitly acknowledges higher memory requirements. Active parameter count therefore helps explain compute use, but cannot stand in for the model's storage footprint.
Terms in this piece · Glossary
mixture-of-experts — A model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.