voyage-multilingual-2 targets non-English retrieval with 32K context
- Source
- x.com
- Date

🌍📢 Launching our multilingual embeddings, voyage-multilingual-2! 👑 Average 5.6% gain on evaluated languages, including French, German, Japanese, Spanish, and Korean 📚 32K context length 🛒 On AWS Marketplace Check us out! 👉🏼 The first 50M tokens are on us. #RAG #LLM
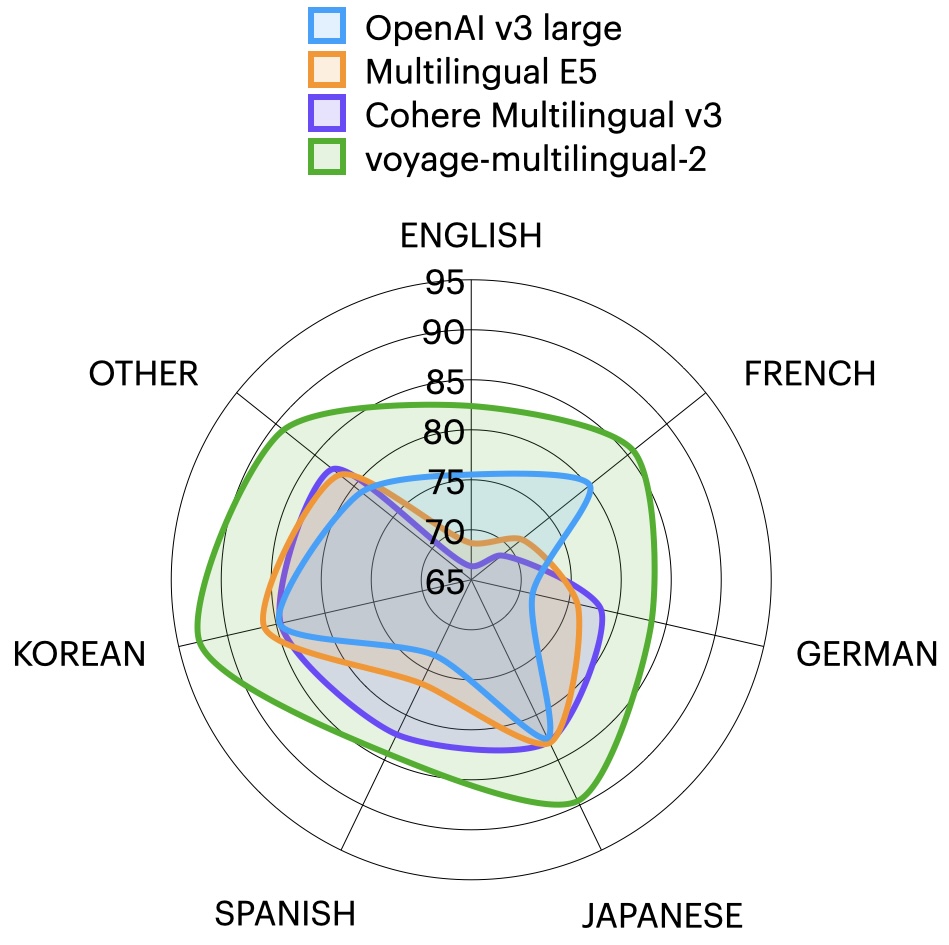
More details in our blog post: https://t.co/KM5NZJ0jOa We support academic retrieval research and benchmarking! Please email us at contact@voyageai.com for more 🆓 tokens.
Context
Voyage AI's voyage-multilingual-2 represents queries and documents as numbers that a search system can compare, with a focus on retrieval across multiple languages. Its June 2024 release report describes evaluations covering 27 languages and an input limit of 32,000 .
The reported 5.6% average advantage concerns a ranking metric that rewards placing relevant documents near the top of the first ten results. It compares the model with the next-best evaluated alternative. This is evidence about finding useful source material in those tests, rather than a measurement of the accuracy of answers subsequently generated from it.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- embedding — A list of numbers representing a piece of text's meaning, so that similar meanings end up numerically close and can be searched.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
Checking sign-in…
Loading comments…