voyage-multimodal-3.5 brings video into the retrieval embedding space
- Source
- x.com
- Date

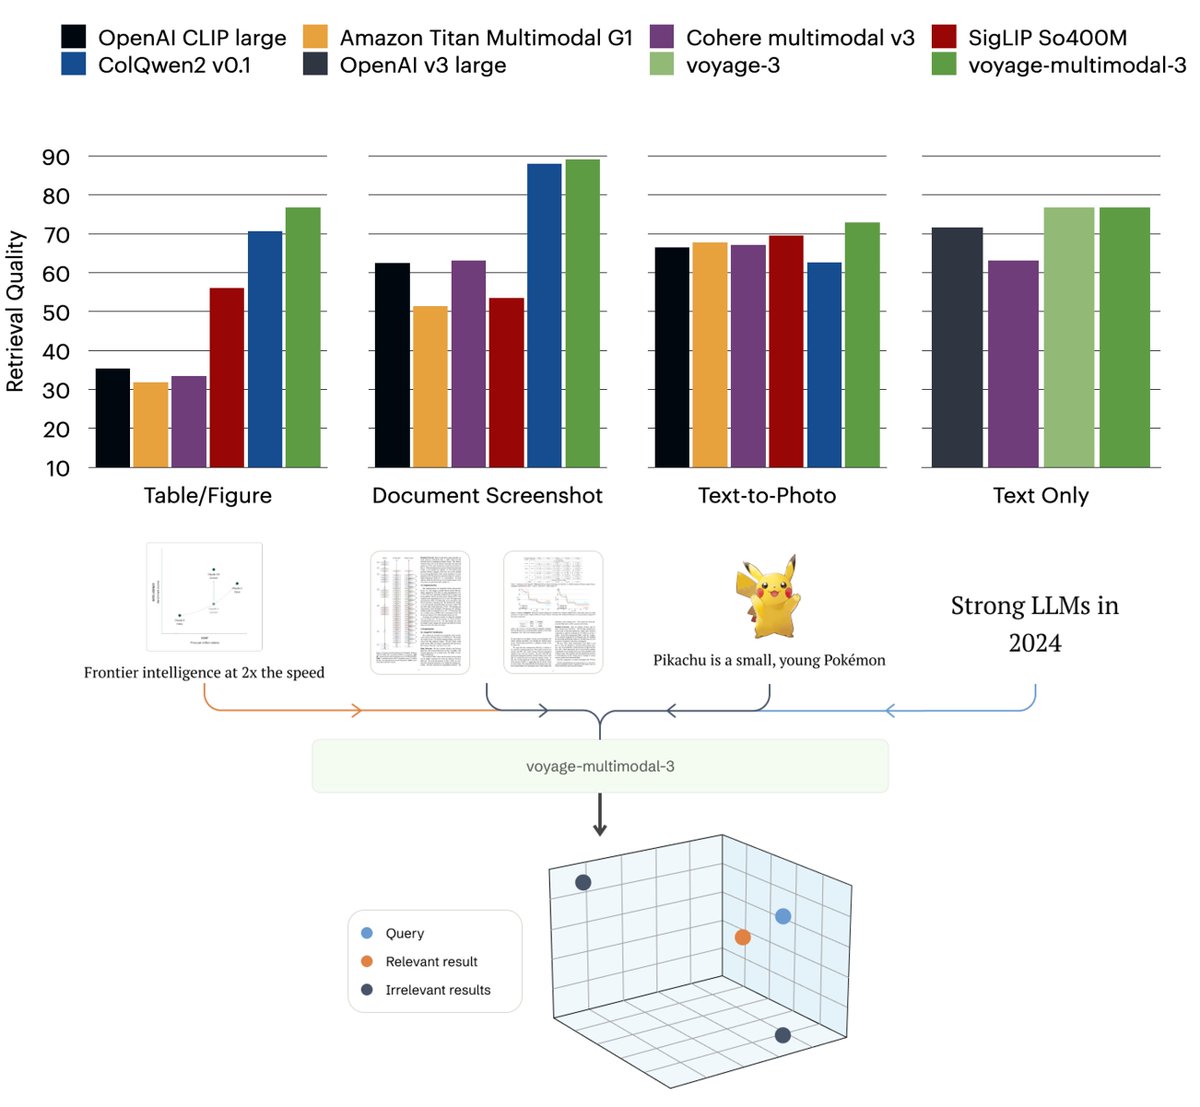
📢 Announcing voyage-multimodal-3.5: a new multimodal retrieval frontier with video support voyage-multimodal-3.5 outperforms Google Multimodal Embedding 001, Cohere Embed v4, Amazon Nova 2 Multimodal, and voyage-multimodal-3 by 30.57%, 2.26%, 8.38%, and 3.03% respectively on visual document retrieval

voyage-multimodal-3.5 is 4.65% more accurate than Google Multimodal Embedding 001 across video retrieval datasets

voyage-multimodal-3.5 matches state-of-the-art performance for standard text retrieval, outperforming Cohere v4, Amazon Nova 2 Multimodal, and voyage-multimodal-3 by 3.49%, 8.48%, and 5.22%, respectively

voyage-multimodal-3.5 is available today! The first 200 million tokens and 150B pixels are free. Get all the details in the release blog: https://t.co/Oq6BN5P2UQ
Context
Voyage AI's voyage--3.5 extends its earlier text-and-image model to video retrieval. It takes an ordered sequence of video frames and converts it into a numerical representation that can be compared with a text query. Text, images and video therefore become searchable within the same system, according to the release article.
Long videos still need preparation. The company recommends splitting them into coherent scenes, using transcript boundaries when available, and reducing frame rate or resolution if necessary to fit the input limit. The useful capability is searching for relevant scenes by description; it does not require treating an entire recording as one search result.
- multimodal — A model that works with more than text — reading images, audio, or video, and sometimes generating them too.
- embedding — A list of numbers representing a piece of text's meaning, so that similar meanings end up numerically close and can be searched.
Checking sign-in…
Loading comments…