DeepSeek-V4-Flash-0731
- Source
- simonwillison.net
- Author
- Simon Willison
- Date
Context
A model's reasoning setting can change the result of a trial. Simon Willison illustrates this with DeepSeek V4 Flash 0731: in the July 31 test, Willison preferred the pelican-on-a-bicycle illustration produced with high reasoning effort to the one produced at the default setting.
The published interaction log records the same request to generate SVG image code and explicitly marks the high-effort run. This is a useful example of why an should record model settings. It remains one person's comparison on one drawing task.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
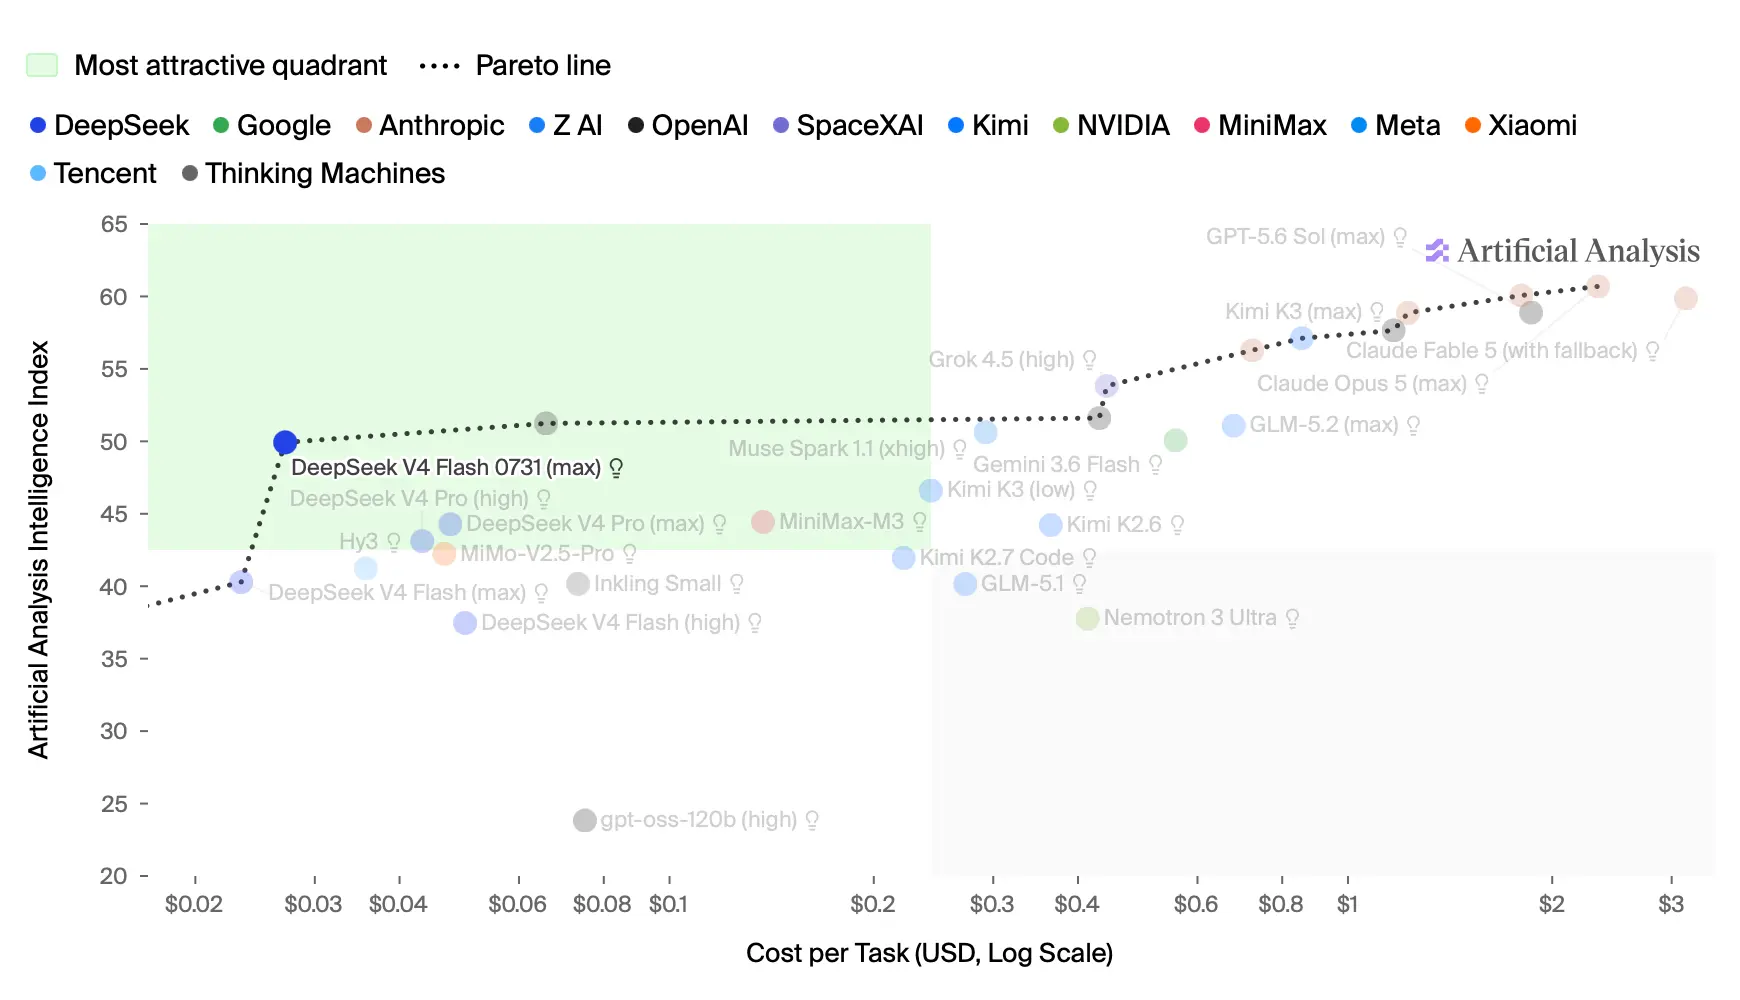
“It's 304 billion parameters - 167GB on Hugging Face - but it appears to punch well above its weight.”
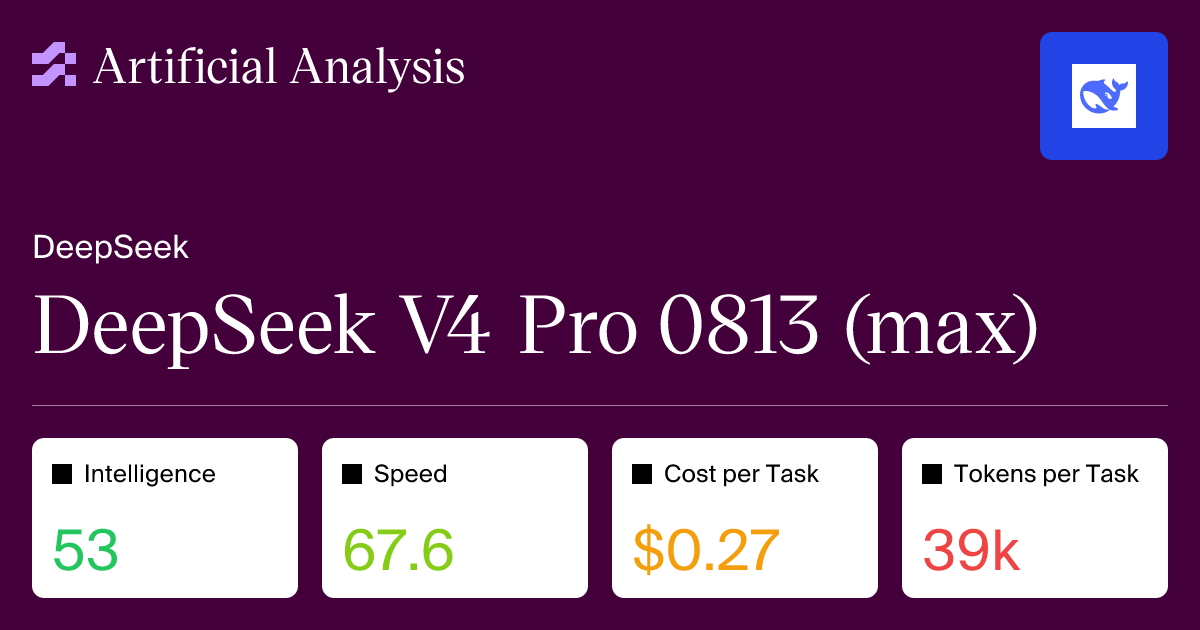
“Artificial Analysis rank it ahead of MiniMax M3 - a 428B model.”
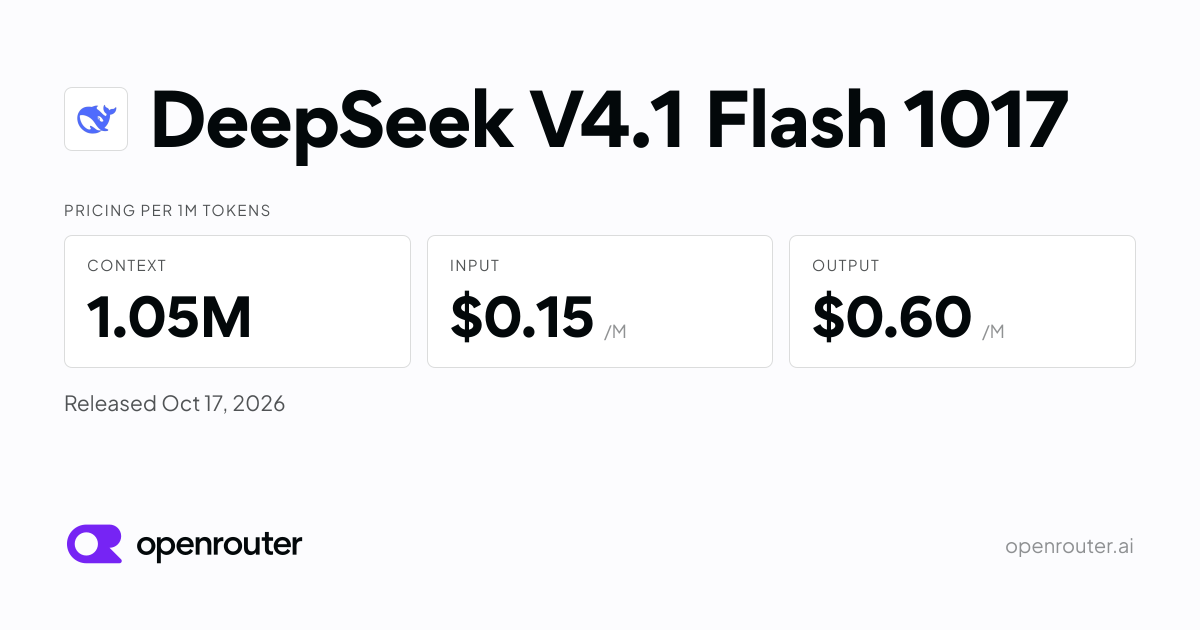
“It's $0.14/million input and $0.27/million output pricing means this may currently be the best value-per-intelligence model out there.”
 articlePrompting Fable 5.2: effort, ownership and harness changes that matter
 articleAuto mode is now the default in Claude Code for Pro, Max, and Team plans
 articleNow we have a timeline of the OpenAI accidental attack against Hugging Face
 articleMoonlight & Mayhem (Raccoon Heist by Codex + GPT-5.6 Sol Ultra)
Checking sign-in…
Loading comments…