MEMENTO: Learning Context Management for Long Context Processing Agents
- Source
- arxiv.org
- Author
- Yunfan Zhang, Taehoon Hwang, Kathleen McKeown, Smaranda Muresan
- Date
Context
MEMENTO is an agent that learns to manage its own by writing notes, and the paper's abstract reports that this lets an 8-billion-parameter model answer questions about very long books far more accurately, at a fraction of the cost of much larger models (arXiv). The technique is : when the window fills, the agent replaces its history with a self-written note and keeps reading in a fresh window. The authors say off-the-shelf agentic models including GPT-5.5 and GLM-5.3 often write ineffective notes, and that reinforcement learning on its own rarely discovers good note-taking.
Their fix has two stages. They first fine-tune Qwen's Qwen3-8B on synthetic trajectories whose notes were written in hindsight, so the model sees what a useful note looks like, then train further with reinforcement learning using a reward that combines answer correctness, note-quality heuristics and confidence . According to the abstract, on four book-level question-answering benchmarks with books up to 2.5 million tokens, accuracy rose from 36.9% to 67.8% while the agent never held more than 20,000 tokens in context. The authors report it beat a GPT-5.5 agent in the same (13.1%) and full-book context (56.7%) at under 1/50 the cost, and nearly matched a roughly 100 times larger GLM-5.3 agent (69.3%) at 1/9 the cost. It came within 6.4 points of GLM-5.3 reading the full book, at 1/26 the cost.
These are the authors' numbers from the abstract, on book question answering specifically. Other recent papers measure what compaction loses, such as Compact-Bench for coding agents and Lost in Compaction on user instructions lost under compaction. MEMENTO takes the other side of the problem and tries to train a model to write better notes.
- The authors report that off-the-shelf agentic models, including GPT-5.5 and GLM-5.3, often write ineffective compaction notes, and that reinforcement learning alone rarely discovers useful note-taking behavior.
- MEMENTO is trained in two stages: fine-tuning on synthetic trajectories with notes written in hindsight, then RL with a reward that combines answer correctness, note-quality heuristics and confidence calibration.
- On book-level QA with books up to 2.5M tokens, the 8B agent never held more than 20K tokens in context, yet beat a GPT-5.5 agent in the same harness (13.1%) and full-book context (56.7%) at under 1/50 the cost, per the abstract.
- Although trained only to compact into a fresh window, the model extended at test time to context folding and confidence-based backtracking, and came within 1.5 points of a roughly 100x larger GLM-5.3 agent (69.3%) at 1/9 the cost.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
- context compaction — Summarizing an agent's earlier conversation to free room in the context window so a long session can keep going.
- calibration — How well a model's confidence matches reality — a calibrated model saying "90% sure" is right about 90% of the time.
- agent harness — The scaffolding around a model that turns it into a working agent — the loop, the tools it can call, and the rules for when to stop.
 articleWhen Learned Context Planning Fails to Beat Strong Retrieval: A Controlled Study of Planning, Routing, and Reranking for Long-Context QAYingrui Li, Han Chen
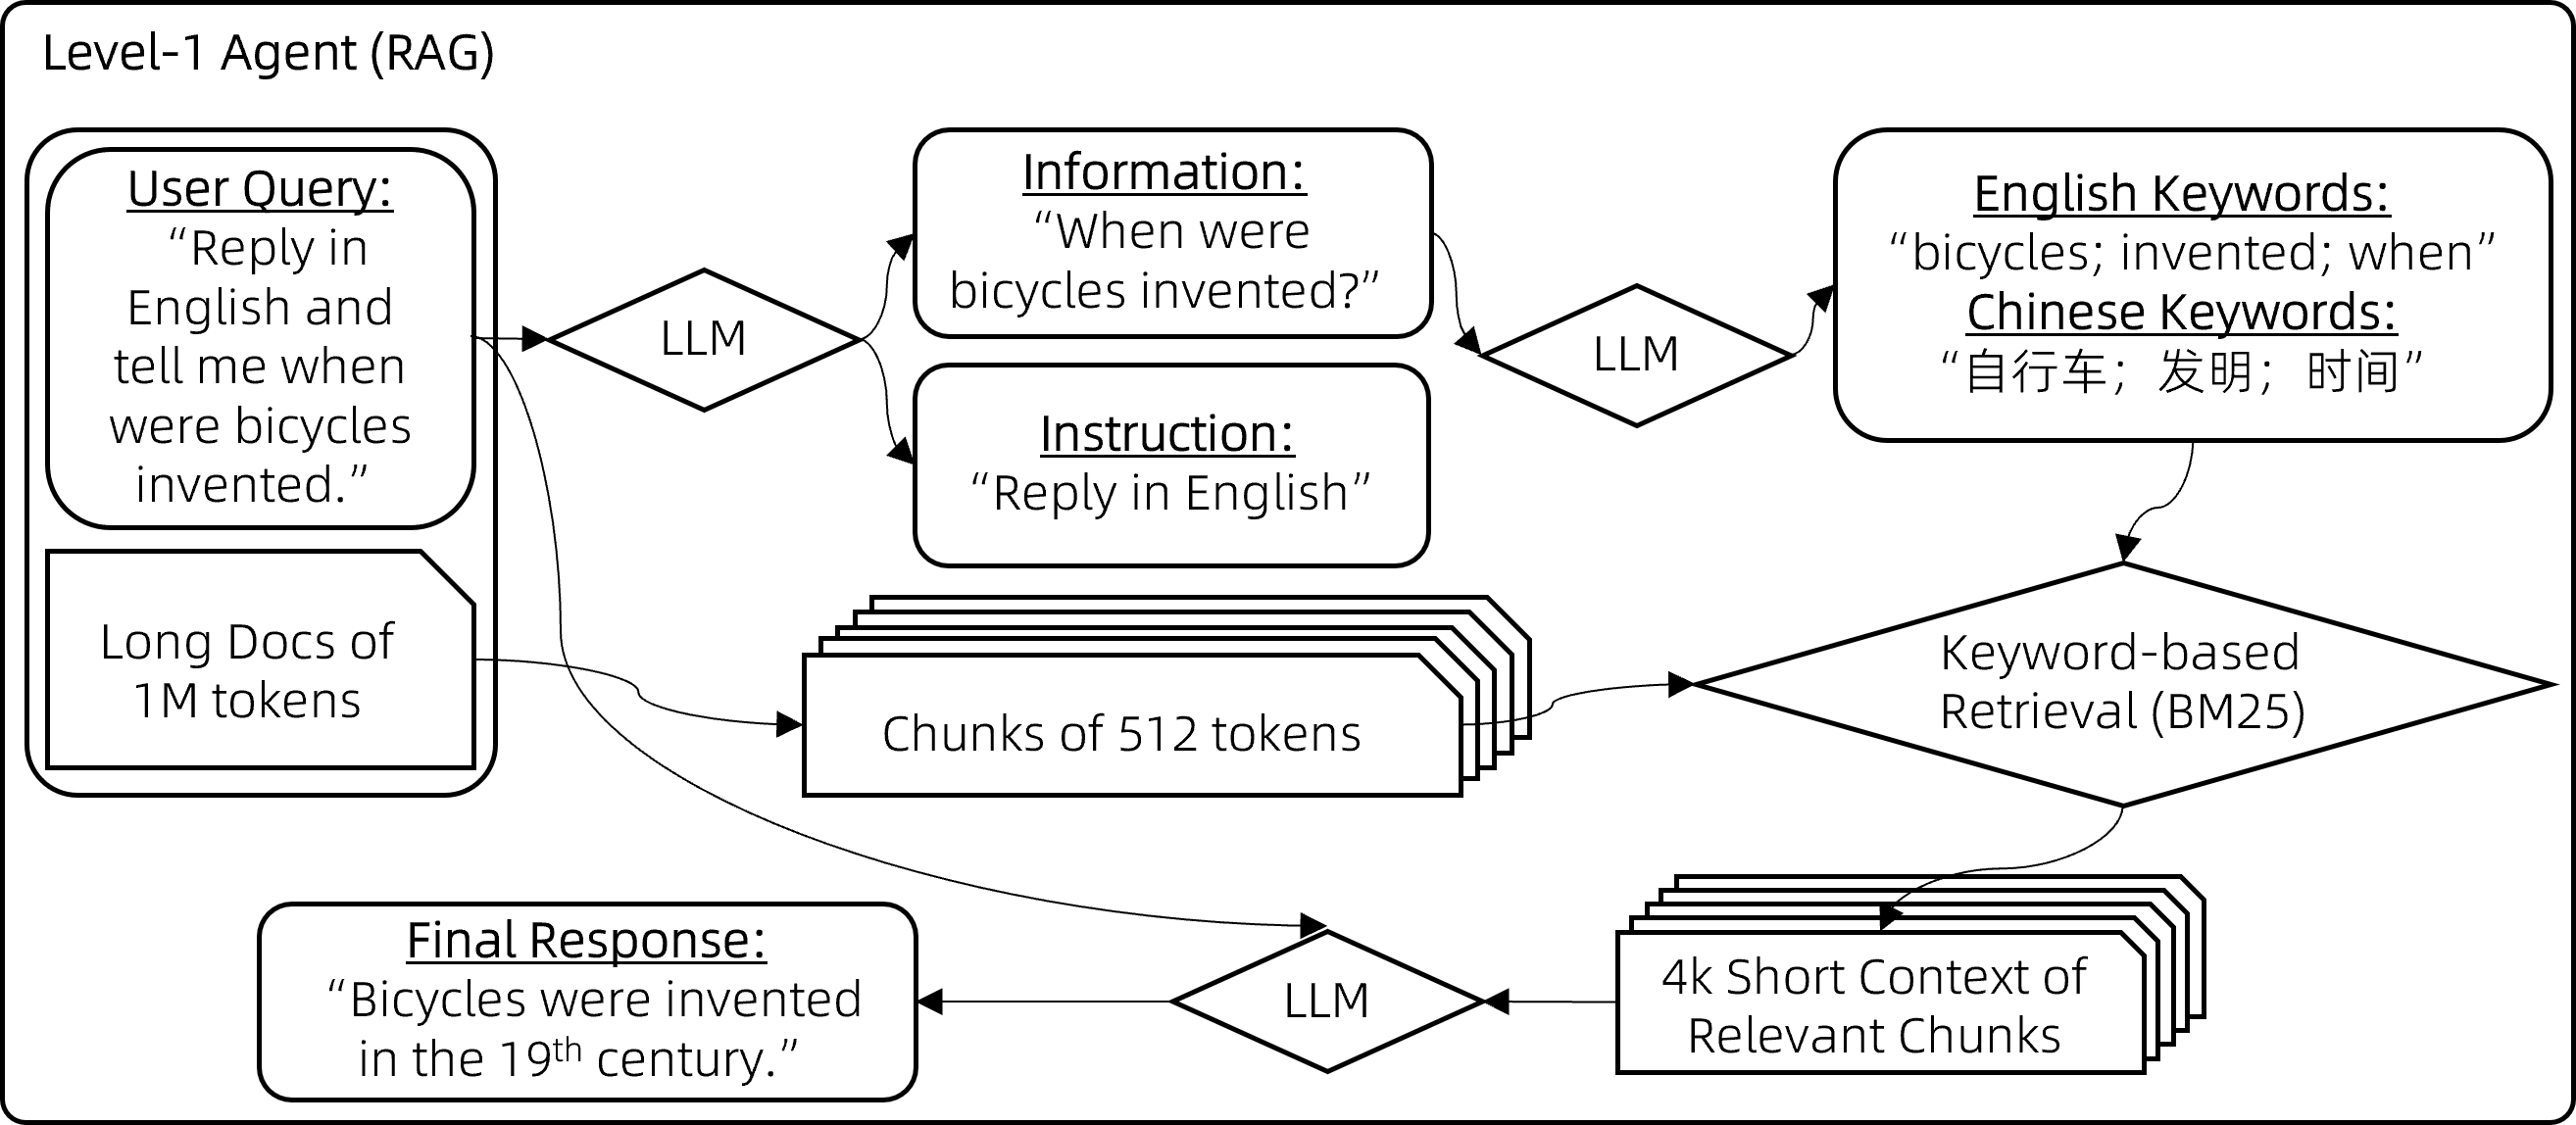 articleGeneralizing an LLM from 8k to 1M Context using Qwen-AgentQwen Team
 articleContext Poisoning as Extreme-Value Attention Interference in Long-Context Language ModelsMeysam Ghaffari, Nina Fatehi, Bhaskar Sen, Nasim Sabetpour, Carlos Morato
Checking sign-in…
Loading comments…