One transformer for text and images, no screen parsing pipeline
- Source
- x.com
- Date

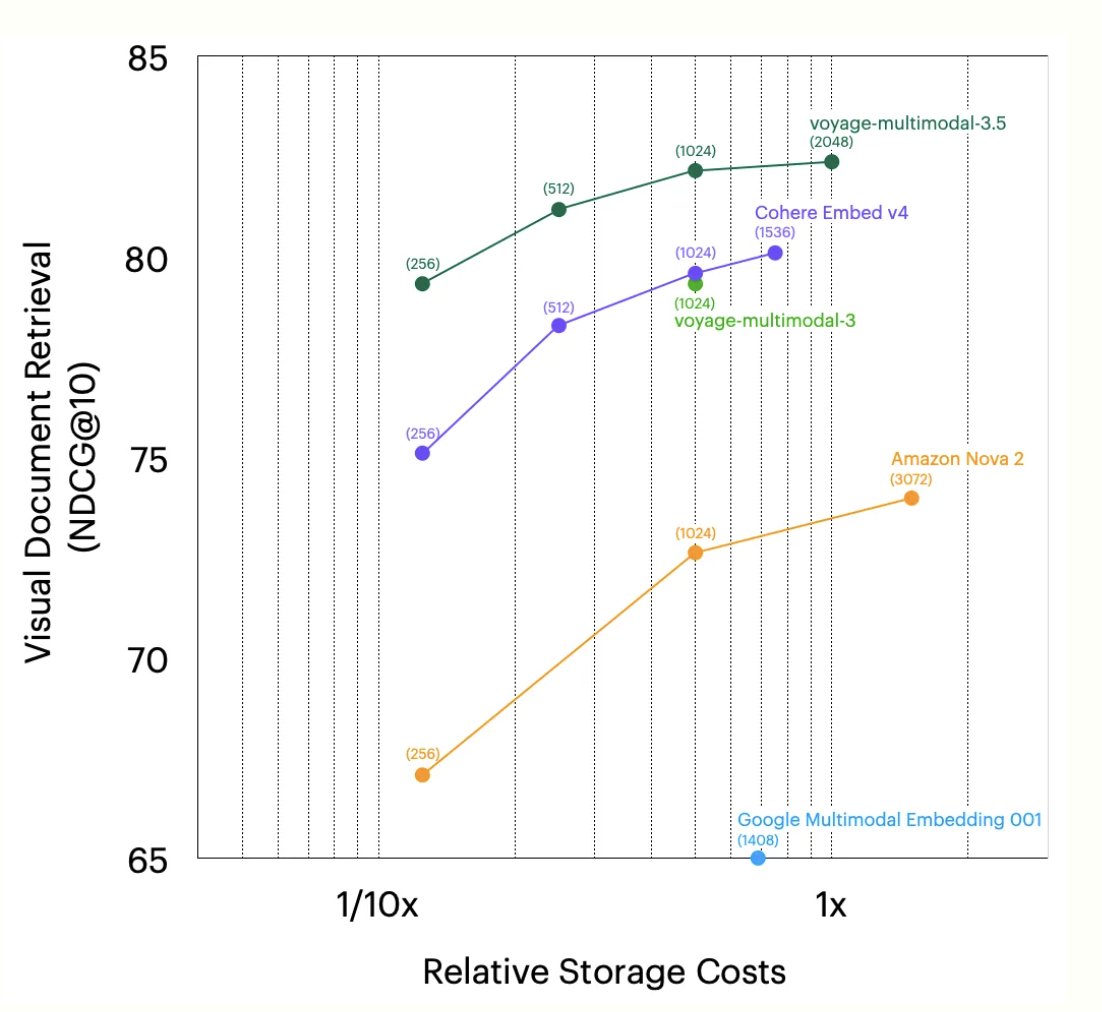
📢 Announcing voyage-multimodal-3, our first multimodal embedding model! It vectorizes interleaved text & images, capturing key visual features from screenshots of PDFs, slides, tables, figures, etc. +19.63% accuracy gain on 3 multimodal retrieval tasks (20 datasets)! 🧵🧵
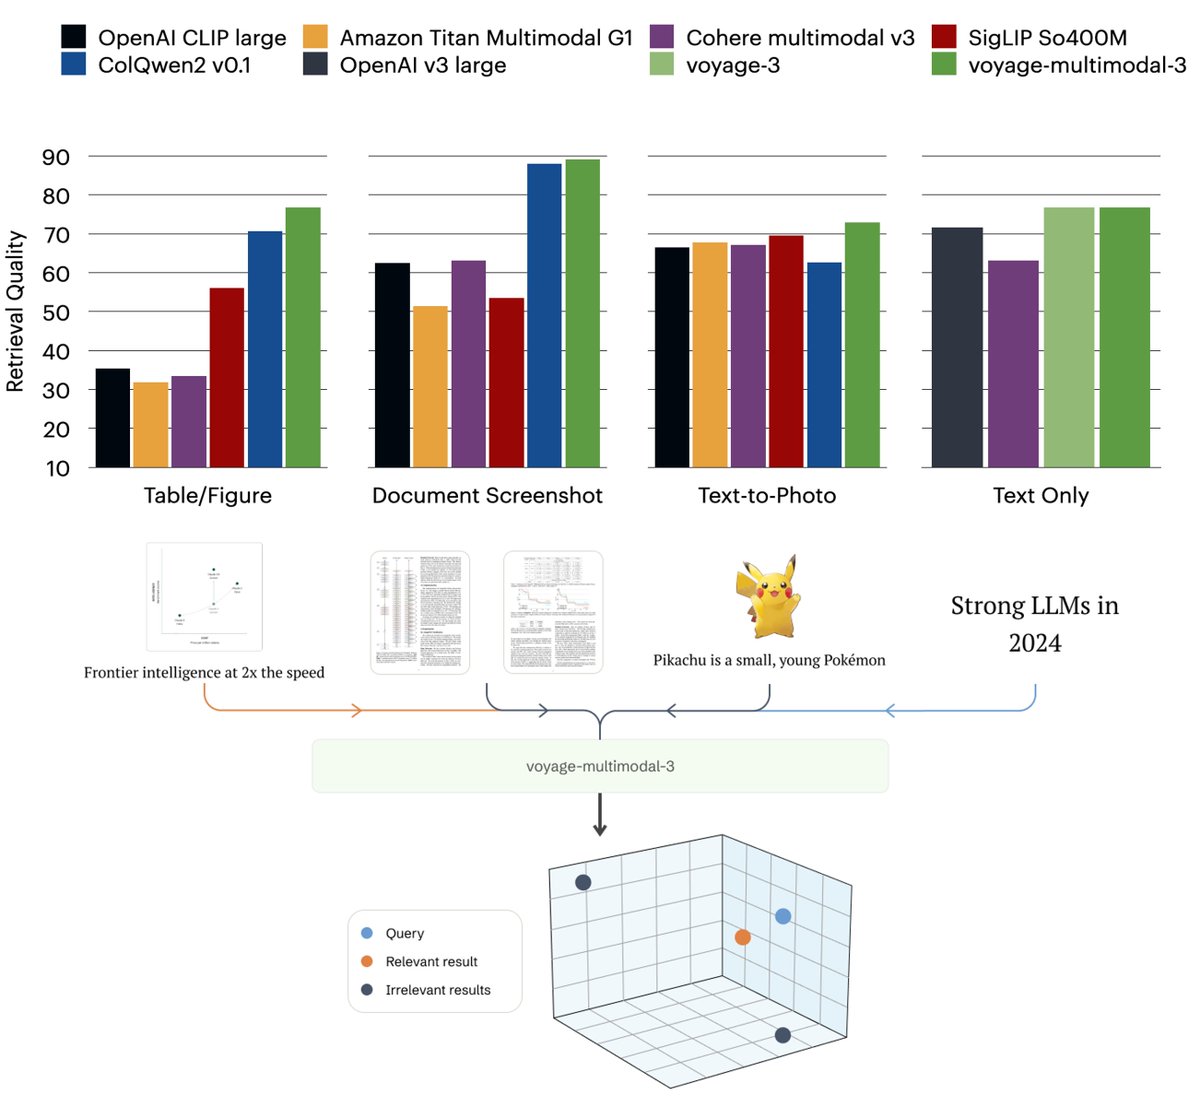
Most multimodal embedding models (e.g. @cohere multimodal v3) mimic @OpenAI CLIP and use separate networks for images & text. In contrast, voyage-multimodal-3, inspired by the modern vision-language model architecture, processes both text and visuals within the same transformer.

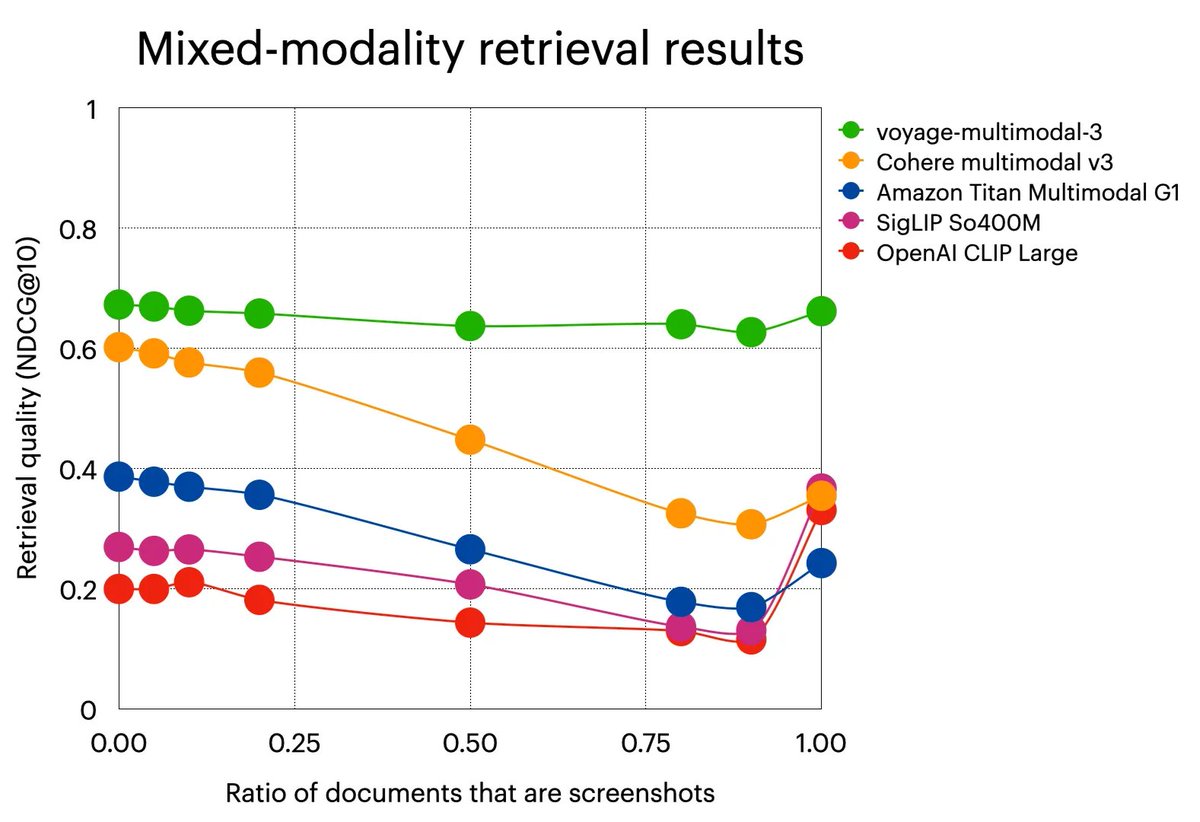
Thanks to the unified architecture, voyage-multimodal-3 excels in mixed-modality retrieval. Testing on varying ratios of text and screenshots with identical content showed that, unlike other models, its performance remains steady as the screenshot ratio increases.
No need anymore for screen parsing models, layout analysis, or other complex text extraction pipelines. Simply take a screenshot of your document and/or prepend extra text (e.g., meta info), and vectorize the interleaved data! Start with our notebook: https://t.co/QIbj9zO3wM
Context
Voyage AI's voyage--3 lets a search system index a document's appearance alongside its words. It processes interleaved text and images through one encoder, producing a numerical representation for retrieval. A screenshot of a slide or report can therefore be indexed directly, retaining visual information such as text placement and layout. The release article describes this as an alternative to extracting and reconstructing document text before it.
That changes the preparation needed for searching visually rich documents. A developer can combine screenshots with accompanying text in the same input, allowing search to use their relationship instead of relying exclusively on extracted words.
- multimodal — A model that works with more than text — reading images, audio, or video, and sometimes generating them too.
- transformer — The neural network architecture behind modern AI models, built on attention — letting every word directly consider every other word in parallel.
- embedding — A list of numbers representing a piece of text's meaning, so that similar meanings end up numerically close and can be searched.
Checking sign-in…
Loading comments…