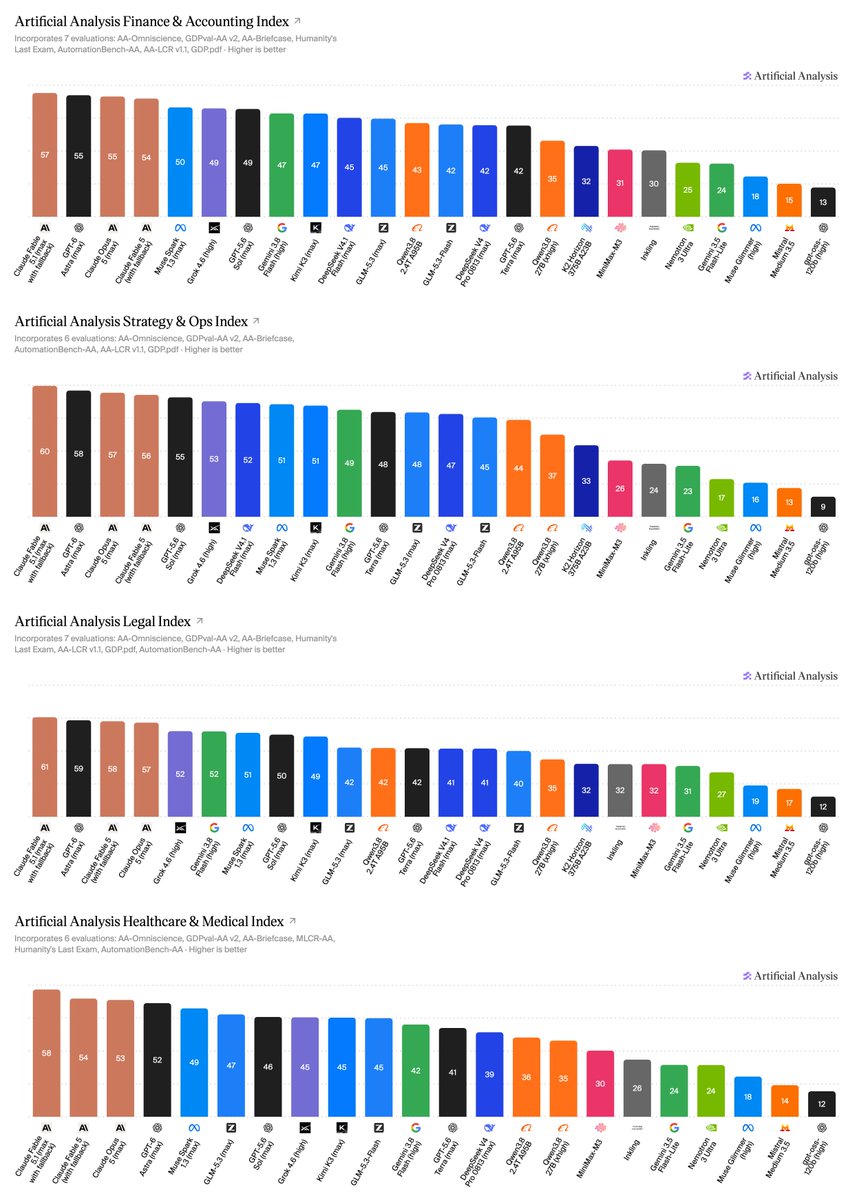
Explains how domain indices map occupation tasks to benchmarks and which evals were added or reweighted. Helps you interpret model rankings for finance, legal, ops and engineering AI agentAn AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.Full definition → work.
Key takeaways · AI-distilled
The Capability Indices map tasks from O*NET occupations to the benchmarks that represent them, weighting each benchmarkA standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.Full definition → by how often its capability appears across those tasks; v1.1 draws on slices of Intelligence Index v4.2 and v4.3 evaluations.
Agentic Customer Interaction (τ³-Banking) is dropped from Finance, Strategy & Ops, Legal and Healthcare, and agentic tool useA model's ability to call external functions — run code, search the web, edit files — instead of only generating text.Full definition → from AutomationBench-AA slices is added, weighted 30% in Strategy & Ops, 10% in Finance and Healthcare, and 5% in Legal.
Engineering swaps Terminal-Bench v2.1 for v4.0 and raises terminal use from 5% to 15%, while removing GPQA Diamond from its reasoning slot; Healthcare adds MLCR-AA long-context windowThe maximum amount of text a model can consider at once — its working memory for the current conversation or task.Full definition → reasoning over clinical records at 15%.
AA-Briefcase joins GDPval-AA v2 in every index's agentic knowledge work slot, and GDP.pdf joins LCR for long context in Finance, Strategy & Ops and Legal; Economics raises knowledge work from 15% to 25% and cuts long-context reasoning from 15% to 5%.
Terms in this piece · Glossary
tool use — A model's ability to call external functions — run code, search the web, edit files — instead of only generating text.
AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.