PrismML ships Ternary Bonsai 2 small models for on-device agents
Source
prismml.com
Author
PrismML
Date
Why it matters
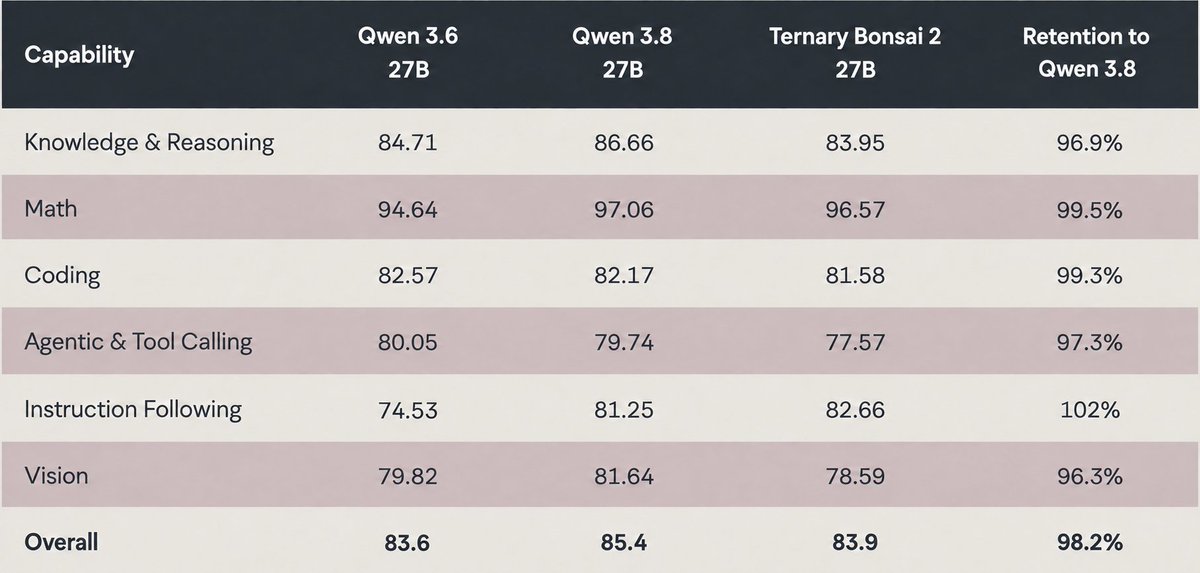
Ternary weights shrink a 9B model to 2GB and keep roughly 92% to 100% of full-precision benchmarkA standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.Full definition → scores, so tool-calling agents can run on phones and laptops. Benchmarks are vendor-reported; the whitepaper was not readable.
Key takeaways · AI-distilled
PrismML's Ternary Bonsai 2 2B, 4B and 9B, built on Qwen3.5, store each weight as -1, 0 or +1, giving footprints of 0.43GB, 0.95GB and 2GB, which PrismML says is over 9x smaller than full precision.
Retention is uneven by agent skillA reusable instruction file that teaches an agent how to do one job well — the procedure, the tools, and what counts as done.Full definition → in PrismML's own tables: the 9B keeps about 100% on instruction following and coding but 84.7% on GPQA Diamond and 85.7% on Tau2Bench, and the 2B keeps only 67.7% on GPQA Diamond.
PrismML reports up to 5x throughput and 3x energy efficiency versus full-precision counterparts on RTX 4090 and M5 Pro, with the 9B reaching up to 34 tokenThe chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.Full definition →/s on an iPhone 18 Pro Max and the 2B up to 120.
PrismML tuned the release against small-model failure modes, repetitive loops, weak instruction following, mobile tool calls and verbosity, and says the 9B uses about 40% fewer tokens on everyday instruction and math tasks.
Terms in this piece · Glossary
tool use — A model's ability to call external functions — run code, search the web, edit files — instead of only generating text.
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
agent skill — A reusable instruction file that teaches an agent how to do one job well — the procedure, the tools, and what counts as done.
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.