Artificial Analysis launches AA-3D, a benchmark for agent-built 3D scenes
- Source
- x.com
- Date

We have measured intelligence. Now it's time to see it. We are launching AA-3D, our new benchmark for how well AI models build interactive 3D scenes. Each model works as an agent in an offline sandbox and turns a written brief into a three.js web page. A human panel of judges compares pairs of scenes built from the same brief without knowing which model made which. AA-3D details: ➤ 55 written briefs across seven domains, including landmarks, machines, living bodies, games, and space. Each brief says what the scene must show and how people should interact with it, and leaves the rest to the model ➤ Each model gets up to three hours and 250 turns. Its sandbox has Blender, Rapier physics, Python, a headless browser to test its own work, and a CC0 library of materials, 3D models, and characters ➤ Panelists spend at least 30 seconds with each scene before they vote. One comparison in every four is a validation check ➤ Over 10,000 counted votes from over 1,000 panelists rank 21 models by Elo, with 95% confidence intervals Key findings: ➤ Four models are statistically tied at the top: Claude Sonnet 5.5 (1194), Claude Opus 5.5 (1190), GPT-6 Astra (1165), and Claude Fable 5.1…

AA-3D ranks 21 models on agentic three.js scene building using human pairwise votes. It shows the top four are statistically tied and Elo tracks the Intelligence Index, helping you pick models for 3D and creative coding work.
- Setup: 55 written briefs across seven domains, including landmarks, machines, living bodies, games and space. Each brief fixes what the scene must show and how people interact with it, and leaves the rest to the model.
- Each model runs as an in an offline for up to three hours and 250 turns, with Blender, Rapier physics, Python, a headless browser to test its own work, and a CC0 library of materials, models and characters.
- Judging is blind pairwise: panelists spend at least 30 seconds with each scene before voting, and one comparison in four is a validation check. Over 10,000 counted votes from 1,000+ panelists produce Elo ratings with 95% confidence intervals.
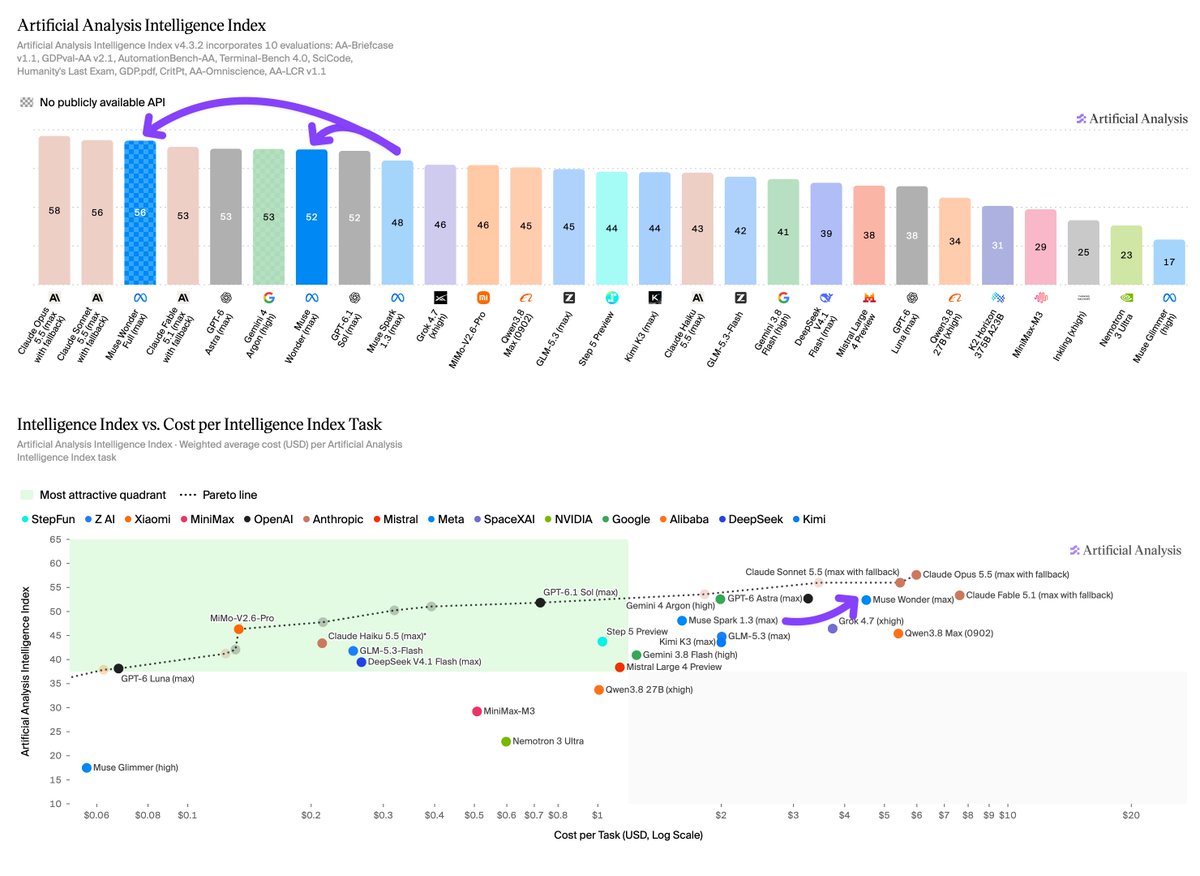
- Artificial Analysis reports about 18 Elo per point on its Intelligence Index (Pearson 0.92). The top four, statistically tied: Claude Sonnet 5.5 (1194), Claude Opus 5.5 (1190), GPT-6 Astra (1165), Claude Fable 5.1 (1131).
- The best open-weights entries, Kimi K3 (982) and MiMo-V2.6-Pro (977), place 11th and 12th, over 200 points behind first. Cost per scene ranges from $0.20 to $32.08; the cheapest model, GPT-6 Luna, ranks eighth.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- open weights — A model whose trained parameters are published for anyone to download and run — unlike API-only models you can access but never possess.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- sandbox — An isolated environment where AI-generated code or agent actions run without being able to touch anything real.
Checking sign-in…
Loading comments…