Speech Agent Arena scores voice agents on tool-call success
- Source
- x.com
- Date

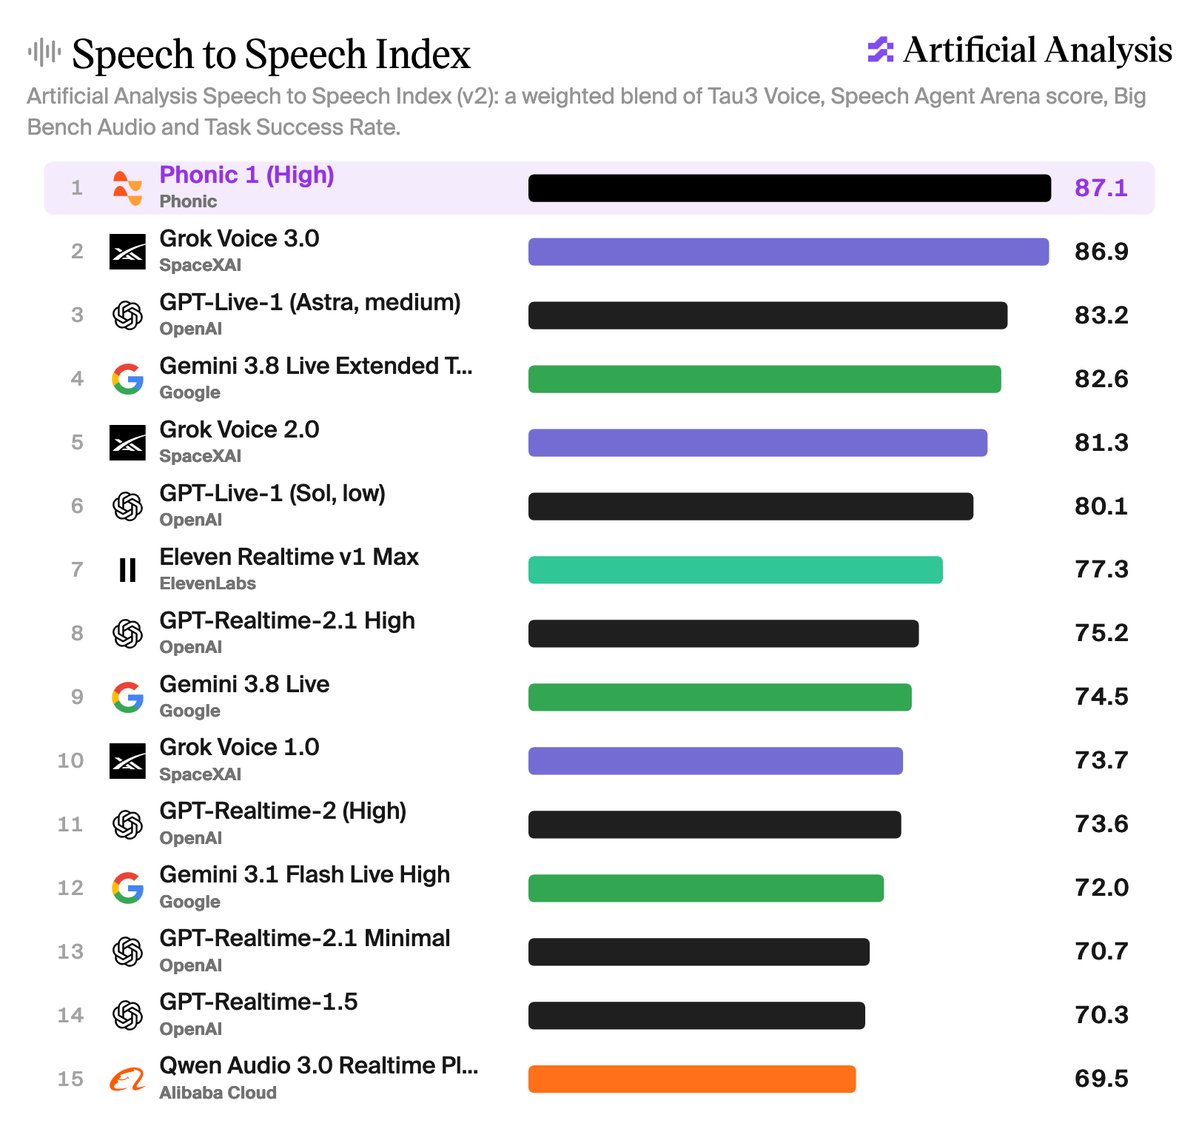
Announcing our new Speech Agent Arena, evaluating Speech to Speech models on real-world scenarios to analyze conversational preference and task success rate Existing Speech to Speech benchmarks cover reasoning, simulated agentic tasks, and conversational dynamics such as turn-taking and interruption handling. The Speech Agent Arena compares models and cascaded systems as humans complete real-world tasks, measuring conversational preference and successful tool use. This allows us to provide an evaluation which closer reflects real-world use, offering insight into which models users most prefer speaking with and how effectively those models support their requests. Overview of the Speech Agent Arena and Task Success Rate Human participants compare two hidden Speech to Speech models on the same assigned scenario, one of 15 agentic scenarios (tasks requiring tool calling, such as ordering takeout) or 20 non-agentic scenarios (tasks without tool calling, such as asking about opening hours). After separate live conversations with each model, participants select which they preferred, with these pairwise votes used to fit a Preference Elo score. For agentic scenarios, Task Success Rate…

Context
Artificial Analysis's new Speech Agent Arena scores voice AI systems on two things separately: whether people prefer talking to them, and whether they actually complete the requested task. The first results show the two can diverge sharply. Google's Gemini 3.1 Flash Live Preview, in its Minimal setting, led the preference ranking at 1,046 Elo but succeeded in only 74.6% of eligible -based conversations, while xAI's Grok Voice Think Fast 2.0 High led task success at 94.7%.
Paid, screened participants receive a scenario, such as ordering takeout, hold a live spoken conversation with each of two unidentified systems, and pick the one they preferred; those pairwise votes are fit into Elo scores. In the 15 agentic scenarios, the system must carry out the request by calling a software tool. Task Success Rate counts a conversation as a success only when the correct final happened, and it leaves out conversations where the participant deviated or the outcome could not be verified. The arena includes both native speech-to-speech models and cascaded systems that chain speech recognition, a text and speech synthesis, such as ElevenLabs Agents.
Artificial Analysis gives one reason the scores split: some conversations sounded as though the action had been done even when the required final tool call failed. It also says the most preferred models tended to respond quickly and sound natural. For a that is supposed to take actions, the success rate is the number that tracks the job, and a strong preference score is not evidence that tasks finish. Most scenario prompts and tool schemas are private to limit overfitting, and the announcement does not give vote counts or confidence intervals, so outsiders cannot tell whether close results, such as 91.5% against 90.5%, differ by more than chance.
- Tool — An operation that the software around a model makes available for the model to request, with a name, expected inputs and a kind of result.
- Tool call — Text the model generates in an agreed format that names a tool and gives its inputs.
- Model — A computational system that uses learned patterns to produce an output from information supplied to it.
- Realtime conversational agent — An agent that processes streaming audio or visual input while a session is live.
Checking sign-in…
Loading comments…