Endpoint Accuracy Index scores providers from 73% to 100%
- Source
- x.com
- Date

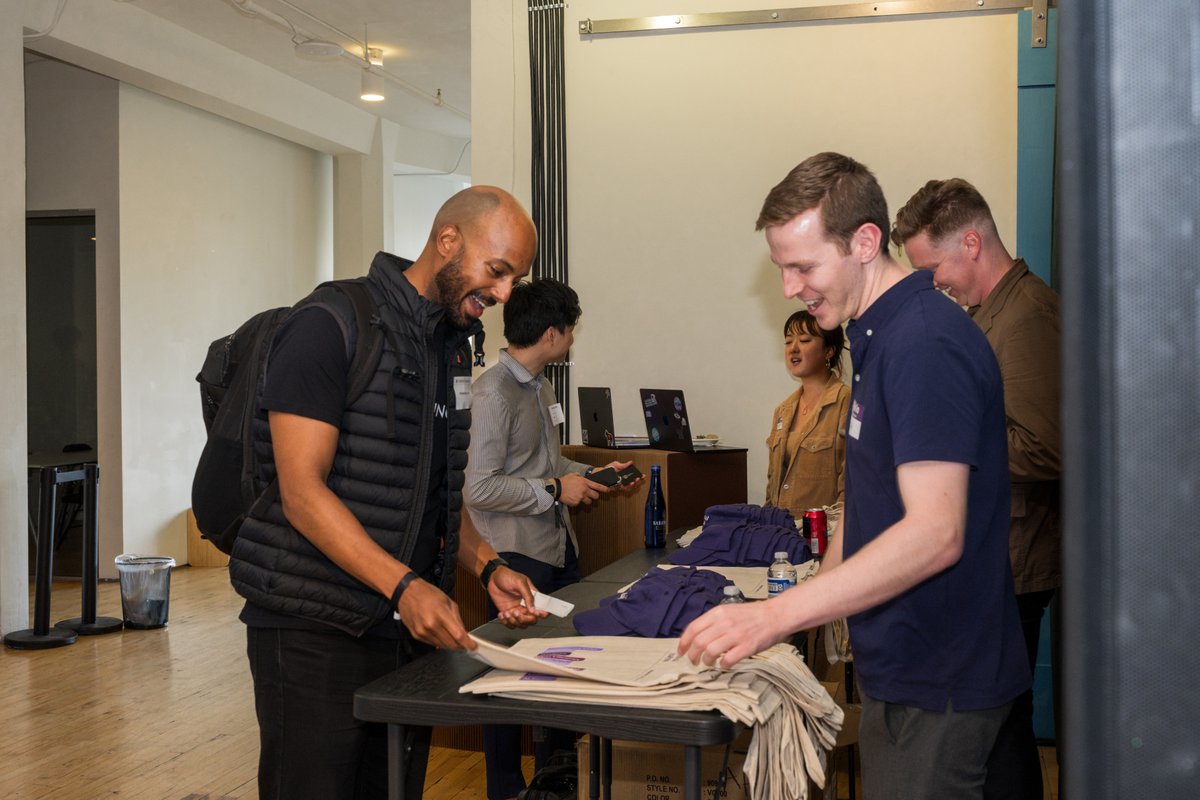
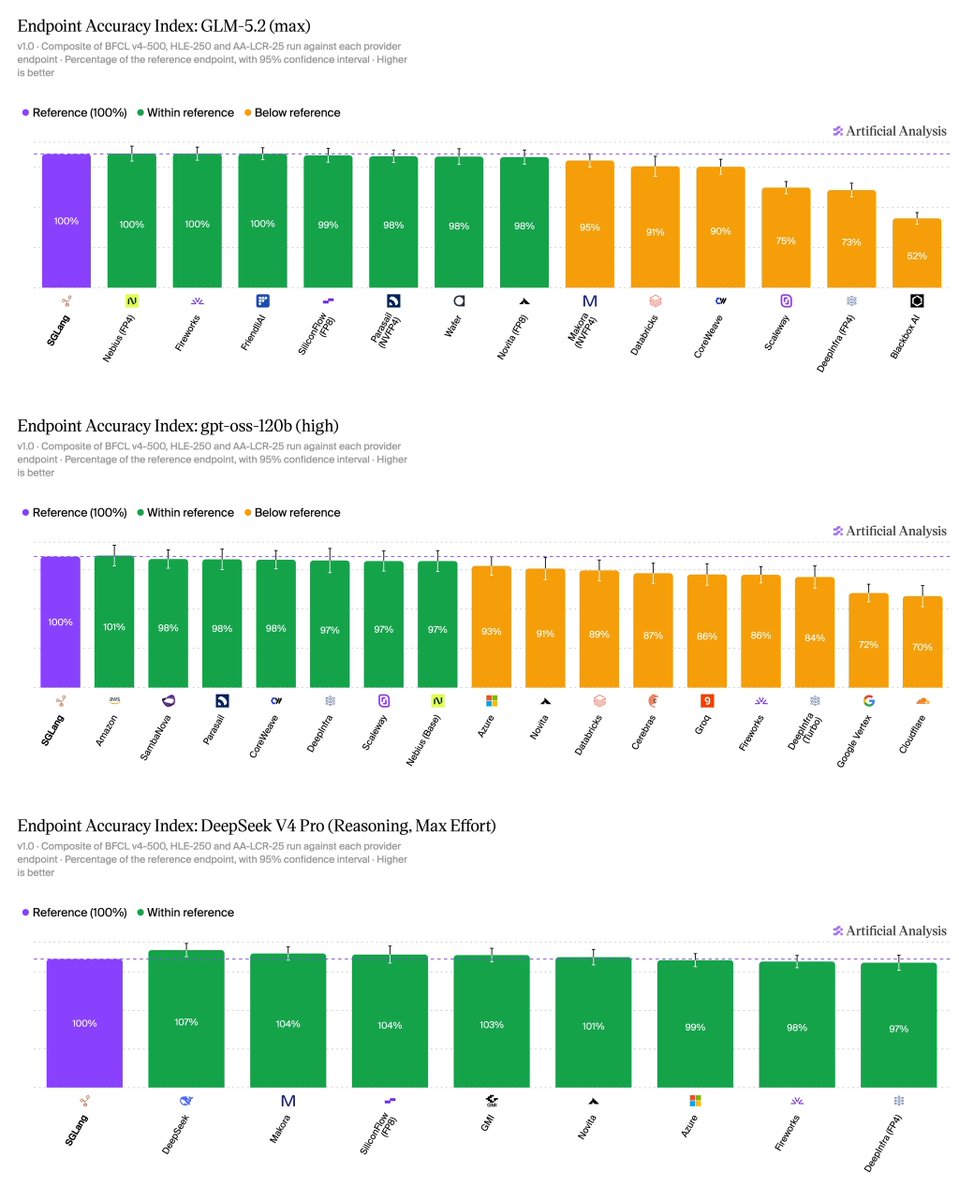
Another fantastic evening at our latest Inference, Measured event in San Francisco. We explored how the same model is not always the same product through conversations on serverless inference, Endpoint Accuracy Index, and AA-AgentPerf Our new Endpoint Accuracy Index reveals another layer. We self-host the released weights as a 100% reference, measure each provider endpoint using the same three evaluations, and score the results relative to that reference. The results range from 73% to 100%. Quantization, KV-cache compression, and context limits can all affect the quality, even when they don't appear on the pricing page. Visit our website to explore the evaluations and full results. Thank you to everyone who joined us and contributed to the conversation about measuring the tradeoffs between performance, speed, and cost.


Context
Artificial Analysis's Endpoint Accuracy Index asks whether a model served by a given provider performs like the model as released. In a recap of its Inference, Measured event, the company says it self-hosts the released weights as a 100% reference, runs each provider's endpoint through the same three evaluations, and scores the results relative to that reference. Scores ranged from 73% to 100%, so the same model name can deliver noticeably different results depending on who serves it.
The post names , KV-cache compression and limits as things that can affect quality without showing up on a pricing page. It does not say which providers, models or evaluations produced the range; the full results on the Artificial Analysis website were not collected here. The index's launch announcement is covered separately.
- inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
- quantization — Shrinking a model by storing its numbers less precisely — like rounding — so it runs faster and fits on smaller hardware, at a small quality cost.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
- open weights — A model whose trained parameters are published for anyone to download and run — unlike API-only models you can access but never possess.
Checking sign-in…
Loading comments…