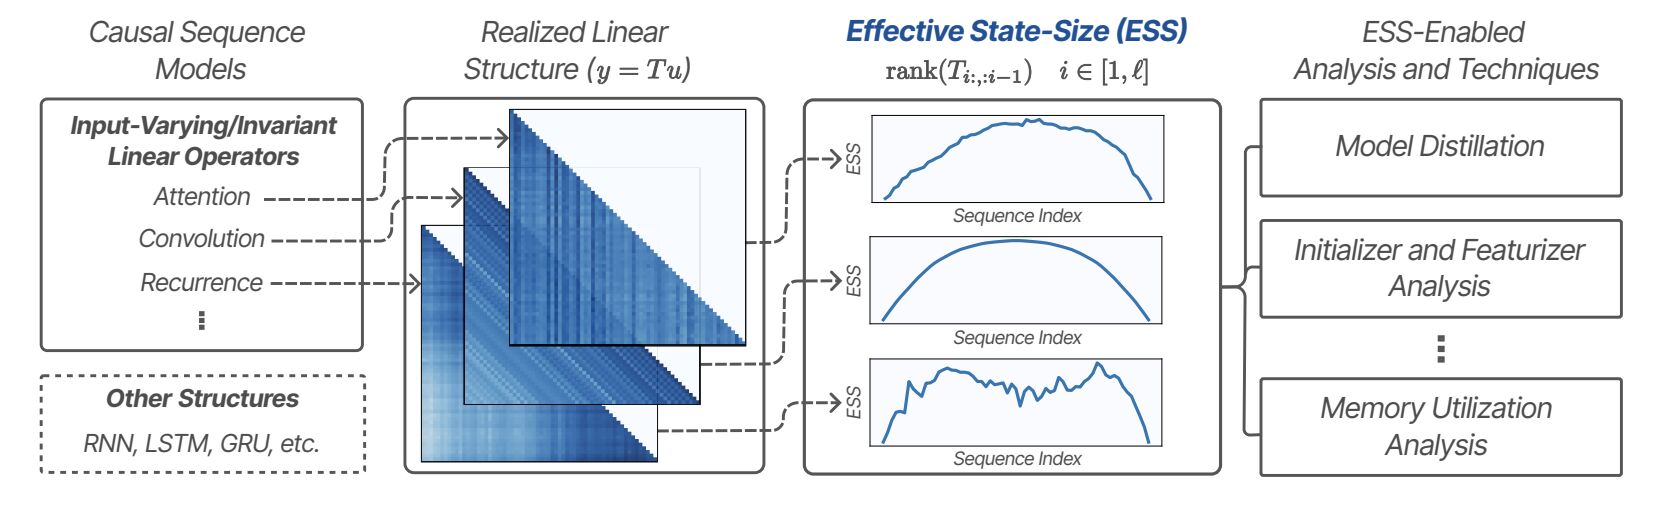
Two sequence models can reserve the same amount of memory yet use it differently. Liquid AI's Effective State-Size is a mathematical proxy for memory utilization. It is based on a lower bound on the internal state, the information a model carries forward as it reads a sequence, needed to reproduce the model's behavior. Its research summary reports that models with higher values are harder to distill into smaller-state models, and that language models that adjust the metric more effectively as context windowThe maximum amount of text a model can consider at once — its working memory for the current conversation or task.Full definition → changes tend to do better on recall-intensive tasks. That is a correlation, not proof of cause. It gives model designers another way to study memory beyond its allocated size.
Terms in this piece · Glossary
context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
KV cache — The memory a model keeps about text it has already read, so generating each new token doesn't require reprocessing the whole conversation.
distillation — Training a small, cheap model to imitate a big one's outputs, keeping much of the capability at a fraction of the cost.
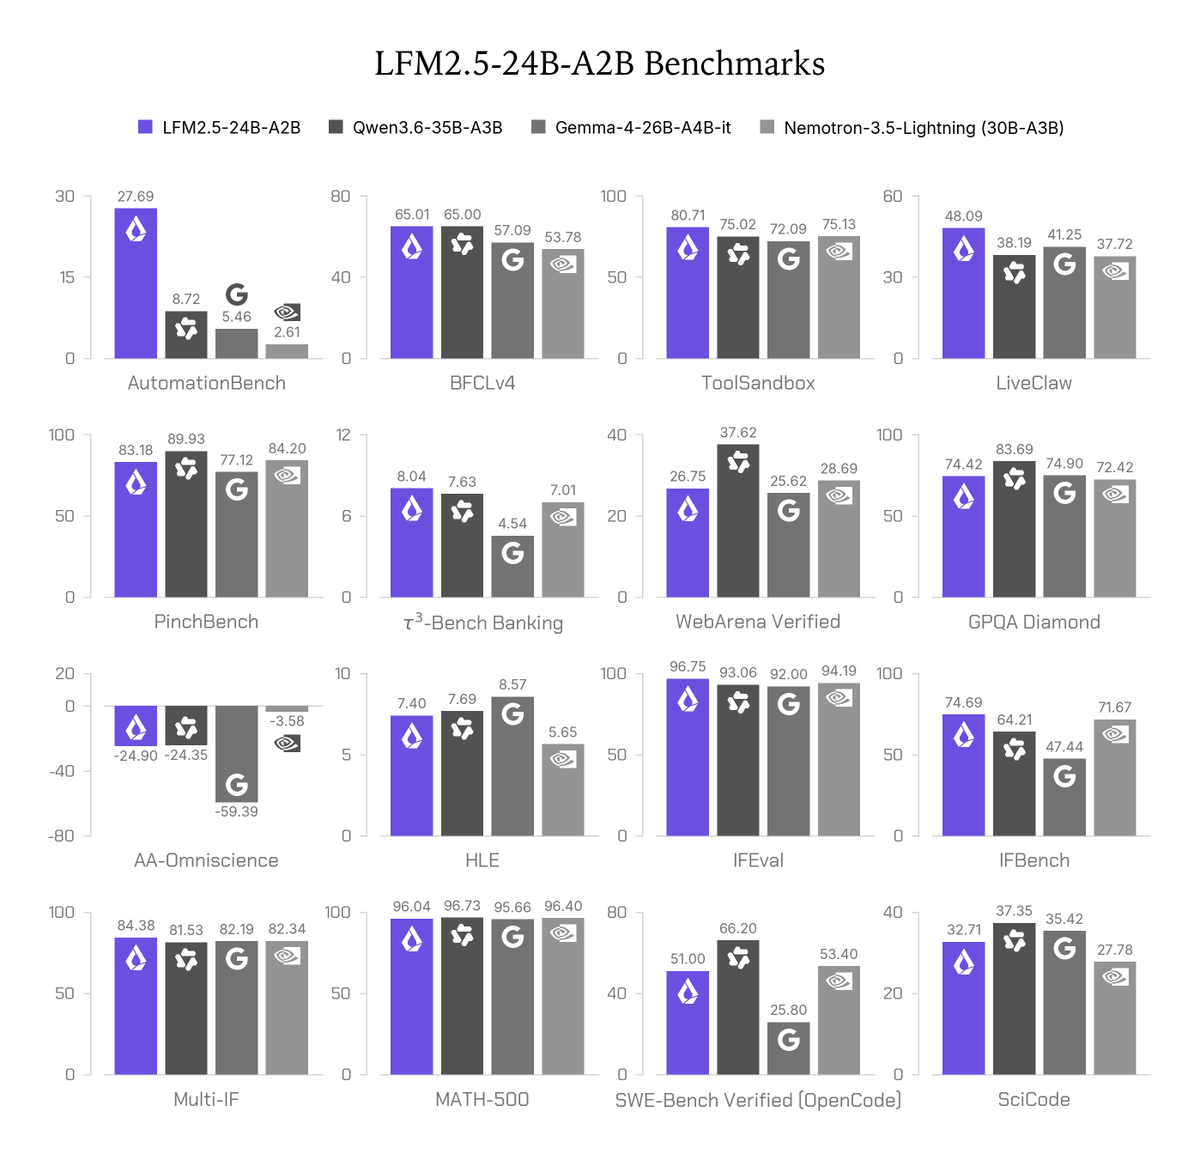 postLiquid AI ships LFM2.5-24B-A2B open weights for local agents
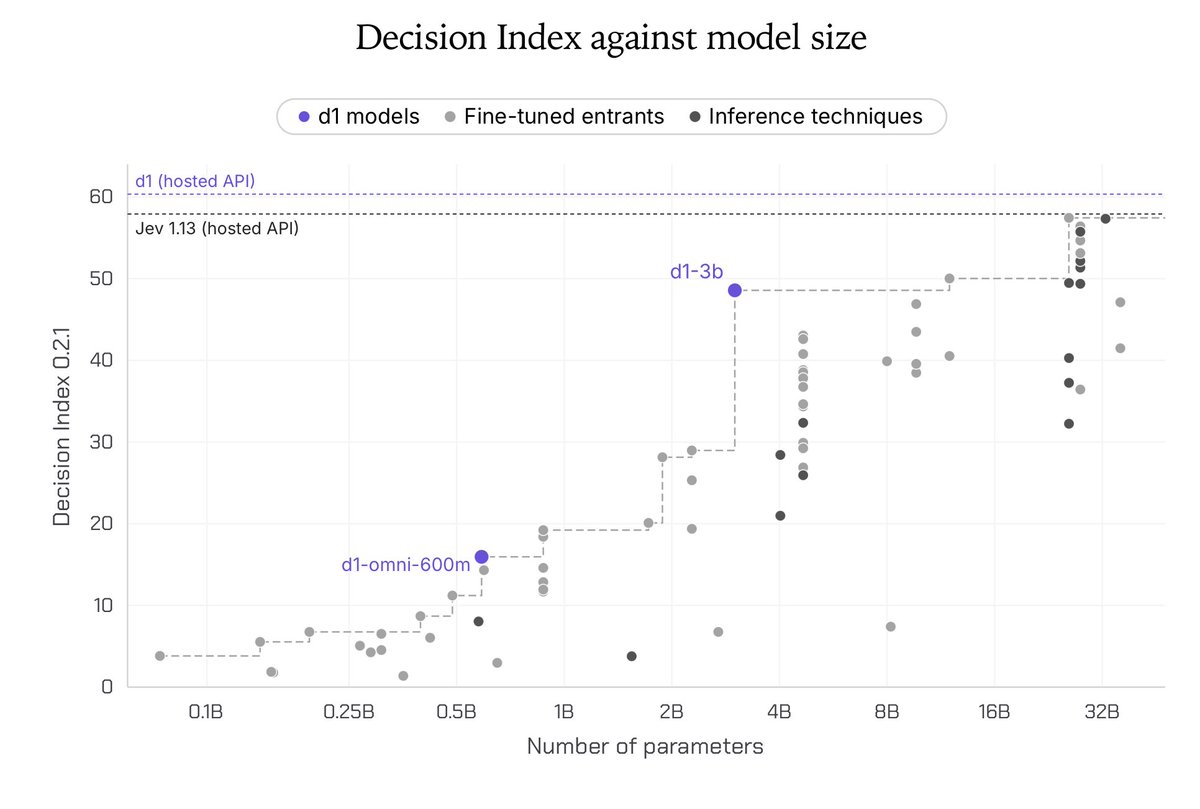 postToday we release Open d1: two open-weight multimodal models in our d1 decision…
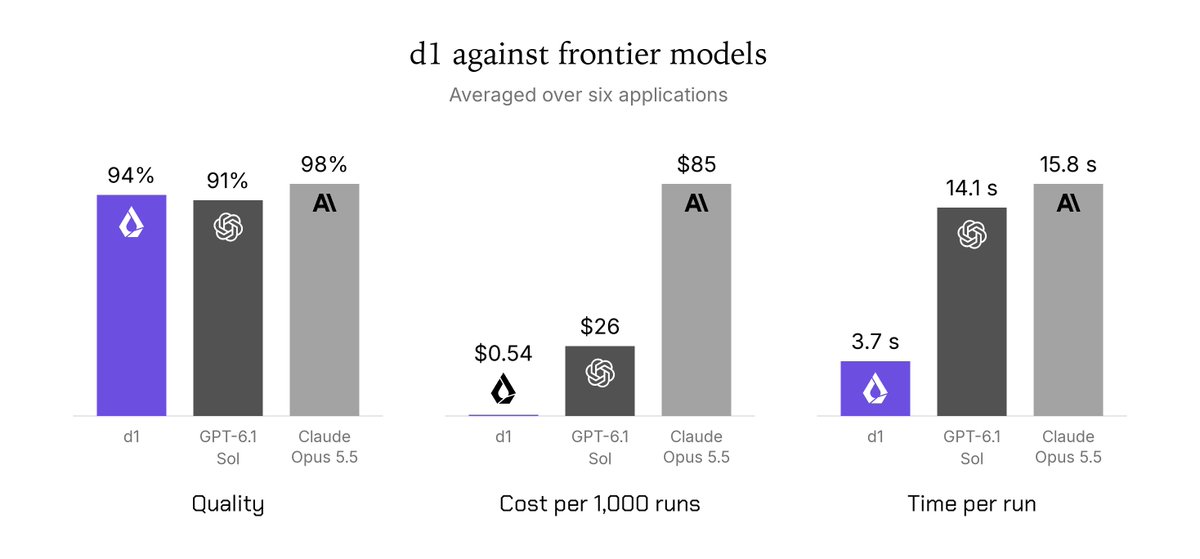 postLiquid AI's d1 decision model adds vision at a fraction of frontier cost
 articled1 is now available on @vercel AI gateway!We worked with the amazing vercel…