BREAKING NEWS🚨: Google has submitted its FIRST TPUv7 FP8 vLLM results to our…
- Source
- x.com
- Date
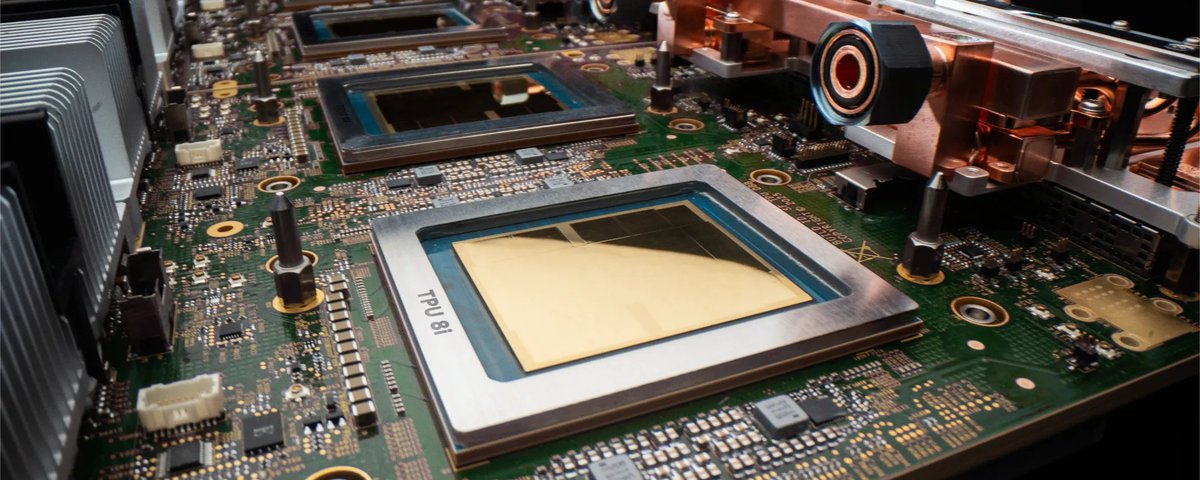
Google has submitted its first TPUv7 results to SemiAnalysis's Agentic Inference Benchmark, running vLLM at FP8. SemiAnalysis reports 1.67x better performance per dollar than NVIDIA's GB300 NVL72 running FP4, and reads the submission as a sign that TPUs are moving beyond Google's internal workloads. The figure is vendor-submitted and has not been independently reproduced, so it is a claim to check rather than a settled ranking. The same day, Artificial Analysis added AMD's MI355X to AA-AgentPerf, which replays real coding-agent sessions with caching and tool delays, and reported up to 40% more throughput per megawatt than NVIDIA Blackwell on DeepSeek V4 Pro. Two non-NVIDIA accelerators now have published numbers on agent-shaped inference traffic rather than synthetic token throughput. For teams pricing large agent workloads, these benchmarks are worth tracking as they mature, because hardware competition is what eventually moves per-token prices.

BREAKING NEWS🚨: Google has submitted its FIRST TPUv7 FP8 vLLM results to our Agentic Inference Benchmark and has demonstrated 1.67x better perf per dollar than even GB300 NVL72 FP4. 🚀 It is amazing to see Google go full steam ahead with externalizing the power of TPUs outside of Google.👇️ (1/4)🧵

Checking sign-in…
Loading comments…