Hy ASR 3.0 preview claims ~3% multilingual word error rate
- Source
- x.com
- Date

AI that finally hears you. 👂 Hy ASR 3.0 preview drops today. Powered by Hy3’s language brain → precision ASR + deep semantic understanding Wins on: • general recognition • context awareness • multi-scenario robustness • dialect coverage Messy real-world audio? Clean, coherent transcripts that nail your intent. Open + internal benches: leading. Multilingual WER ≈ 3%. Voice just got an upgrade. 🔥 #HyASR #TencentAI #Hy3
Context
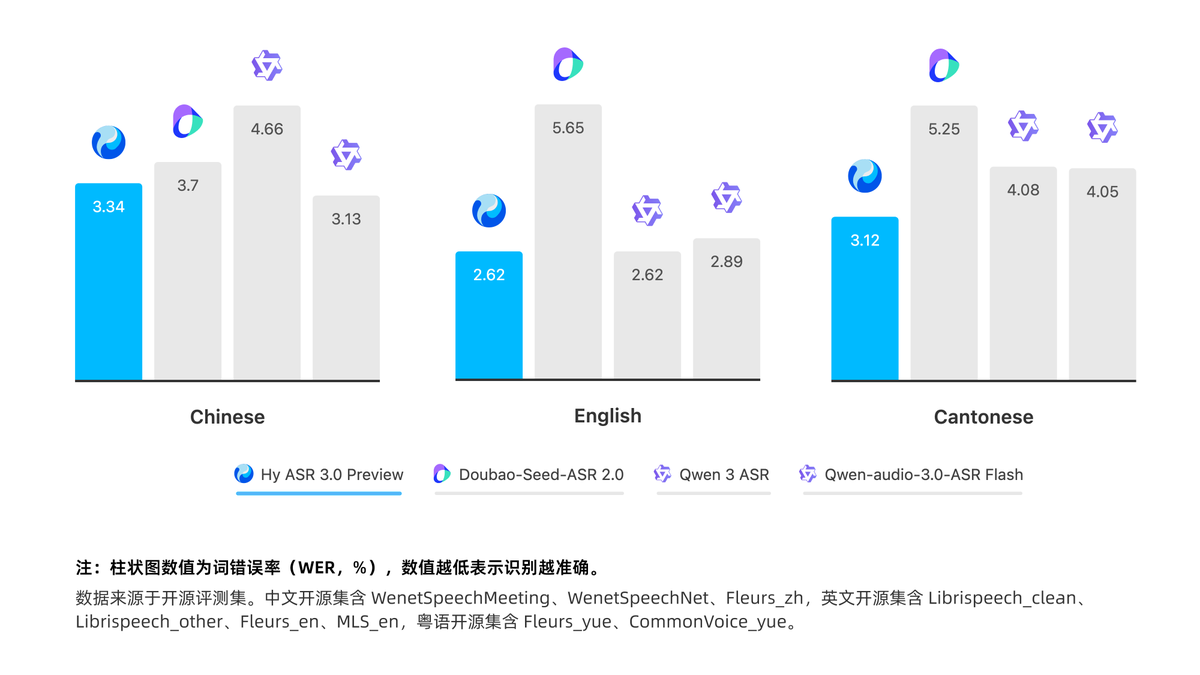
Tencent's Hy ASR 3.0 preview converts speech into text. Its announcement claims a multilingual word error rate of roughly 3%, and a company-published chart gives 3.34% for Chinese, 2.62% for English and 3.12% for Cantonese. Lower values mean fewer transcription errors.
The chart identifies public speech datasets used for each language, but does not explain how their results were combined. These are reported results for those evaluations; they do not establish a single error rate for every language, speaker or recording environment.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
 postExplorationBench tests how models explore, with exactly verifiable grading
 postHy Image3.5 preview is live. 🚀 Professional-grade image generation, +30% win…
 postTencent Hunyuan's EvolveScaler trips up frontier models on evolving facts
 postTencent Hunyuan open-sources AuK, a unified speech generation and editing model
Checking sign-in…
Loading comments…