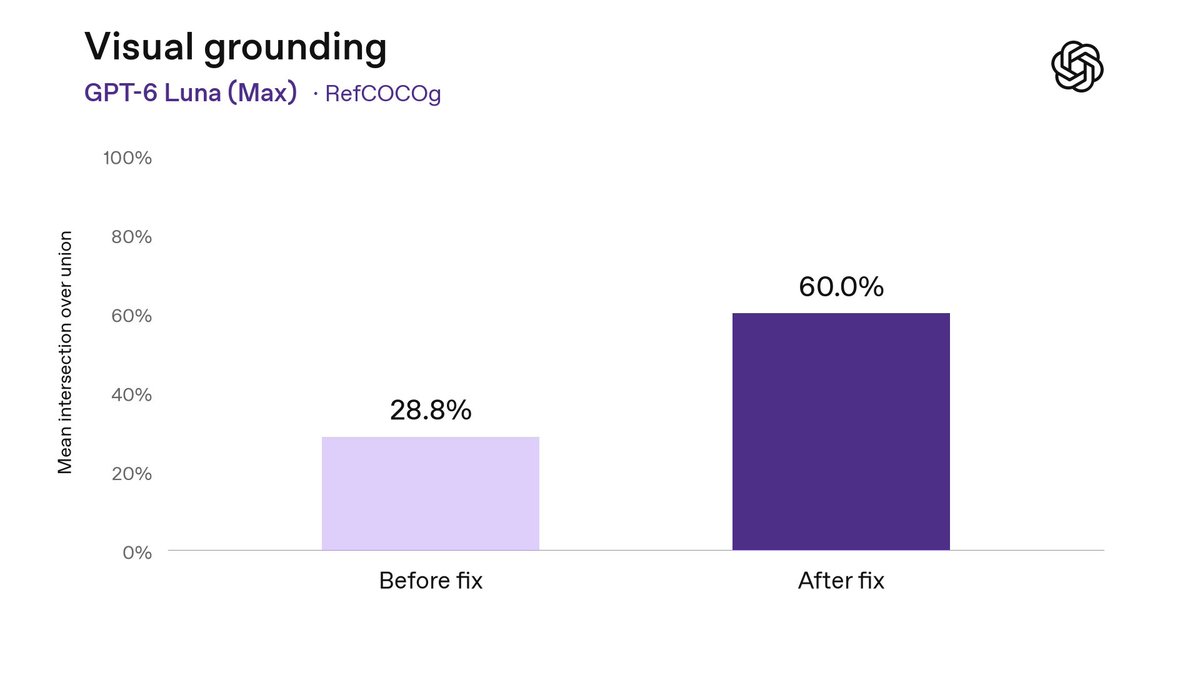
We’ve fixed a bug that was degrading image understanding in GPT-6 Sol and GPT-6 Luna. You should now see better results on visual tasks in the API and Codex, including computer use.
If your workflows use image inputs, we recommend rerunning your evals and giving those workflows another try.
More details in the changelog:
https://t.co/uICFBf1ZNg
eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
Why it matters
Anyone running vision or computer-use workloads on GPT-6 Sol or Luna should rerun their evalA repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.Full definition → now, since prior results may have understated the models' true visual accuracy.