GPT-6.1 Sol pushes the cost-efficiency frontier, per Artificial Analysis
- Source
- x.com
- Date

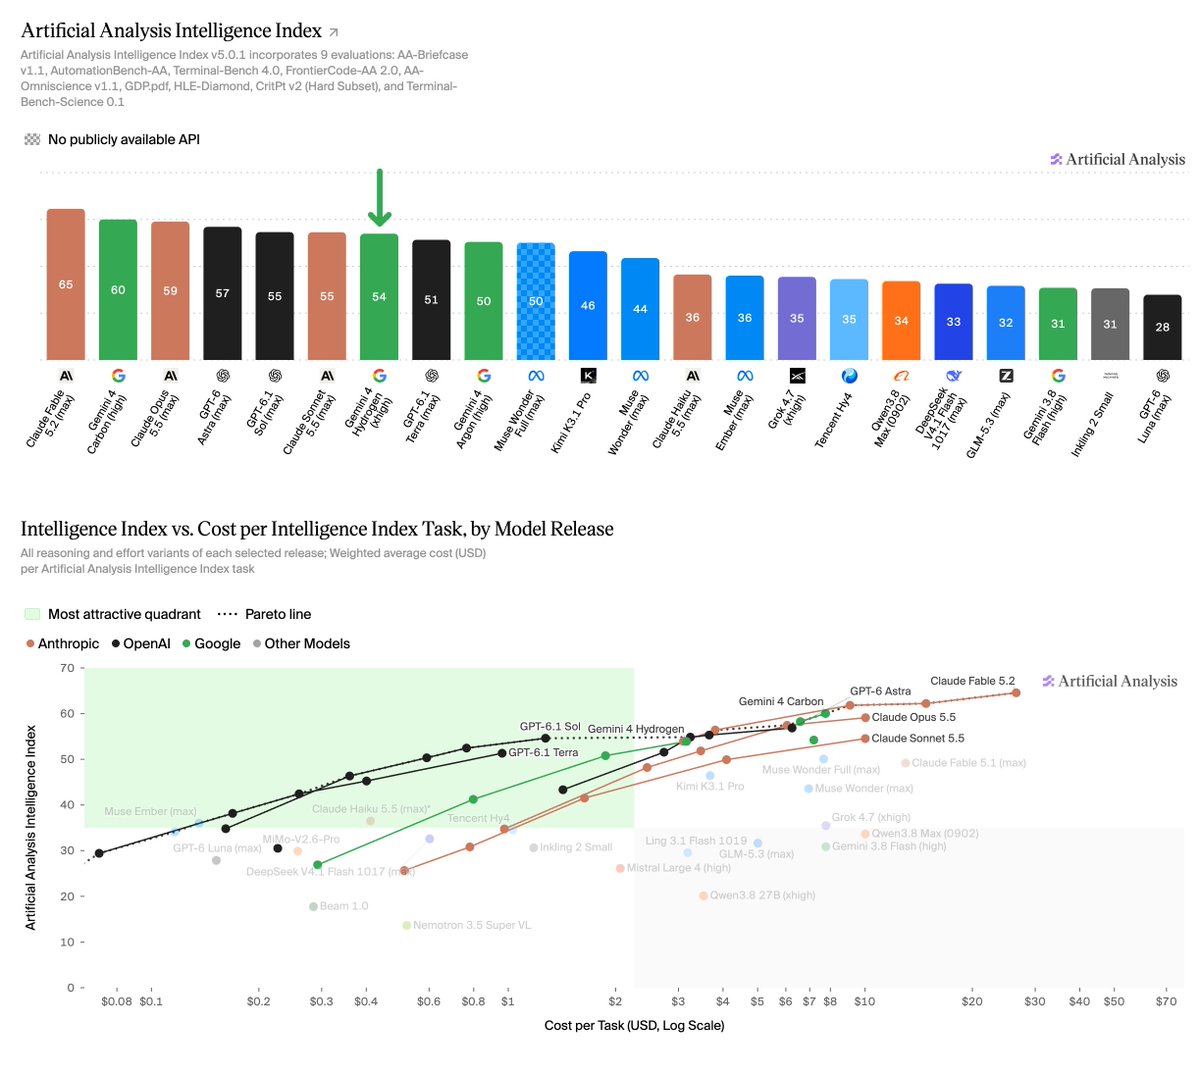
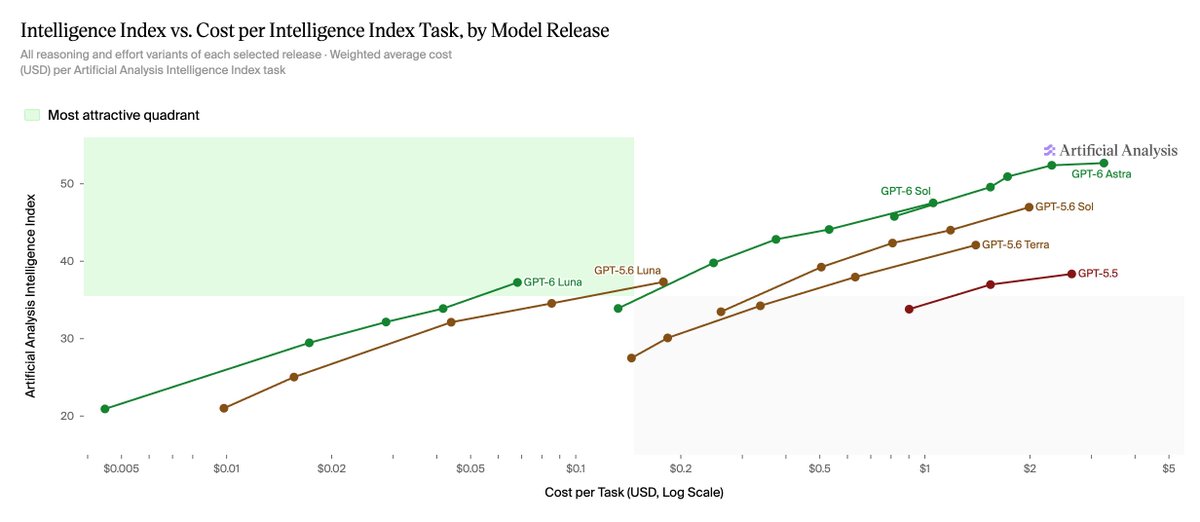
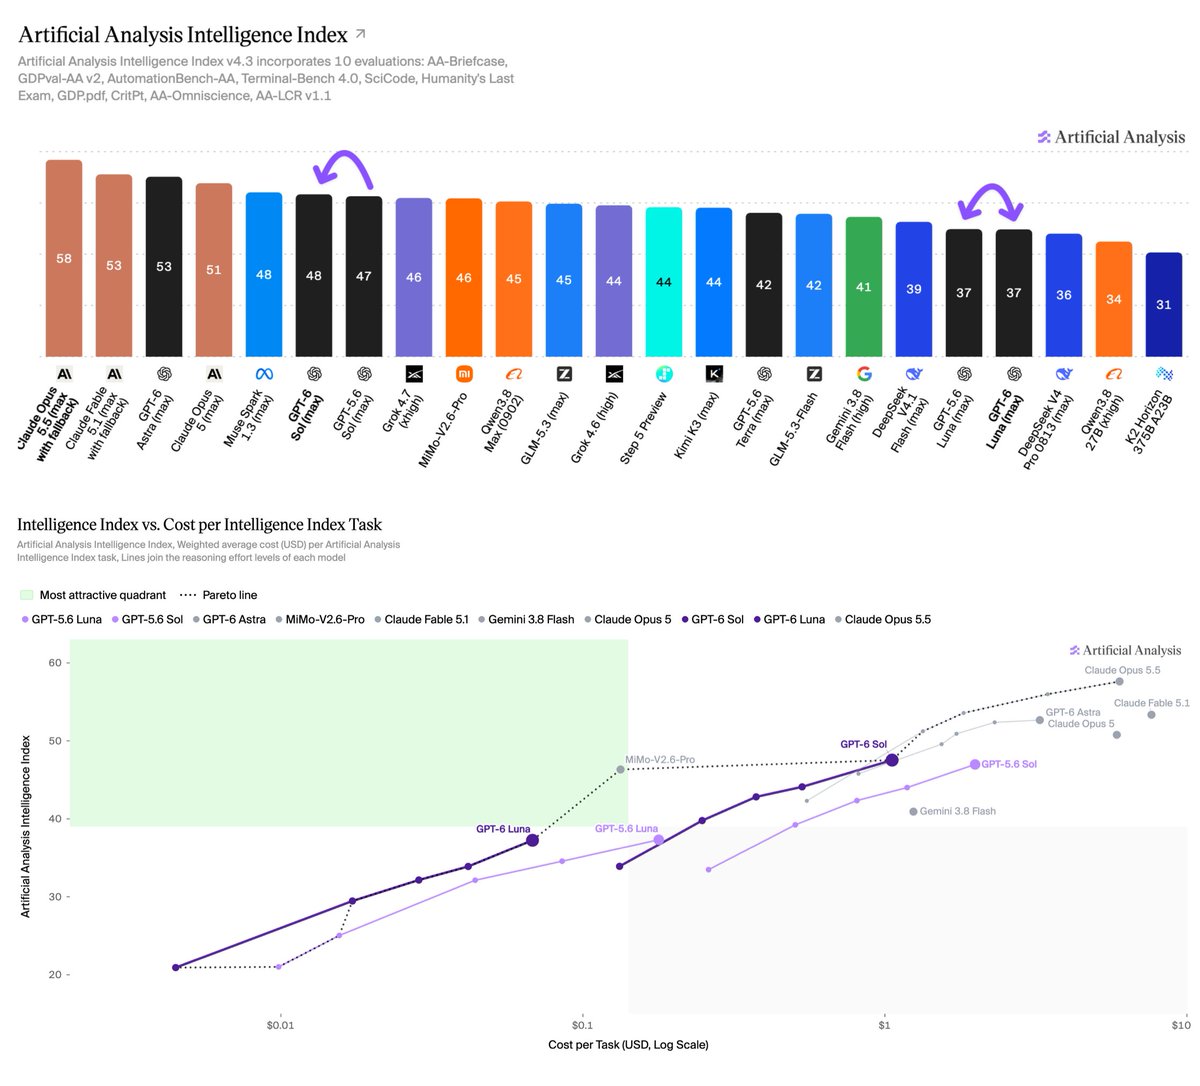
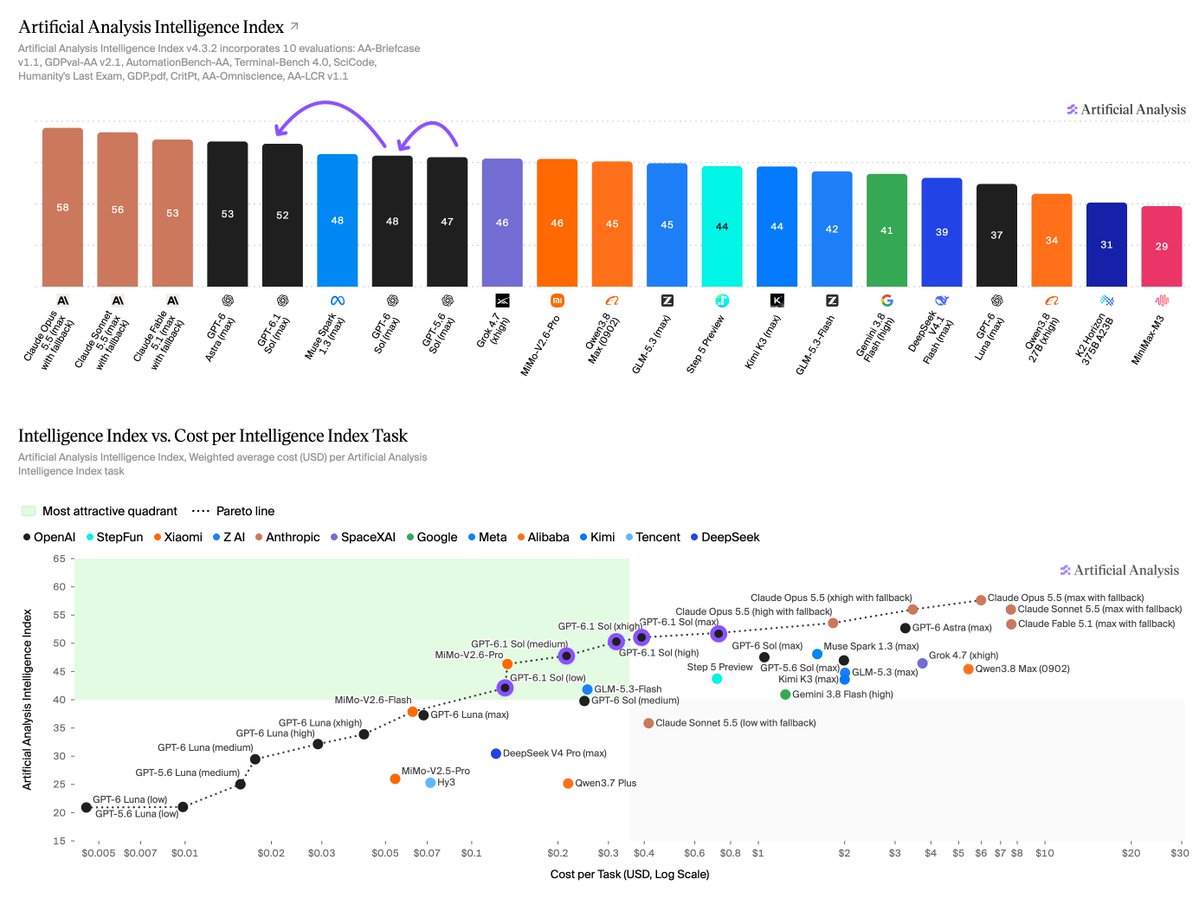
GPT-6.1 Sol pushes the cost efficiency frontier for OpenAI models. OpenAI has also fixed an issue reading multimodal input which improves Intelligence Index results for GPT-6 Luna by 1 point. At max effort, GPT-6.1 Sol costs less than a quarter of GPT-6 Astra per Intelligence Index task ($0.72 vs $3.26). It also costs 31% less per task than GPT-6 Sol ($1.04) and 64% less than GPT-5.6 Sol ($1.99). All effort levels of GPT-6.1 Sol push out the cost efficiency Pareto frontier: for a given level of intelligence, there is no cheaper model. OpenAI also fixed a bug in image encoding for GPT-6 Luna and Sol. GPT-6 Luna (max) has gained a point in the Intelligence Index, with improvement in evals which benefit from visual understanding such as GDP.pdf (2.4pt gain), MMMU-Pro (4.1pt gain), GDPval-AA v2.1 (71 Elo gain), AA-Briefcase (36 Elo gain). GPT-6 Sol shows negligible improvement.

Context
Artificial Analysis, which scores models on its own Intelligence Index of evaluations, says OpenAI's GPT-6.1 Sol costs much less to run on that index than OpenAI's other recent models. According to its post, GPT-6.1 Sol at max effort costs $0.72 per Intelligence Index task. That is less than a quarter of GPT-6 Astra's $3.26, 31% below GPT-6 Sol's $1.04 and 64% below GPT-5.6 Sol's $1.99. The post followed the firm's earlier assessment of the model.
Cost here is quoted per Intelligence Index task, not per , so it depends on how much work the model does on those tasks as well as on its prices. Effort is a setting that controls how much reasoning the model does before answering. Artificial Analysis says every effort level of GPT-6.1 Sol pushes out its cost-efficiency Pareto frontier, the line marking the cheapest option at each level of intelligence. In other words, at the score each setting reaches, there is no cheaper model. The post presents this as a frontier for OpenAI models, and the attached chart that would show the full comparison set was not collected.
The same post reports that OpenAI fixed a bug in how images were encoded for GPT-6 Luna and GPT-6 Sol, which means earlier results for those models were measured while the bug was in place. GPT-6 Luna at max effort gained one Intelligence Index point. The gains came on evaluations that benefit from visual understanding, including 4.1 points on MMMU-Pro and 2.4 points on GDP.pdf. GPT-6 Sol showed negligible improvement.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
Checking sign-in…
Loading comments…