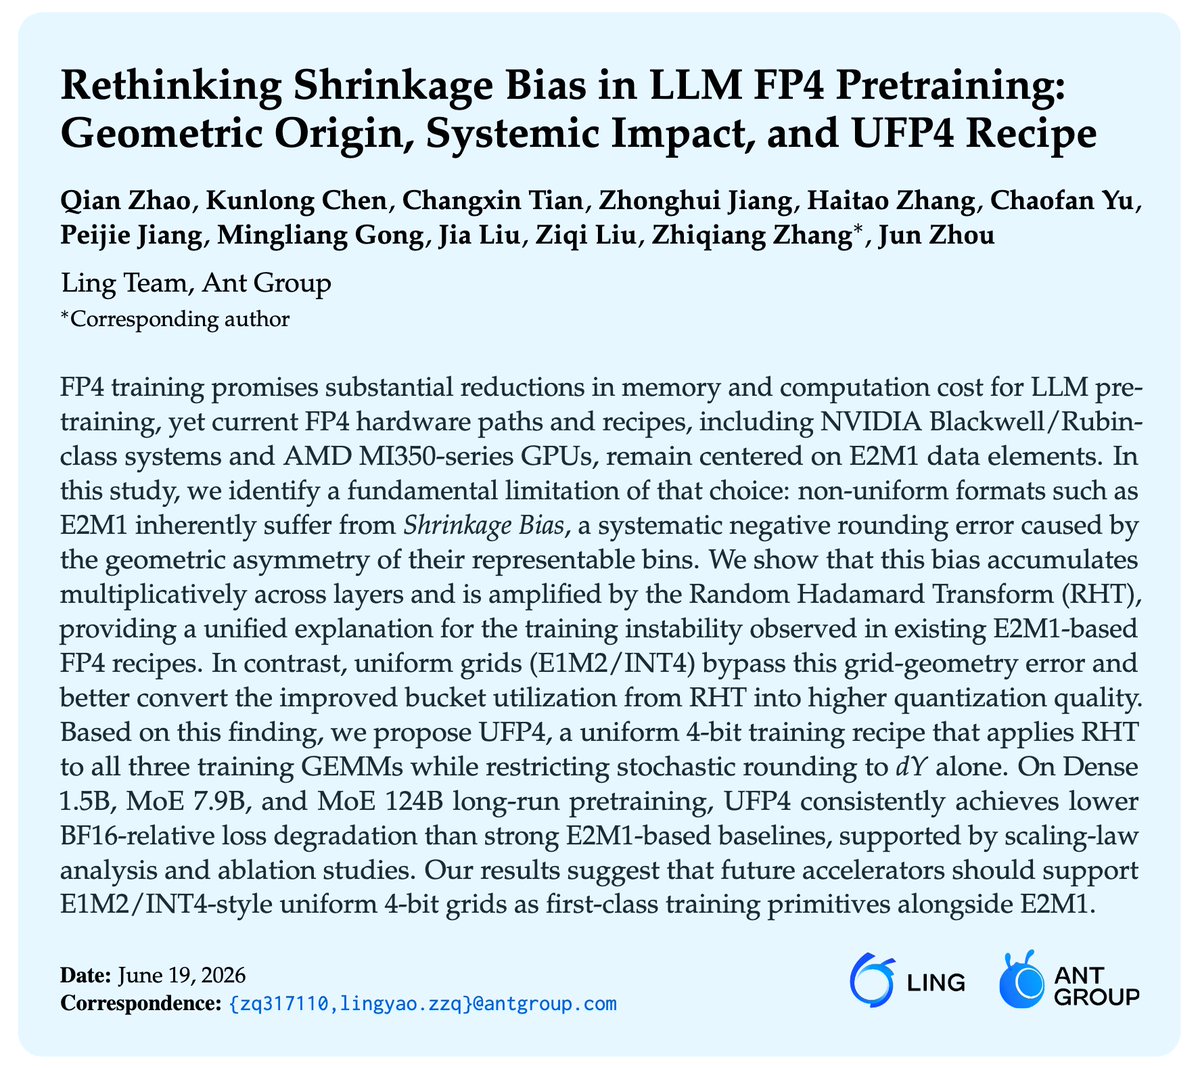
Shows how a frontier lab trades precision against speed per training stage, with NVFP4 running up to 6x faster than BF16 on GB300. This informs practitioners' expectations of training cost and capability trends.
Terms in this piece · Glossary
quantization — Shrinking a model by storing its numbers less precisely — like rounding — so it runs faster and fits on smaller hardware, at a small quality cost.