Service tiers now available on AI Gateway
- Source
- vercel.com
- Author
- Walter Korman
- Date
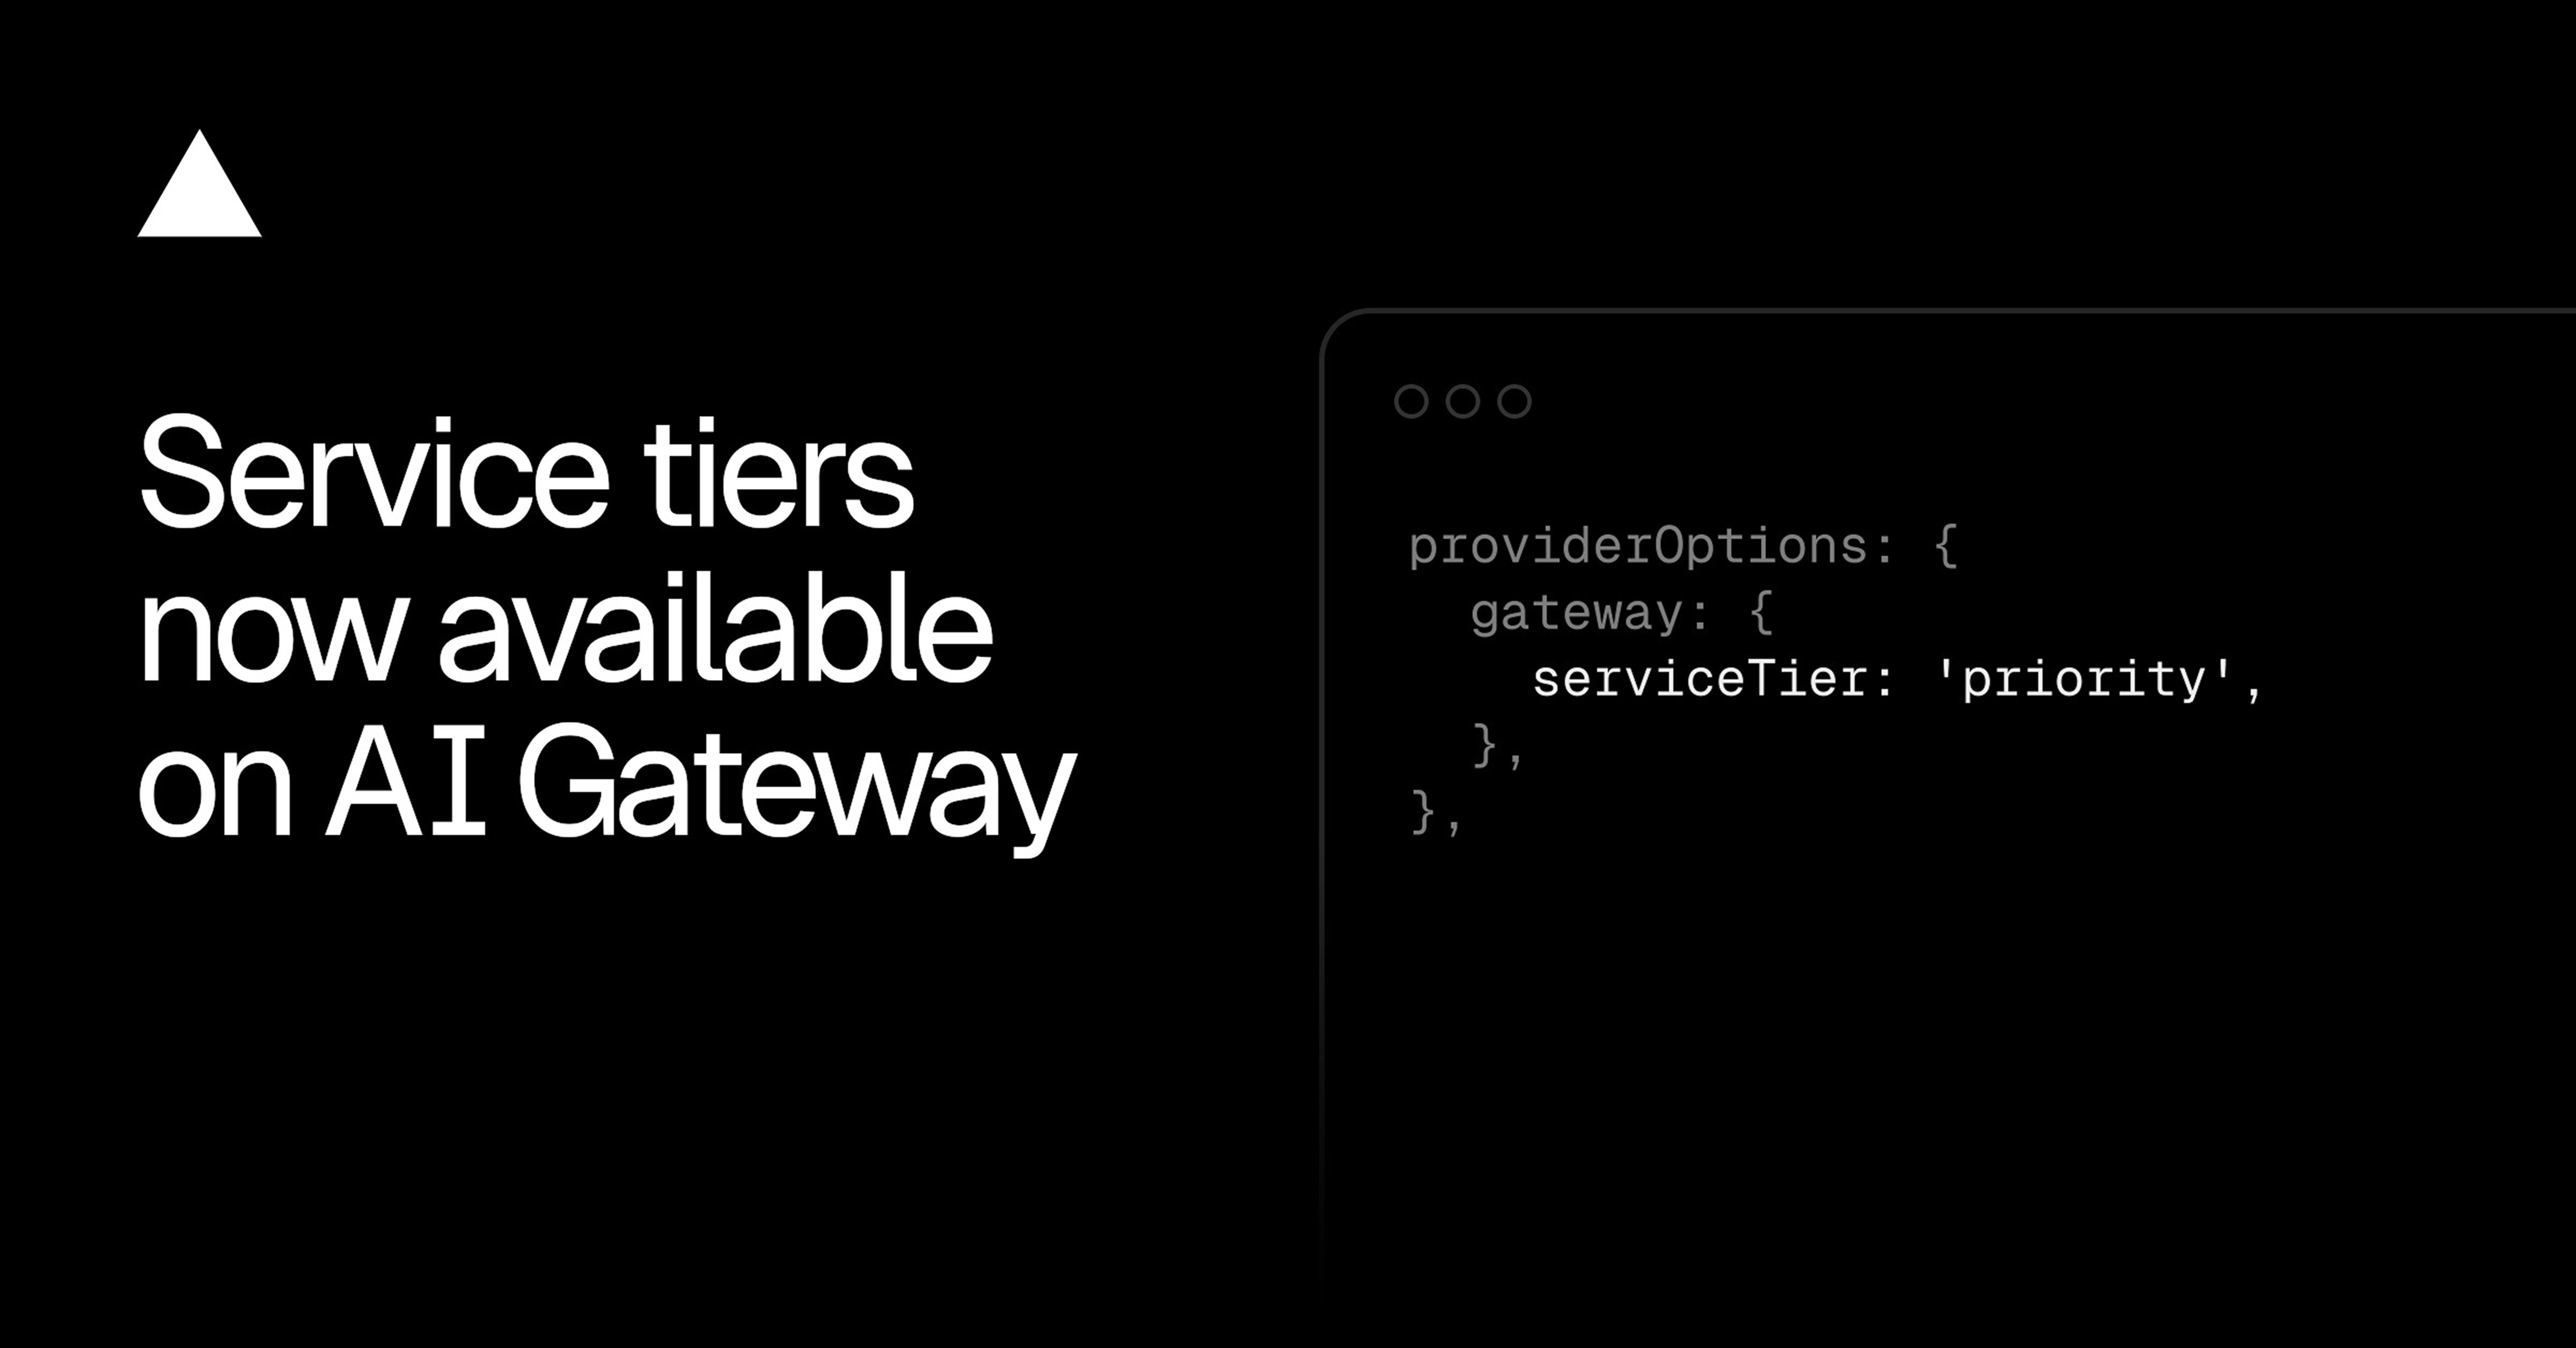
If you route calls through Vercel AI Gateway, you can now trade cost against latency per request — 'priority' for interactive chat, 'flex' for background batch work — without writing provider-specific code, and verify which tier was actually applied from the response metadata before you get billed for it.
- LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.
“Service tiers let you optimize for latency, throughput, and cost per request to match your use case.”
“Pick a faster tier for interactive workloads (less queueing, higher token throughput), or a lower cost tier for background jobs that can tolerate more latency.”
“Service tier is serviced on a best-effort basis: if a tier can't be applied, the request runs on the default tier at the default rate, and only an invalid service tier value fails the request.”
“If a priority request gets downgraded to default capacity, billing reflects the default rate, not the priority rate.”



Checking sign-in…
Loading comments…