LLaDA2.1-flash goes live on ZenMux for hosted API access
- Source
- x.com
- Date

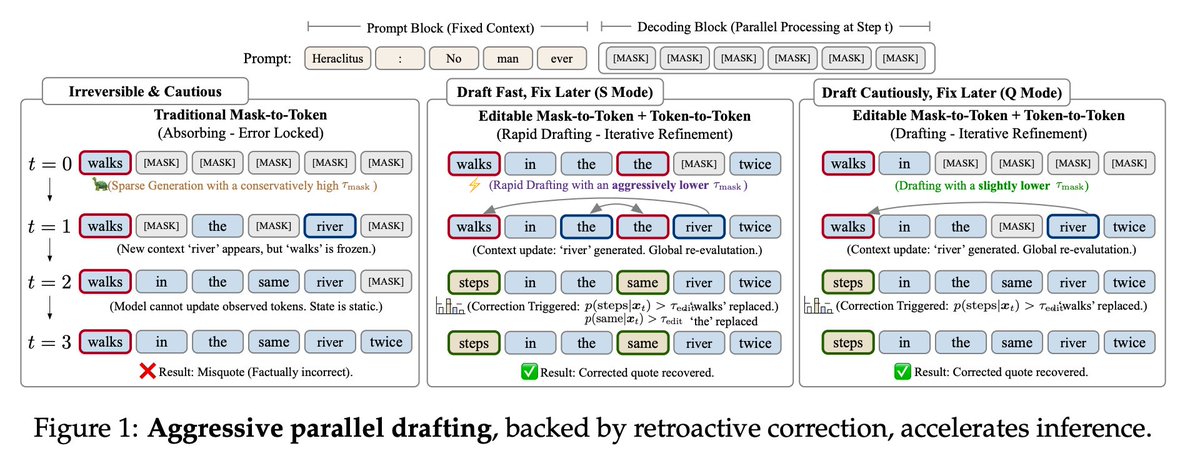
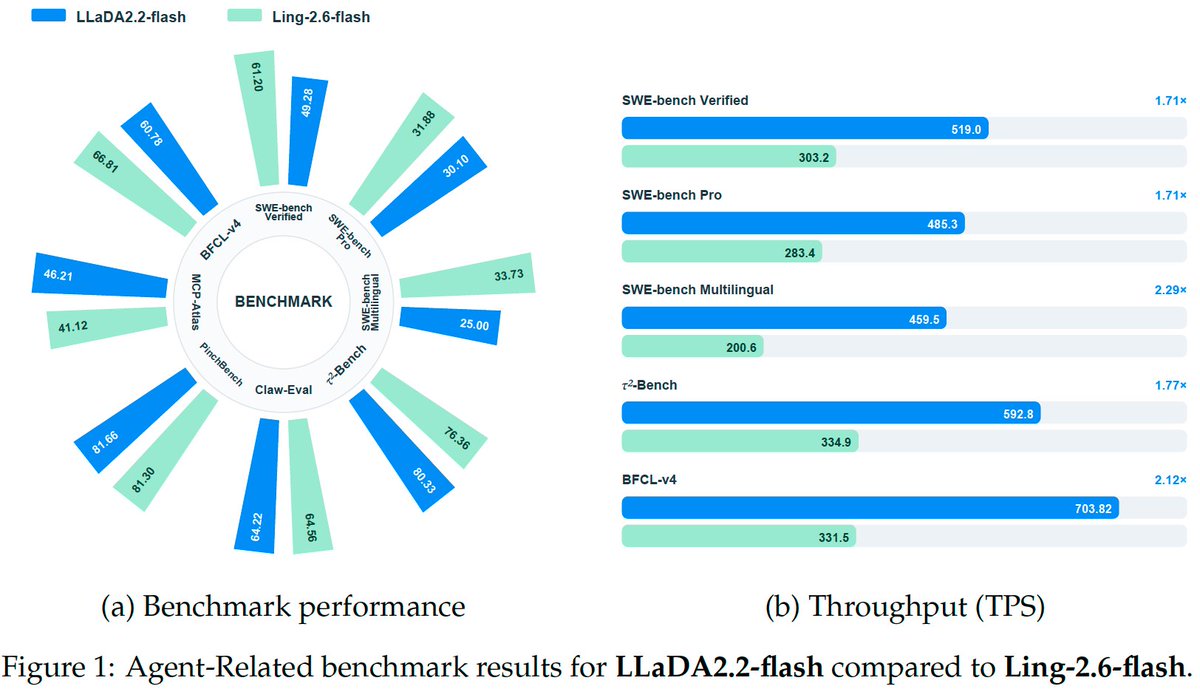
⚡️ 892 tokens/s — our 100B diffusion LLM, LLaDA2.1-flash, is now live on @ZenMuxAI! With Token Editing, LLaDA 2.1 goes from research breakthrough to production-ready speed. Diffusion models just got real. Try it via API or Chat 👇 https://t.co/8ObarWTPio #LLaDA #ZenMux #AI #dLLM https://t.co/zUUROipUAs
Context
A number for a new model architecture means little until you can actually call it the way you'd call any other API. Ant Open Source says its 100B-parameter diffusion model, LLaDA2.1-flash, is now live on the ZenMux platform through both a chat interface and an API, at a stated 892 per second. That makes the token-editing speed claim behind LLaDA2.1, first reported at the model's launch, something a developer can test against their current stack without provisioning their own GPUs.
Checking sign-in…
Loading comments…