LLaDA2.0 Scales Diffusion Language Models to 100B With Open Weights
- Source
- x.com
- Date

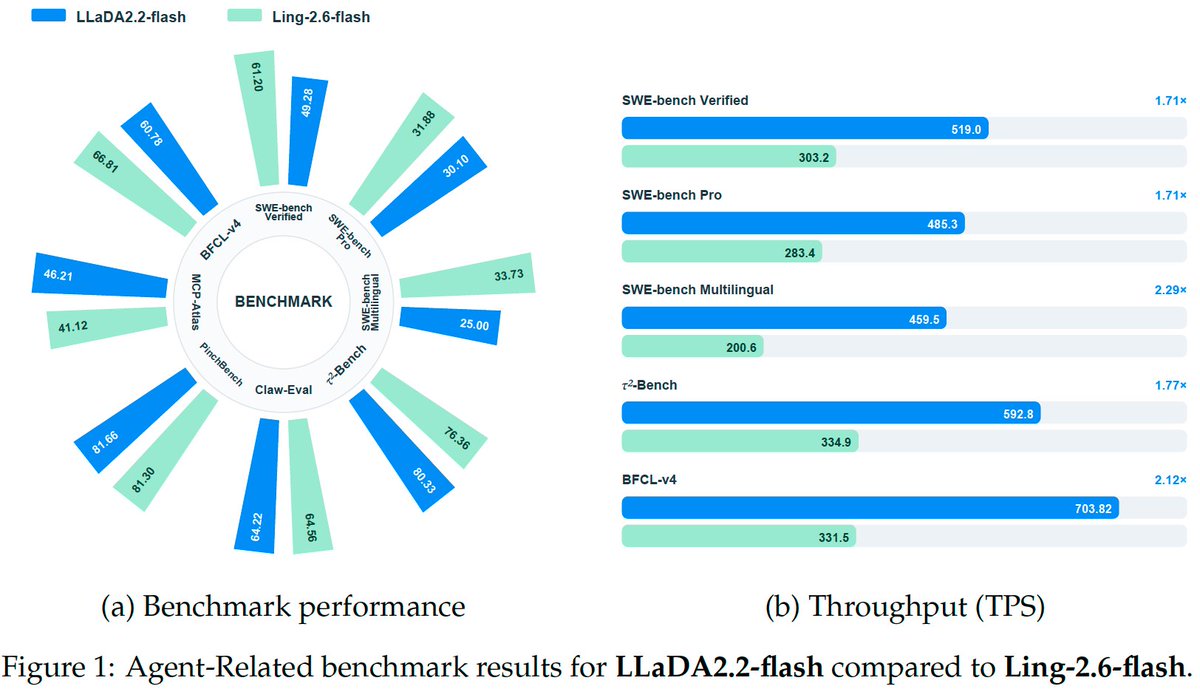
🧬 Introducing LLaDA2.0, for the first time scaled to 100B, as a Discrete Diffusion LLMs (dLLM)! Featuring 16B (mini) and 100B (flash) MoE versions. With 2.1x faster inference than AR models and superior performance in Code, Math, and Agentic tasks, we prove that at scale, Diffusion is not just feasible—it's stronger and faster. 🌊 #AI #LLaDA #Diffusion #OpenSource #dllm
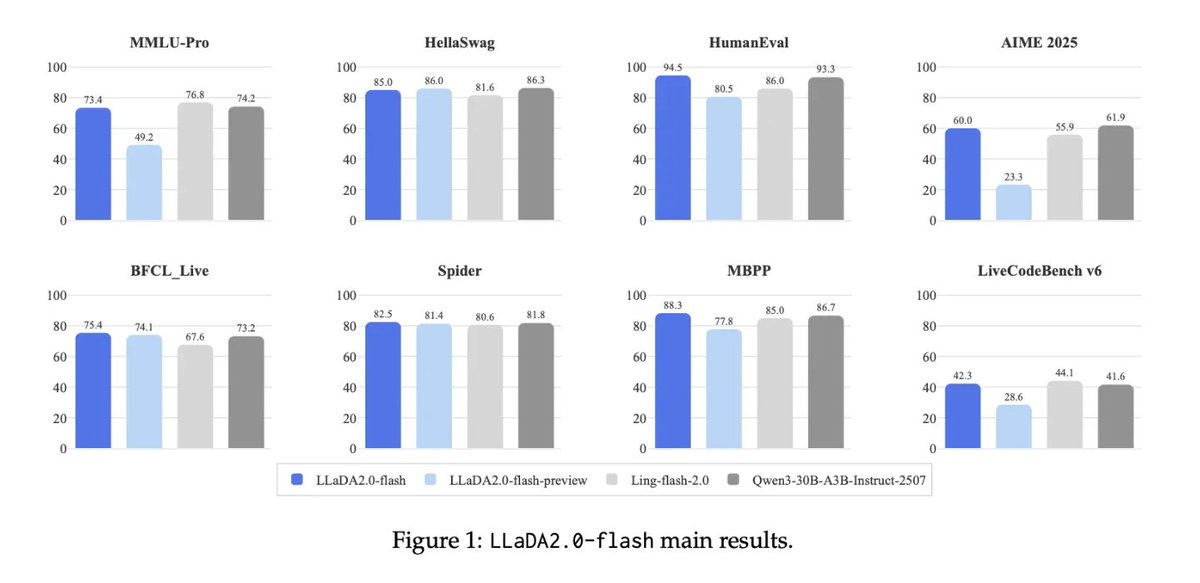
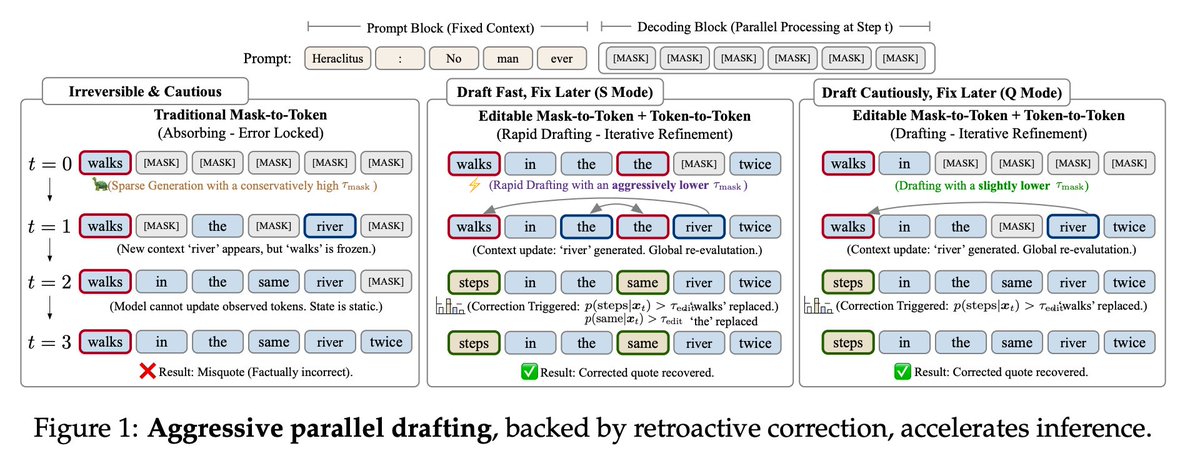
Why LLaDA2.0 can be a game-changer? 🚀 100B Scale: The largest dLLM to date. Declared its potential to scale (finally!). ⚡ Blazing Speed: Achieves 535 tokens/s (2.1x vs AR) via parallel decoding, merged in SGLang. 🔄 Cost-Effective: Specific training strategies allow seamless knowledge transfer from existing AR models. 🔍 Fully Open Source: Full opened weights & code for both 16B/100B available now on HuggingFace.
Core Tech - WSD Strategy How did we bridge the gap between AR and Diffusion? Introducing Warmup-Stable-Decay (WSD): 🔹 Warmup: Gradually increase block size, transitioning from AR mode to full-sequence context. 🔹 Stable: Train on massive corpora with Masked Diffusion to master bidirectional understanding. 🔹 Decay: Shrink block size (e.g., to 32) to optimize KV Cache usage and inference efficiency.

Post-Training Alignment Stack Conversion alone doesn't create a usable assistant. Let's see what we did through post-training for LLaDA2.0: 👨🏫 Supervised Fine-Tuning: Complementary masking ensures 100% token utilization; mask ratio bandwidth stabilizes convergence 🎖️ DPO over ELBO: Direct Preference Optimization reformulated using Evidence Lower Bounds, trained on 1.5M preference pairs 🎯 Confidence-Aware Training: Auxiliary loss sharpens predictions for efficient parallel decoding (threshold 0.95) 🚀 Fine-tuning framework, dFactory: https://t.co/qBXcOZI6wX
Context
Most large language models write text one token at a time, left to right. Diffusion language models start from masked positions and fill in several at once. Ant Open Source, publishing for InclusionAI, introduces LLaDA2.0 as the first discrete diffusion language model scaled to 100 billion parameters, alongside a 16-billion-parameter version, both . It reports 535 tokens per second through parallel decoding merged into SGLang, 2.1 times an autoregressive baseline that the post does not specify.
The training recipe, Warmup-Stable-Decay, is said to allow knowledge transfer from existing autoregressive models: block size grows during warmup to move from autoregressive mode toward full-sequence , the model trains on large corpora with masked diffusion, then block size shrinks (for example to 32) to make use efficient. Post-training includes supervised fine-tuning and a preference-optimization method reformulated for diffusion, trained on 1.5 million preference pairs. The post claims superior code, math and agentic performance without giving scores, so that claim is unverified here.
- mixture-of-experts — A model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
- KV cache — The memory a model keeps about text it has already read, so generating each new token doesn't require reprocessing the whole conversation.
- open weights — A model whose trained parameters are published for anyone to download and run — unlike API-only models you can access but never possess.
Checking sign-in…
Loading comments…