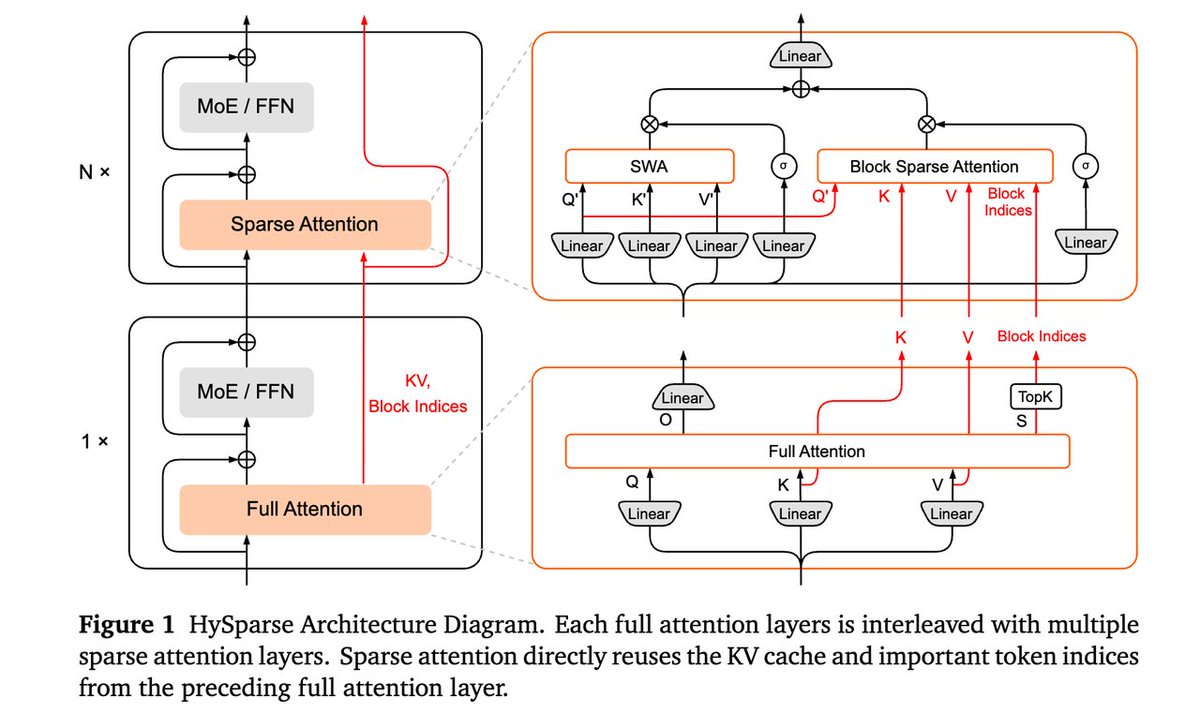
Tencent's Hy4 preview has a documented deployment path through vLLM, software for serving language models. The serving project's quoted announcement explains how Hy4 handles long inputs: although its context windowThe maximum amount of text a model can consider at once — its working memory for the current conversation or task.Full definition → can reach roughly one million text tokenThe chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.Full definition →, each attentionThe mechanism that lets a model weigh which earlier words matter for the word it's currently processing — the core operation of a transformer.Full definition → query selects only 2,048 positions to examine.
The same announcement says most layers reuse a selection index computed elsewhere in the model. This distinguishes the amount of text the model can accept from the amount each attention operation processes. The serving support makes that architecture deployable; it does not establish that every detail in a million-token input will be recalled reliably.
Terms in this piece · Glossary
context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
attention — The mechanism that lets a model weigh which earlier words matter for the word it's currently processing — the core operation of a transformer.

 postExplorationBench tests how models explore, with exactly verifiable grading
 postHy Image3.5 preview is live. 🚀 Professional-grade image generation, +30% win…
 postTencent Hunyuan's EvolveScaler trips up frontier models on evolving facts
 postTencent Hunyuan open-sources AuK, a unified speech generation and editing model