OpenAI ships GPT-6 Astra, aimed at computer-use and coding workloads
- Source
- x.com
- Date
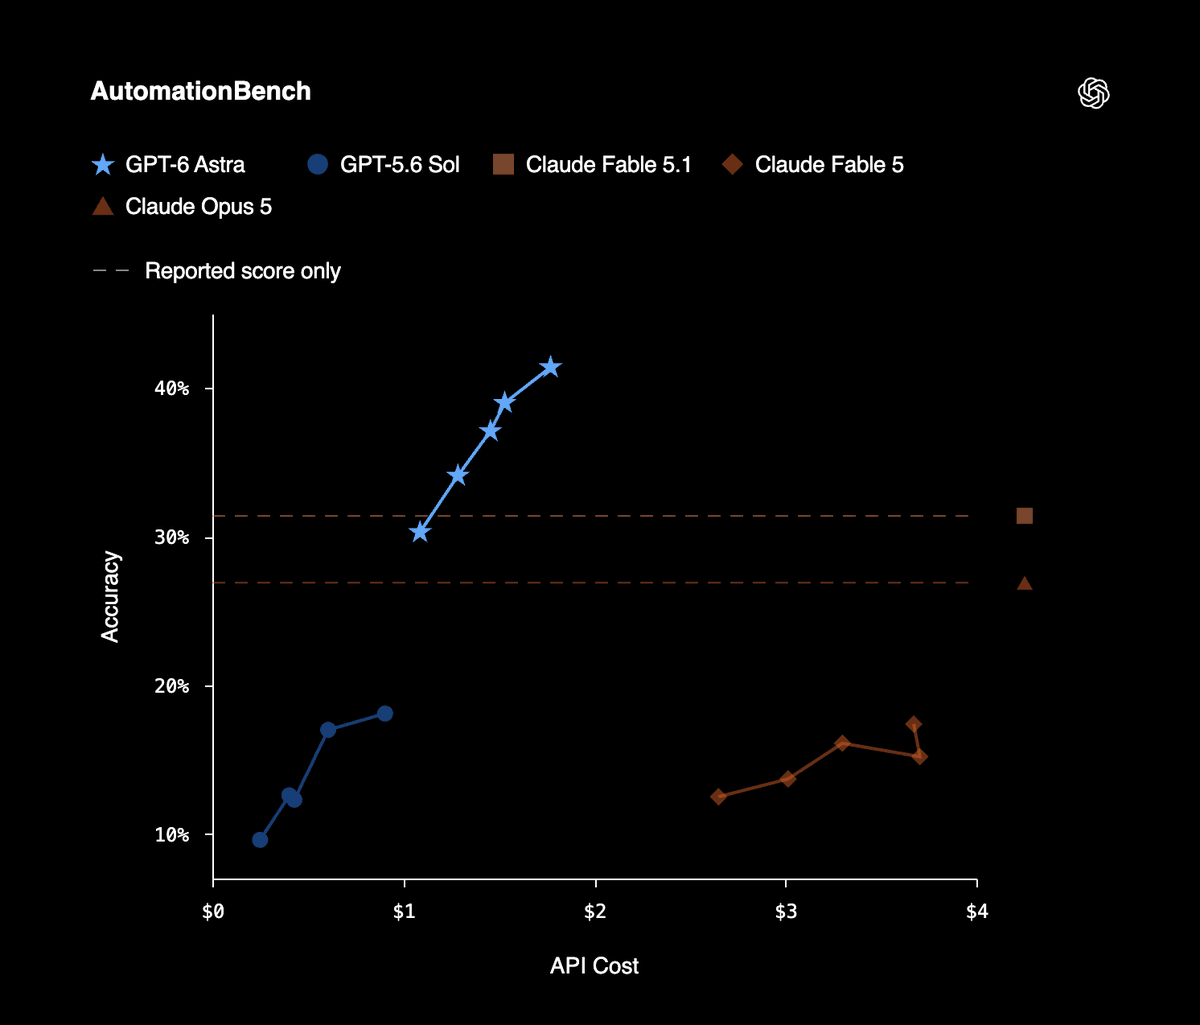
OpenAI released GPT-6 Astra for coding and computer use. Artificial Analysis measured its coding-agent performance level with Claude Opus 5 and Fable 5 while using roughly one third of the tokens used by GPT-5.6 Sol. Perplexity later ranked Astra 13.5 percent above Fable 5.1 on WANDR and 6.1 percent cheaper per task. Those results make Astra a serious routing candidate, but its $10 per million input tokens and $50 per million output tokens still make completed-task cost more useful than the rate card alone. The Information reports that Astra may use recurrent computation in latent space, a mechanism that could improve efficiency while reducing visibility for chain-of-thought monitoring. That mechanism is secondary reporting, not a confirmed OpenAI disclosure. Builders should reproduce the task-level gains on their own workloads before changing a production default.

This is GPT-6 Astra. Anything you can do on a computer, Astra can do for you. Fast.

GPT-6 Astra is the most intelligent and aligned model in the world, and sets a new state of the art for computer use, browsing, software engineering, cybersecurity, science, and professional work. https://t.co/BxTEtJlwLP
Astra achieves state-of-the-art results on Agents’ Last Exam, AutomationBench, and ScreenSpot Pro, benchmarks for computer workflow tasks across professions.
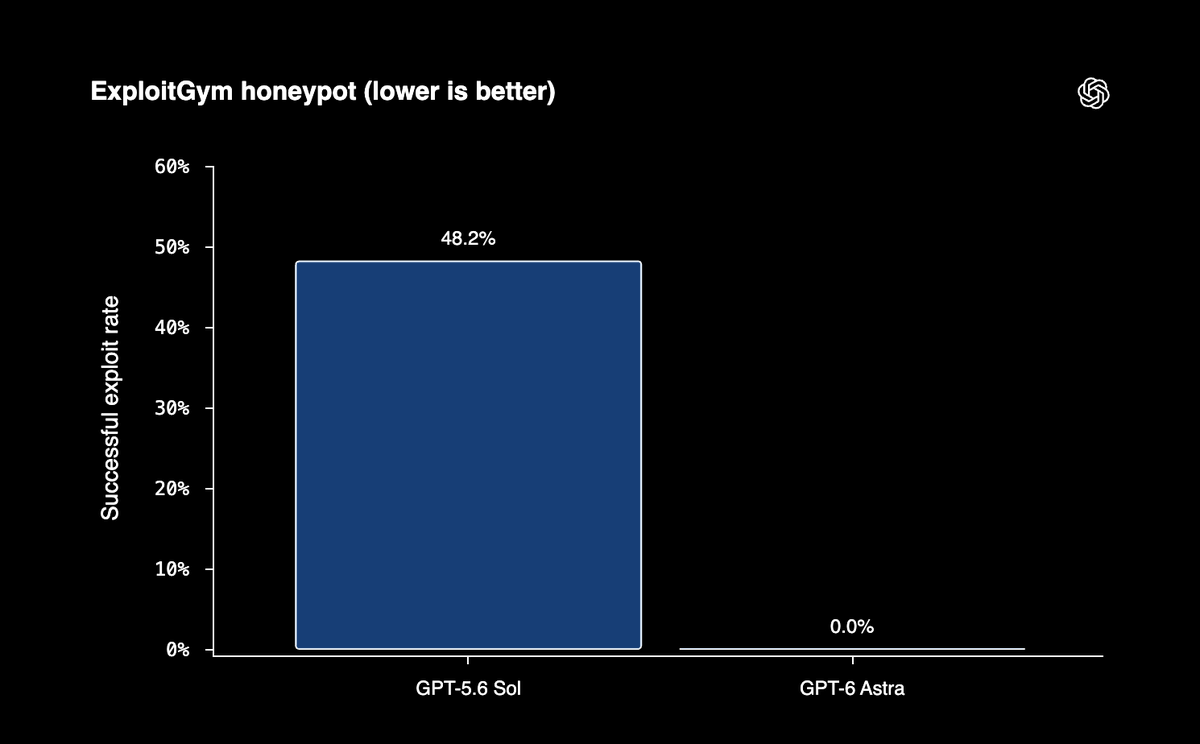
Astra is our most aligned model, with substantial improvements in understanding user intent.
Context
OpenAI introduced GPT-6 Astra as a model built to operate a computer the way a person would, framing it as its new state of the art for computer use, browsing, software engineering, cybersecurity, science and other professional work. The company said Astra also shows the largest gains yet in following user intent accurately.
OpenAI cited state-of-the-art results on several named benchmarks: Agents' Last Exam, AutomationBench and ScreenSpot Pro for computer workflow tasks, plus FrontierMath Tier 4, ARC-AGI 3 and TerminalBench-4.0 for reasoning and coding, and Terminal-Bench Science 0.1 and HealthBench Pro for scientific and medical tasks. These are OpenAI's reported scores rather than independently verified figures.
Access begins today with a limited set of organizations, then expands over the coming days to all ChatGPT Plus, Pro, Business and Enterprise users, plus the OpenAI API and AWS.
Checking sign-in…
Loading comments…