How Specializing the Vocabulary of SLMs Can Cut Inference Cost by 77% in Real Applications
Source
huggingface.co
Date
Why it matters
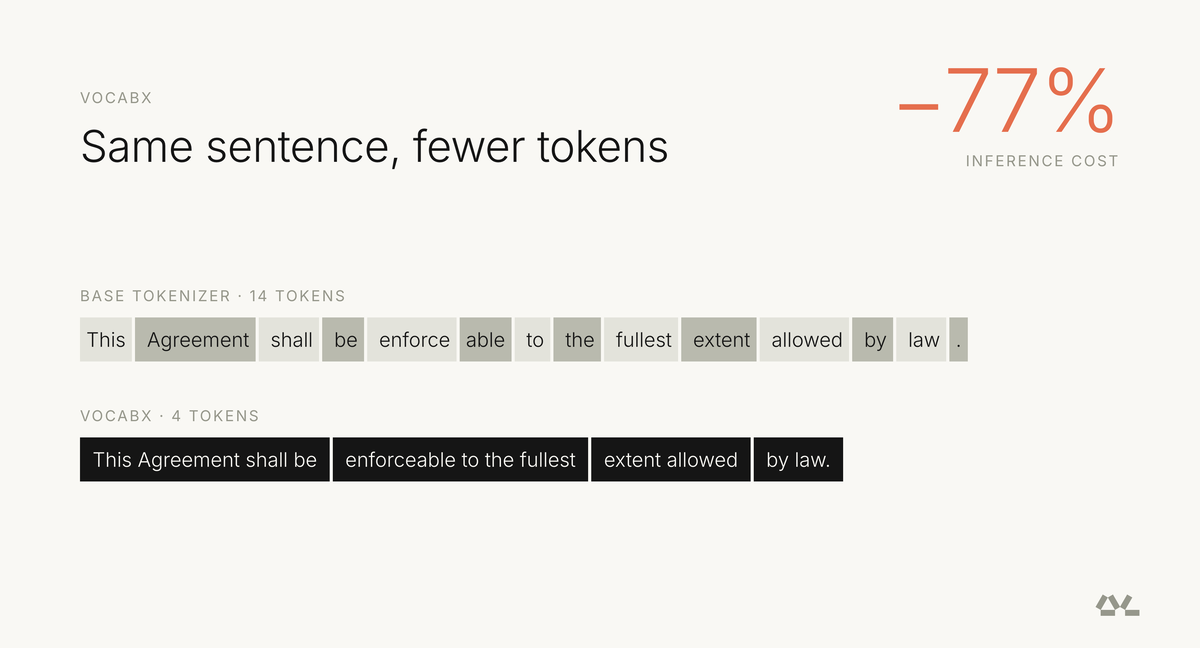
Fine-tuned small models inherit a general vocabulary that splits domain output into many tokens. Choosing vocabulary by token cost rather than frequency reportedly cut serving cost 77% on a production grader, a lever to check before spending on hardware.
Key takeaways · AI-distilled
Dharma-AI rebuilt the tokenizer of a fine-tuned Qwen3-4B Portuguese essay grader, keeping base model, data and recipe fixed. Average response length fell from 350 to 101 tokenThe chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.Full definition → and measured inferenceRunning a trained model to get answers — the phase where AI is actually used, as opposed to trained.Full definition → cost fell 77%, while its bench score rose from 0.703 to 0.810.
VocabX picks tokens by serving cost, not frequency: each saved token is weighted by where it appears. In their grader a generated token cost 7.4x an input token, because decode is memory-bound, so shrinking output is worth far more than shrinking input.
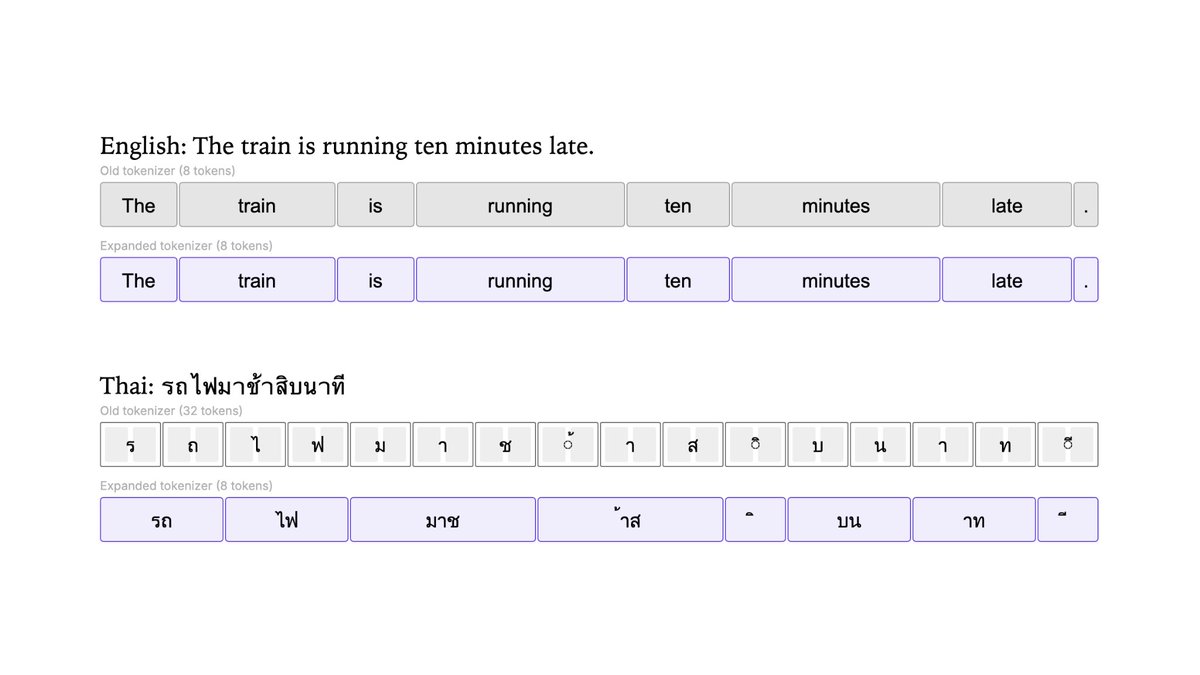
Besides sub-word merges, it adds macro tokens for whole repeated spans such as JSON envelopes, found by five miners. The output layer shrank from about 152,000 to 65,000 rows, which also cuts per-token work since the LM head reads every row at each step.
Fusing each grade with its surrounding JSON into one macro dropped quality to 0.689. Giving the grade its own token cost two extra tokens yet scored 0.810 and was cheaper, so compression should not swallow the decision the model exists to make.
Across five public domains and three model families, VocabX compressed more than FVT, multi-word tokenization and in-place BPE in all 15 pairings, by 1.2-9.3 points. The figures come from a paper still under review and may change.
Terms in this piece · Glossary
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.