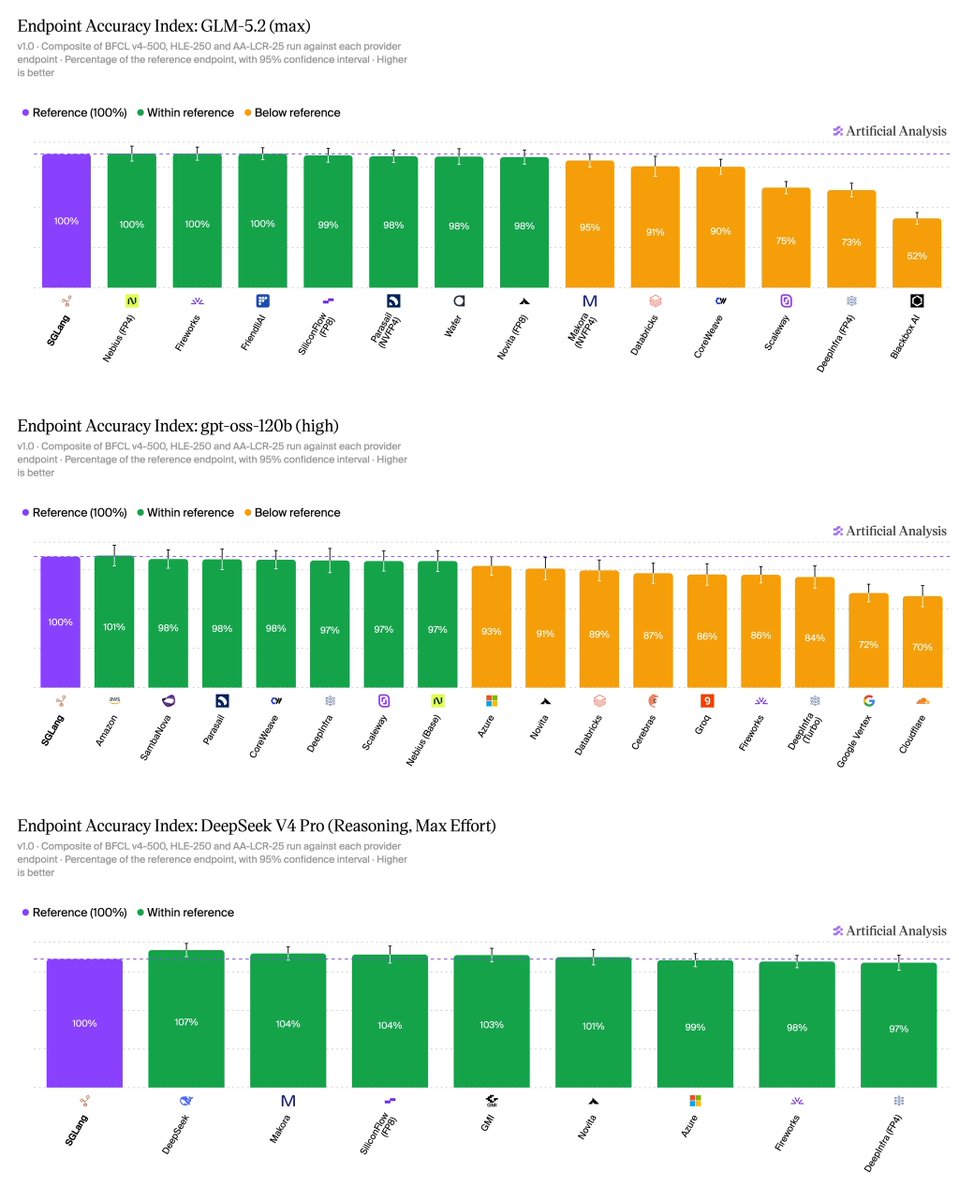
Providers quantize, cap outputs and ship bugs, so the same model can score differently by endpoint. This index shows which endpoints fall below a self-hosted reference on tool useA model's ability to call external functions — run code, search the web, edit files — instead of only generating text.Full definition →, reasoning and long context windowThe maximum amount of text a model can consider at once — its working memory for the current conversation or task.Full definition →.
Key takeaways · AI-distilled
Artificial Analysis benchmarked 103 serverless endpoints for six open-weights models against self-hosted references on the labs' official weights: 79 were statistically in line with the reference and 24 scored below it.
It sorts the below-reference causes into four groups: output tokenThe chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.Full definition → caps that cut off long reasoning, endpoints that reason less at the same settings, mishandled tool calls, and request timeouts or streams that end before the model finishes.
Tool-call formatting alone can sink an endpoint: one Kimi K3 endpoint that reused tool call IDs across turns scored 42.1% on BFCL-500 against 55.2% for the reference, while staying within 2 points on the other two evaluations.
FP4 serving held up in these results: all three GLM-5.3 Flash endpoints serving FP4 weights and five of the six GLM-5.3 FP4 endpoints were statistically in line with their FP8 references.
Version 1.1 raises AA-LCR-25 repeats from 10 to 25 and corrects two answer keys, narrowing its average 95% confidence interval from ±4.7 to ±2.6 points. Artificial Analysis says v1.0 and v1.1 scores are not directly comparable.
Terms in this piece · Glossary
context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
tool use — A model's ability to call external functions — run code, search the web, edit files — instead of only generating text.
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.